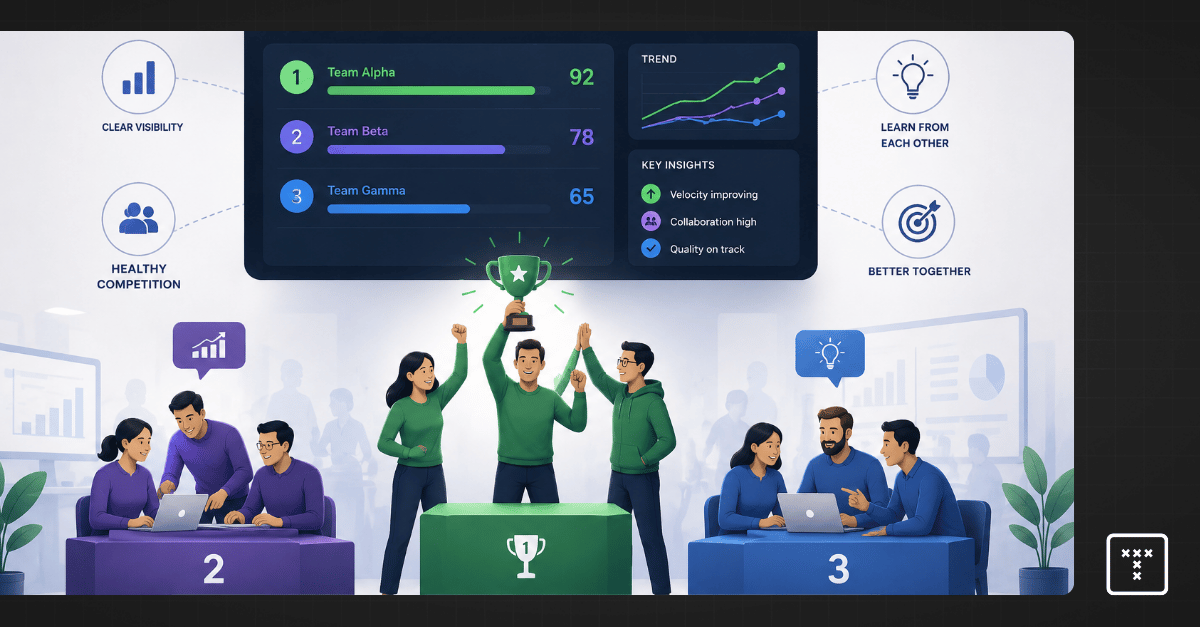
Fostering a healthy competitive culture within organizations is beneficial and essential for success. This principle holds across all departments and businesses, regardless of size or industry. In every group, performance levels will naturally vary among members. However, creating a positive environment where individuals are motivated to excel and equipped with the necessary tools and infrastructure can transform individual outcomes and overall business success.
1. Tech Stars: In the fast-paced world of technology startups, a leading software development company implemented a quarterly hackathon encouraging teams to innovate new product features. The winning team received a prize and had their feature fast-tracked into development. This initiative not only spurred a friendly rivalry among teams but also led to significant product advancements, boosting team morale and market competitiveness.
2. Sales Stars: A multinational retail corporation introduced a monthly sales leaderboard highlighting top regional performers. This was complemented by a peer recognition program where employees could nominate colleagues for exceptional customer service or teamwork. These measures increased sales figures and fostered a culture of mutual respect and collaboration, with employees feeling more valued and connected to the company’s goals.However, creating such an environment is not without its challenges. It requires a meticulous approach to collecting data, analyzing it, and implementing processes and tools that effectively leverage this information.
With TargetBoard, you can access a comprehensive suite of tools that empower you to understand and compare performance across various lines such as Teams, Products, Services, Markets, and more. TargetBoard simplifies showcasing and interpreting performance data, making it easy to see how your results stack up against the past or other groups. This clarity enables you to learn from successes and apply these lessons across the board, thereby elevating the entire organization.
1. Immediate Implementation: Get everything you need from day one to start making informed decisions.
2. Comprehensive Comparisons: Easily compare different aspects of your business to identify strengths and areas for improvement.3. Shared Success: Foster an environment where learning from each group's successes becomes a pathway to collective improvement.
In conclusion, by integrating TargetBoard into your strategic toolkit, you ensure that your organization remains competitive and thrives in an ever-evolving business landscape. Unlock the full potential of your team and lead your business to new heights with TargetBoard.
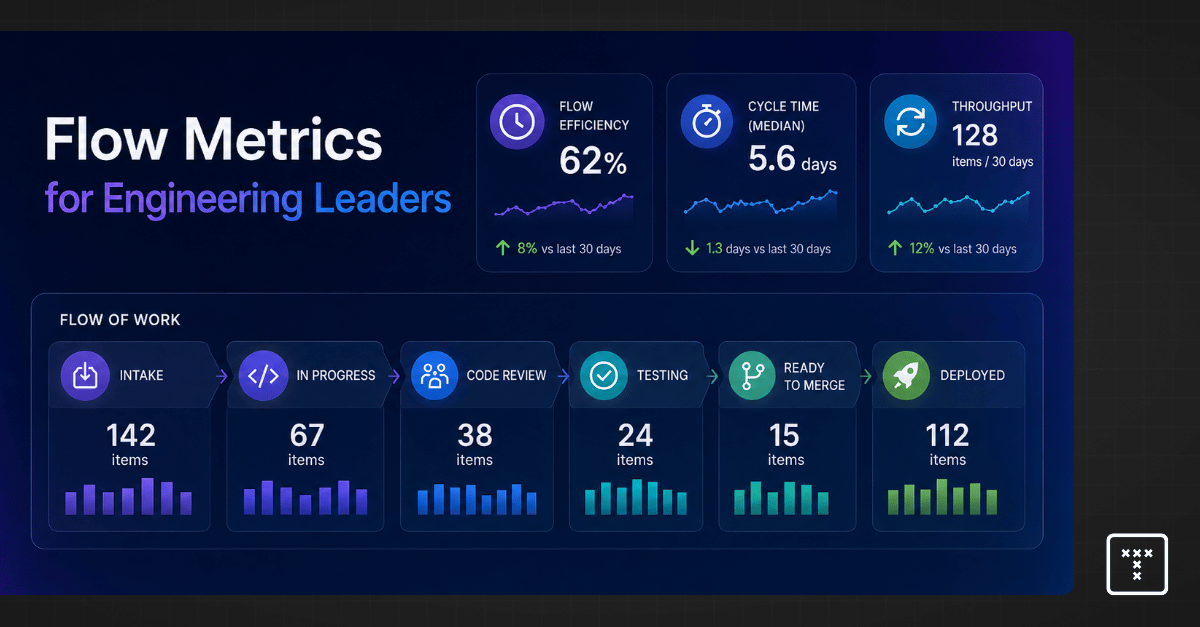
Understanding flow metrics means looking at how value moves from an initial idea to time-to-revenue. These metrics track work across the end-to-end value stream to help leaders spot hidden blockages before they impact delivery predictability. They provide clear signals about where workflow friction occurs, so you can diagnose system stress instead of blaming individual developers.
The 4 key flow metrics provide a foundational view of delivery health and system capacity.
The flow framework metrics defined by Dr. Mik Kersten offer a more specific lens for analyzing engineering performance signals.¹
Teams shipping 50+ deployments a week boast excellent DORA scores while struggling with terrible software delivery predictability. A team might deploy multiple times a day, yet their overall flow load is massive and critical features are constantly delayed.
This happens because DORA relies on point-in-time metrics that measure output events rather than the continuous progression of work across the development lifecycle. DORA shows you how fast you ship, while flow metrics reveal how work actually moves. Relying solely on speed creates proxy metrics limitations that hide the true cost of context switching.
DORA metrics focus purely on deployment speed and operational stability, originally established by the DevOps Research and Assessment team.²
DORA metrics and flow metrics act as complementary engineering performance signals. DORA measures the final mechanical steps of software delivery, focusing entirely on speed and stability. Measuring flow focuses on the entire value stream, tracking how work moves through cross-team dependencies from planning to execution.
When you combine both, you can see the delivery tradeoffs teams make. For example, a team might inflate deployment frequency by shipping tiny updates while larger feature requests rot in the backlog. Flow metrics expose these behaviors, giving leaders the context needed to make confident capacity decisions.
Identifying execution bottlenecks requires shifting from passive observation to active capacity allocation. When you spot workflow friction, you need a systematic approach to clear it and drive continuous improvement.
One of the most common bottlenecks occurs during the code review process. When you analyze wait time vs. active time, you often find that pull requests sit idle for days before receiving a review. This delay usually stems from subjective review decisions or massive PR sizes that intimidate reviewers.
Tracking Work Item Age helps you spot these stalled reviews early, allowing you to step in and facilitate delivery risk mitigation. By addressing code review risk directly, you prevent minor delays from snowballing into missed release dates. Tracking a specific pull request's age recently helped one engineering team prevent a critical release delay by highlighting a PR stuck in an endless, subjective review loop.
High Work in Progress directly correlates with reduced throughput. When Flow Load spikes, teams spend more time context-switching than actually writing code. You need system-level visibility to enforce strict WIP limits and stabilize the delivery pipeline.
AI tools allow developers to generate code faster than ever, yet this speed often creates throughput anomalies. You might see a massive increase in tickets closed, so you assume productivity is up. This artificial output spike often hides a surge in AI-generated code complexity.
Reviewers simply can't keep up with the volume. This bottleneck tanks flow efficiency and causes massive rework churn. You end up with a pipeline stuffed with code that is fast to write but incredibly slow to review, test, and merge.
Cycle time and throughput act as trailing indicators. By the time they show a slowdown, the damage is already done. AI accelerates the creation of new features, but it also accelerates technical debt accumulation. When developers push complex AI-assisted pull requests, they introduce hidden complexity into the codebase.
Over time, your team spends more time fixing bugs than building features. This shifts your capacity from value demand to failure demand, slowly strangling your delivery pipeline. You need visibility into code complexity before it merges, or your future delivery predictability will collapse.
Flow metrics are incredibly useful for spotting system stress, but optimizing for them in isolation creates a massive blind spot. Frameworks provide signals. They do not provide understanding. A metric dashboard might tell you that cycle time is up, but it can't explain that three high-complexity AI-generated pull requests are stalled in code review.
When you rely on data silos and fragmented reporting, executive decision-making becomes a guessing game. Leaders see the numbers shift but can't explain why, which erodes trust across the organization. To fix this, you must bridge the gap between static measurement and operational intelligence.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects cross-system data to continuously analyze performance, translating raw signals directly into decision-centric execution actions.
You can't achieve predictable delivery by simply staring at charts. True execution alignment requires connecting your planning data directly to your codebase. When you rely solely on passive measurement across the software delivery lifecycle, you risk optimizing the wrong things. Some teams even game throughput by breaking tickets into artificially small chunks without actually improving value delivery.
The mathematical realities of Little's Law dictate that cycle time equals work in progress divided by throughput. If you allow work in progress to expand indefinitely, cycle time mathematically must increase. You must shift from reporting on the past to predicting the future, using active intelligence to manage flow load and guide your daily operations.
Developer experience defines the operational reality of how engineers interact with your technical infrastructure to build and ship code. It measures the level of friction in daily workflows and directly impacts software delivery performance. A poor dev experience means your team spends more time fighting internal systems than solving actual business problems.
Board members and C-suite leaders often mistakenly treat what is developer experience as a cultural or HR initiative focused on office perks. You must treat developer experience as the UX for your engineering team. If the internal systems are slow or siloed, your team can't ship predictably.
You might notice a high-complexity pull request sitting in review for multiple days. That isn't a motivation problem. It's pure organizational drag caused by poor system design.
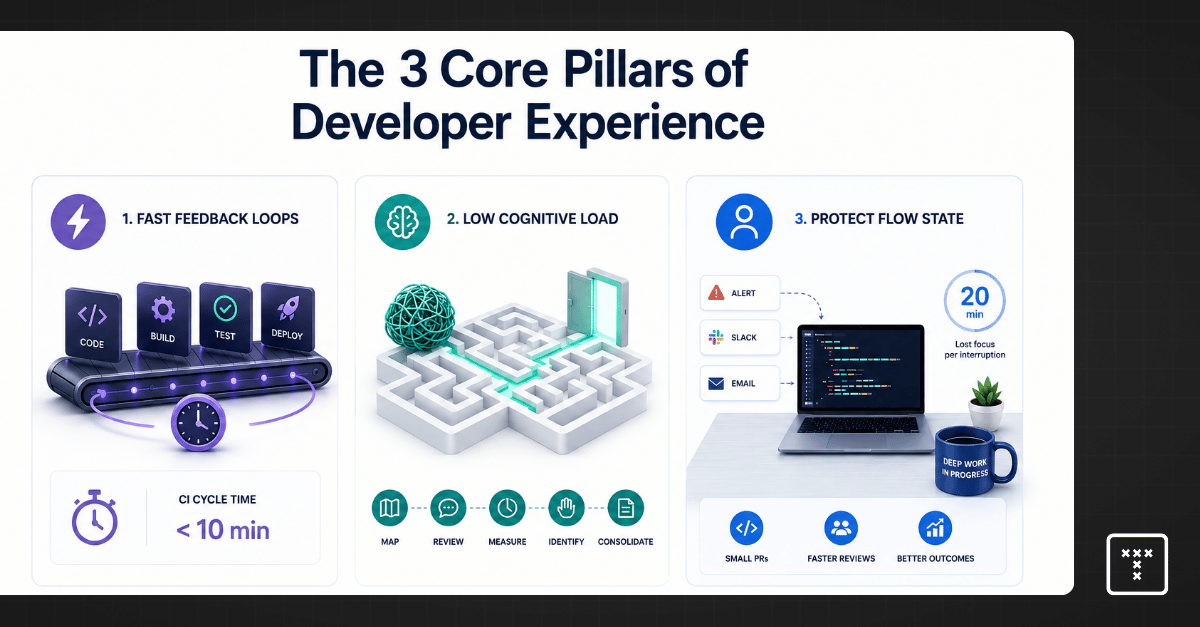
A good Developer Experience (DX) means your team can focus on execution without hitting hidden bottlenecks. Engineering effectiveness drops the moment developer friction increases. You can evaluate the health of your environment by looking at three specific operational pillars that dictate how work actually flows through your systems.
Fast feedback loops are critical for maintaining engineering momentum. Engineers need to know immediately if their code breaks the build. Long build and deployment times force developers to wait, so they lose context and switch to other tasks.
You must optimize your continuous integration and delivery pipelines to return results in minutes. Automated environment setups eliminate manual configuration errors and reduce wait times from hours to minutes. If your continuous integration cycle time exceeds ten minutes, you are actively burning engineering capacity and delaying your release schedule. Fast cycle times are usually a healthy signal, but you must ensure they don't indicate a lack of proper code review.
High cognitive load means your engineers spend more time deciphering complex architecture than writing functional code. Systemic complexity grows silently, and legacy system navigation quickly becomes a major bottleneck for new and existing staff. You can audit this burden using a structured approach to uncover hidden inefficiencies.
Engineering requires deep focus to achieve a productive flow state. Context switching destroys that focus instantly. Every broken pipeline alert or fragmented toolchain forces a developer to drop their current mental model, and regaining that focus takes up to 20 minutes per interruption.
This friction often stems from poor code review practices. Large pull request size and complexity mean reviews take days instead of hours. The author must switch back to the code long after they wrote it, and the reviewer has to dedicate half their afternoon just to understand the changes. Keeping pull requests small and focused protects flow state and accelerates delivery predictability.
When delivery slows down, leaders often look at output metrics instead of workflow inefficiencies and rework. You must identify where developer friction originates to fix the underlying system. Unstable or low-quality code forces engineers into constant firefighting loops, so they spend less time shipping new features and more time managing technical debt.
Generative AI fundamentally changes how your teams build software. The AI impact is massive because the difference between AI-generated vs. human-written code creates a false sense of speed. According to a 2024 GitHub report on AI adoption, an engineer can generate hundreds of lines of code in seconds, but that volume introduces hidden systemic complexity.
This surge in output overwhelms code reviewers and directly causes up to 3x the normal code review churn. The initial velocity looks great on paper, but the downstream reality is a bottleneck of untested logic. AI accelerates output, but it inherently introduces hidden systemic risks if your tooling cannot parse and manage that complexity.
You can't fix systemic issues by only treating the symptoms. Use this framework for root cause analysis to identify exactly where your delivery engine is breaking down.
Engineering leaders often rely on standard benchmarks like DORA metrics or the SPACE framework to track software delivery performance. According to the authors of the SPACE framework in 2021, productivity requires a balanced view of multiple dimensions. According to the 2023 DORA Report, high performers optimize for both speed and stability. These frameworks provide highly valuable signals, but they come with severe practical limitations.
They reveal that performance is changing, but they completely fail to explain why it's changing. Relying purely on lagging metrics or subjective developer sentiment surveys creates blind spots around hidden AI complexity and workflow bottlenecks. You need an operational intelligence layer to connect siloed engineering data and transform those subjective feelings into objective signals.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It creates an operational intelligence layer between data systems and execution. TargetBoard connects fragmented data across planning, code, and delivery systems to surface real-time execution risks before they disrupt predictability.
You need both subjective feelings vs. objective signals to get a complete picture of your engineering operations.
Moving from passive observation to active engineering operations requires a shift in how you use data.
Fixing your environment requires intentional investments in tooling and infrastructure. You must consolidate fragmented tools into internal developer platforms that reduce cognitive load. Proper toolchain integration ensures that data flows smoothly across your organization, so developers don't have to jump between five different applications to complete a single task.
A developer experience engineer builds and maintains the internal tools that keep your delivery engine running. They focus on creating self-service capabilities that allow engineers to provision environments without waiting on IT tickets. This role directly reduces developer onboarding time and eliminates the manual toil that causes burnout.
You can audit your current operations to uncover hidden inefficiencies. Follow these steps to align your engineering practices with delivery predictability.
Mastering developer experience gives you a clear framework to control your software delivery lifecycle. You can stop reacting to delayed releases and start managing the actual workflow friction that slows your teams down. Connecting your fragmented data into a unified operational model protects your engineering effectiveness.
Understanding these patterns gives you the confidence to allocate resources accurately and forecast delivery timelines. You can now present objective operational data to your board and explain exactly why performance is changing, which transforms your engineering organization into a resilient and predictable delivery engine.
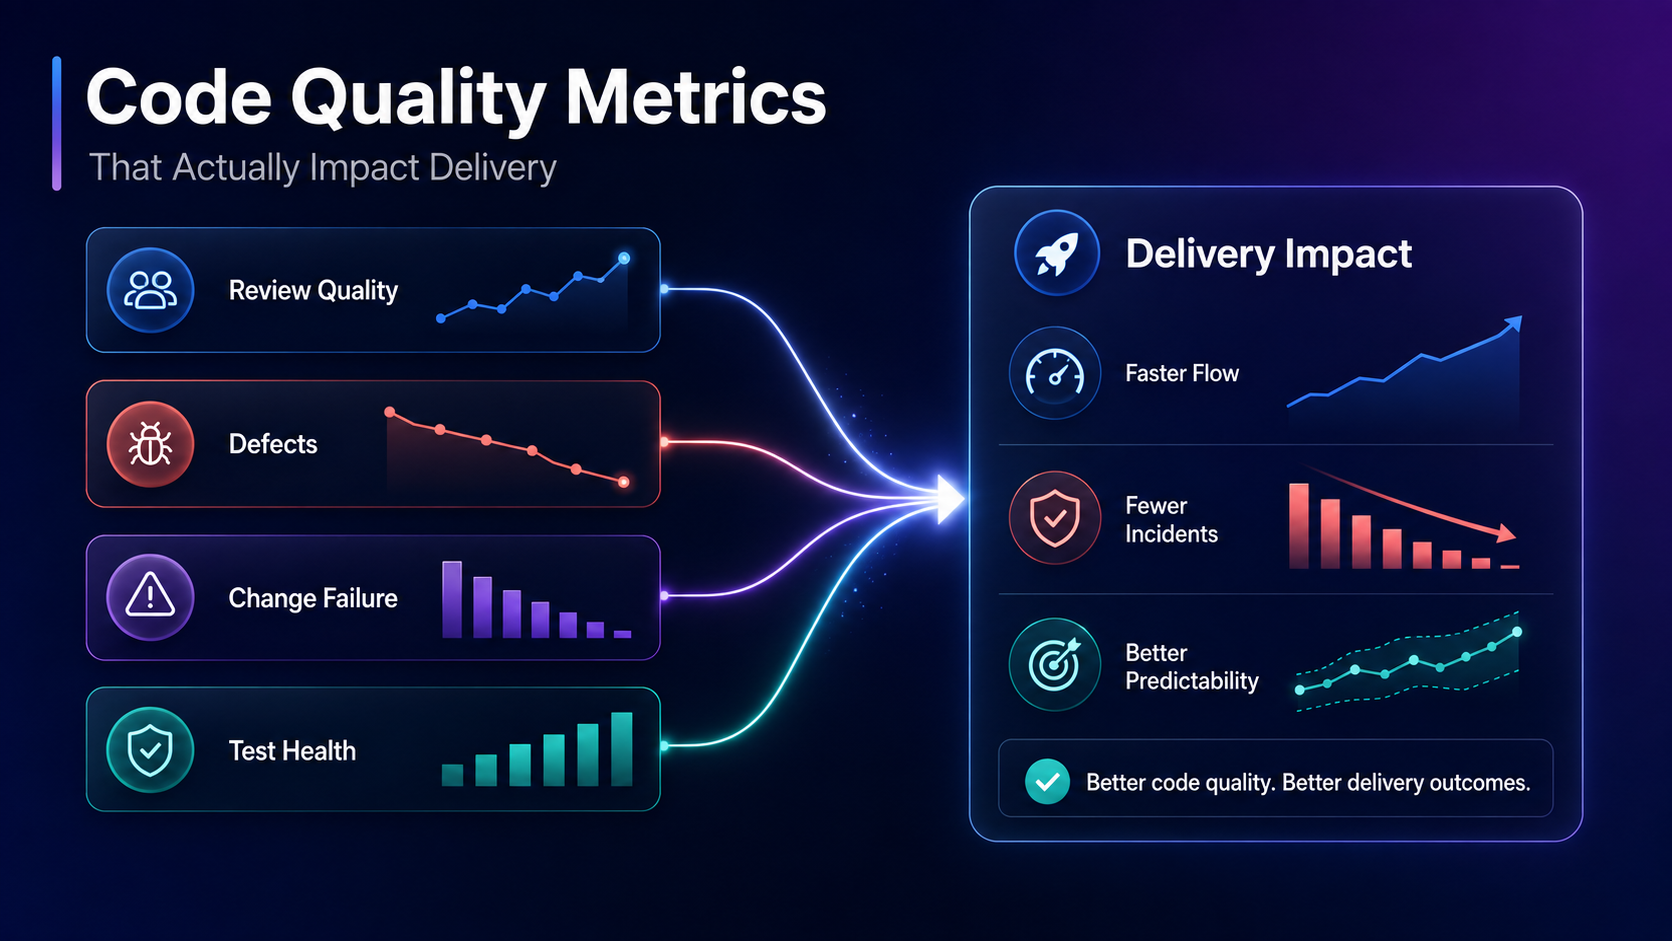
Code quality metrics are quantitative and qualitative measures used to evaluate the health, maintainability, and reliability of a software codebase.
Engineering leaders often struggle to translate raw data into actionable insights for delivery predictability. These metrics solve this by tracking structural complexity, test reliability, and codebase health over time. They act as objective signals that help you identify execution bottlenecks before they slow down your entire development pipeline.
Relying on a single data source creates blind spots across your engineering organization. To measure code quality effectively, you must implement a hybrid approach. Measuring code quality requires capturing both automated and human-driven software code quality metrics.
Measuring structural complexity helps you understand the long-term cost of your code. High complexity creates a massive maintenance burden, so minor feature updates turn into multi-week refactoring projects. Tracking these indicators allows you to manage technical debt before it halts sustainable development. Identifying code smells early prevents fragile architecture from reaching production.
Leaders often confuse cyclomatic complexity with the maintainability index. Both evaluate structural health, but they serve different operational purposes.
A common executive mistake is confusing high developer output with high organizational productivity. A team might merge thousands of lines of code, but that momentum is an illusion if the work consists of heavy code churn and rework. Code duplication inflates output metrics while injecting hidden complexity into the system.
To diagnose these execution bottlenecks, you must look at workflow behavior using these structured signals:
Testing metrics often give leadership a false sense of security. Code coverage tells you what percentage of your codebase executes during a test suite, but it reveals nothing about test reliability or actual system resilience. You must look beyond raw percentages to ensure pre-release stability.
Tracking defect density and bug rate provides a much clearer picture of production readiness. Vulnerability tracking must also integrate directly into your delivery workflows to catch risks early.
Flaky tests destroy developer trust in your continuous integration pipeline. When tests fail randomly, engineers learn to ignore the alerts, so real defects slip into production. This directly impacts your MTTR (mean time to recovery) and increases your change failure rate. High defect density in specific modules signals deep architectural rot that requires immediate intervention to stabilize the system.
Engineering teams optimize for whatever target you set. Pushing rigid mandates creates perverse incentives where developers engage in metric gaming just to satisfy the dashboard. I have seen teams write tautological tests with useless assertions simply to hit an 80 percent test coverage limit. This turns actionable insights into vanity metrics and generates useless rework.
Isolated codebase health metrics don't guarantee delivery performance. You must connect those static numbers to your delivery workflows to see the complete picture. High structural complexity inevitably causes workflow friction, so developers spend more time deciphering logic than shipping features. Cross-repository dependencies increase the blast radius of every code change. You need system-level visibility to understand how these isolated issues delay your entire delivery pipeline.
The industry relies heavily on the framework established by Google's DORA research to measure system health. These are the core 4 metrics you should track:
These metrics provide valuable baseline data, but they fall short because they act as trailing indicators. They tell you that Lead Time is increasing, yet they fail to explain the root cause. DORA metrics don't measure developer productivity or DevEx directly. They provide a partial signal, so you still need an operational intelligence model to understand exactly why those numbers shift.
Large pull request size is the leading indicator of workflow bottlenecks. Massive code changes require immense cognitive load, so reviewers delay looking at them. This drives up PR friction and destroys your code review velocity.
I have experienced the operational pain of trying to manually reconcile Git data with Jira reports during a delayed release. The Jira board showed tickets actively in review, but the Git data revealed massive review churn and continuous rework. When you can't see this friction in real time, you can't clear the bottlenecks before they derail your sprint.
AI-generated code contributions are fundamentally changing how engineering teams operate. According to GitHub's research on AI developer productivity, AI accelerates developer output by up to 55 percent, but it introduces deep hidden complexity.
Traditional CI/CD pipelines weren't designed to handle this sheer volume of automated code generation. You must evaluate the AI impact on your systems to ensure the speed vs. quality tradeoffs don't cripple your architecture.
Yes, ChatGPT and similar large language models can perform basic static code analysis. They can identify syntax errors, suggest optimizations, and ensure alignment with coding standards. But these automated tools lack system-level context. They execute AI code reviews on isolated functions, yet they can't understand how those changes impact cross-repository dependencies or broader architectural goals.
Managing high-volume AI code requires entirely different guardrails than human-written code. I recently saw a team merge a seemingly minor, AI-generated code change that resulted in massive review churn. The AI optimized a single function, but it introduced hidden complexity that broke three downstream services.
Engineering executives have dashboards full of data from SonarQube, Jira, and Git. But these siloed tools don't explain why delivery is slowing down or what the root cause of the friction actually is. Standard frameworks and code quality measures are just raw signals. The gap in modern engineering is no longer data visibility, but rather contextual understanding and coordinated decision-making capability.
The goal isn't to build a better dashboard. You need an operational intelligence layer to achieve true execution alignment. When quality indicators decline, follow this step-by-step process. First, use unified intelligence to detect cross-system dependencies causing the bottleneck, which allows you to see exactly where work is stalling. Next, allocate senior capacity to reduce the technical debt blocking the critical path so your team can regain momentum. Finally, make confident execution decisions before delivery predictability drops.
This proactive approach creates true execution alignment and a sustainable engineering culture. It shifts your leadership posture from reacting to stale data to driving organizational productivity.