Most vendor evaluations combine a product demo, a limited developer trial, feature comparisons, and user feedback.
These inputs can show whether a tool is usable, trusted, secure, and compatible with the existing toolchain. They do not establish whether it improves delivery.
A developer may feel faster while using an AI assistant, yet pull requests may still require more review, create more rework, or spend longer waiting to be picked up.
Developer sentiment provides valuable context. Operational data shows what actually changed.
This distinction is particularly important for AI engineering tools. Faster code creation does not automatically lead to faster review, approval, or deployment. A tool may accelerate one stage while moving friction further downstream.
The customer wanted to compare two AI code review automation vendors: Qodo and CodeRabbit.
Rather than testing the tools with unrelated groups or comparing broad company-wide averages, the team used the same defined group of developers throughout the evaluation. Each vendor was tested during a separate period of approximately two weeks.
The methodology was straightforward:
This was not a laboratory experiment. Real engineering environments include differences in repository complexity, work type, team availability, and pull request size.
But it was a structured, real-world comparison that produced stronger evidence than a feature checklist or a collection of opinions.
The objective was not to prove that one vendor is universally better. It was to determine which vendor produced better outcomes in this customer’s environment.
The analysis depended on consistently isolating the developers participating in the POC.
Without a reusable filter, the team would have needed to rebuild the participant group for each metric and evaluation period, slowing the process and increasing the risk of inconsistent comparisons.
Using TargetBoard Saved Filters, the team defined the relevant contributors and pull request creators once, then reused the same cohort across the board.
This made it easier to:
The team could spend less time configuring the analysis and more time interpreting the results.
The customer focused on what happened after code entered the pull request workflow.
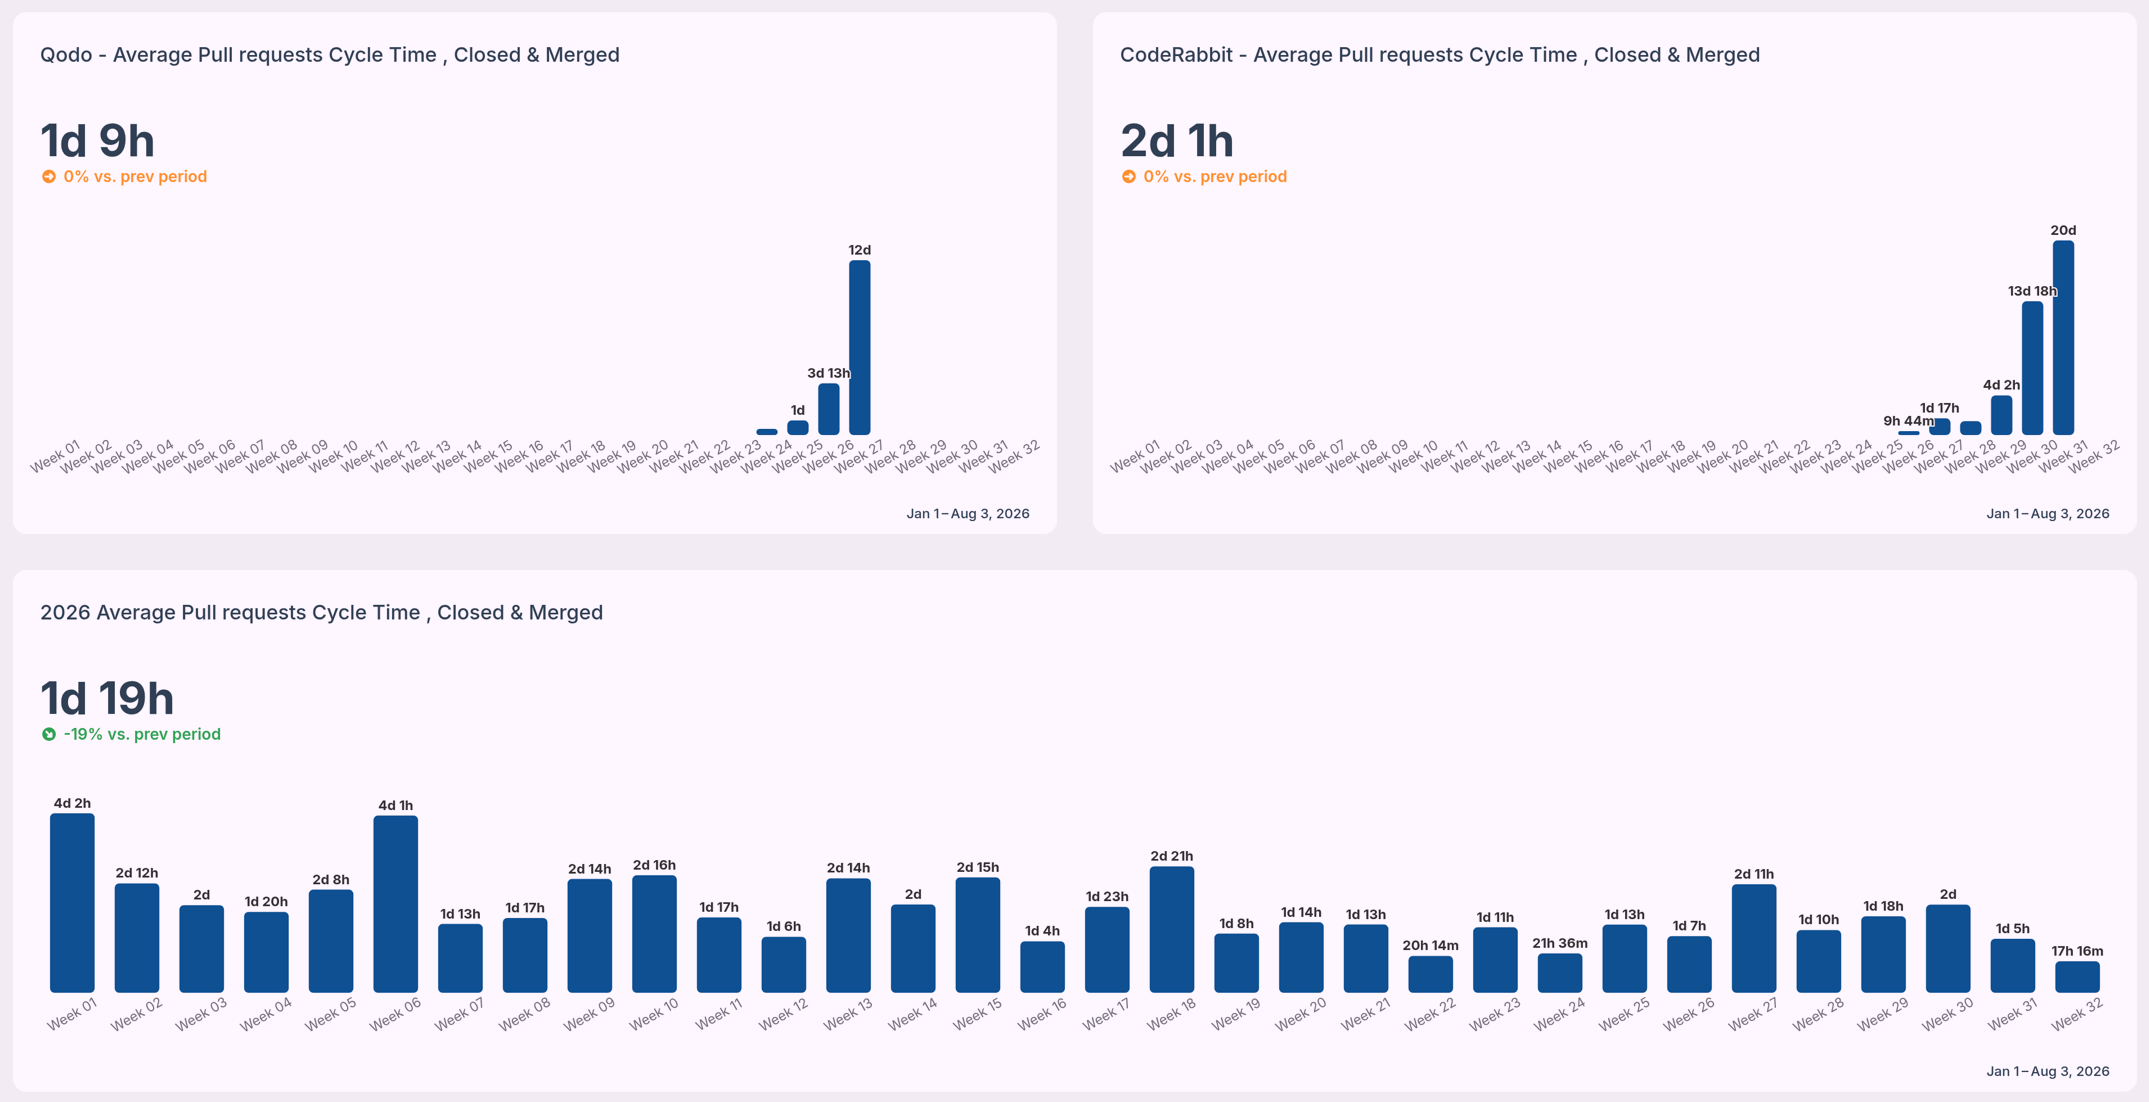
This measured the time from the first commit until the pull request was merged.
It provided an end-to-end view of whether work moved more efficiently during each vendor trial. In this evaluation, the Qodo period showed a shorter average cycle time than the CodeRabbit period.
Cycle time should be treated as a system signal. A higher result may reflect delays in pickup, review, coordination, approval, or integration.
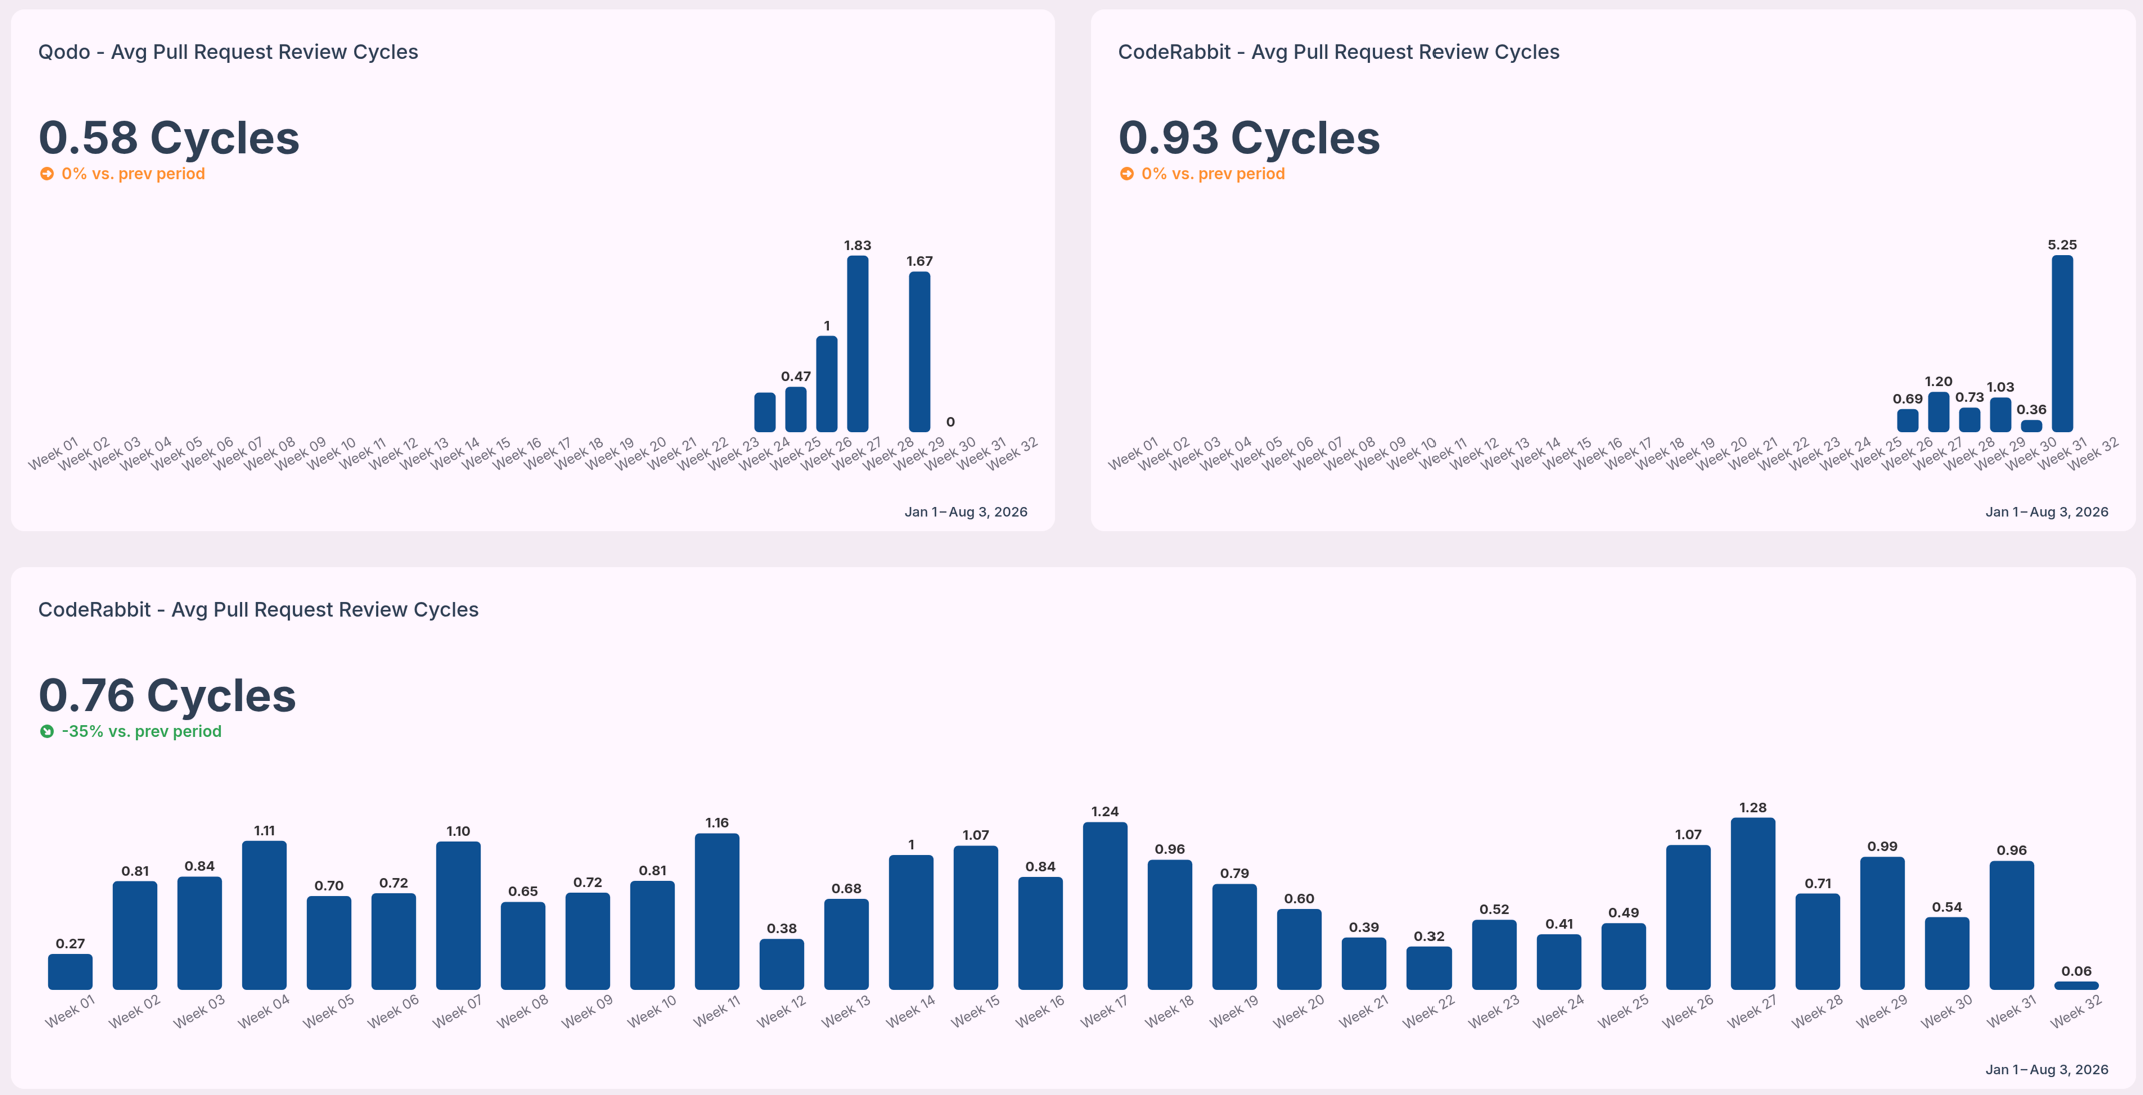
The team also measured how many times a pull request returned to the author for changes before approval.
Fewer review cycles can indicate less back-and-forth and lower review churn. The Qodo period showed fewer average review cycles than the CodeRabbit period.
This was useful evidence, although a full quality assessment would also need to consider defects, incidents, rollbacks, and escaped issues.
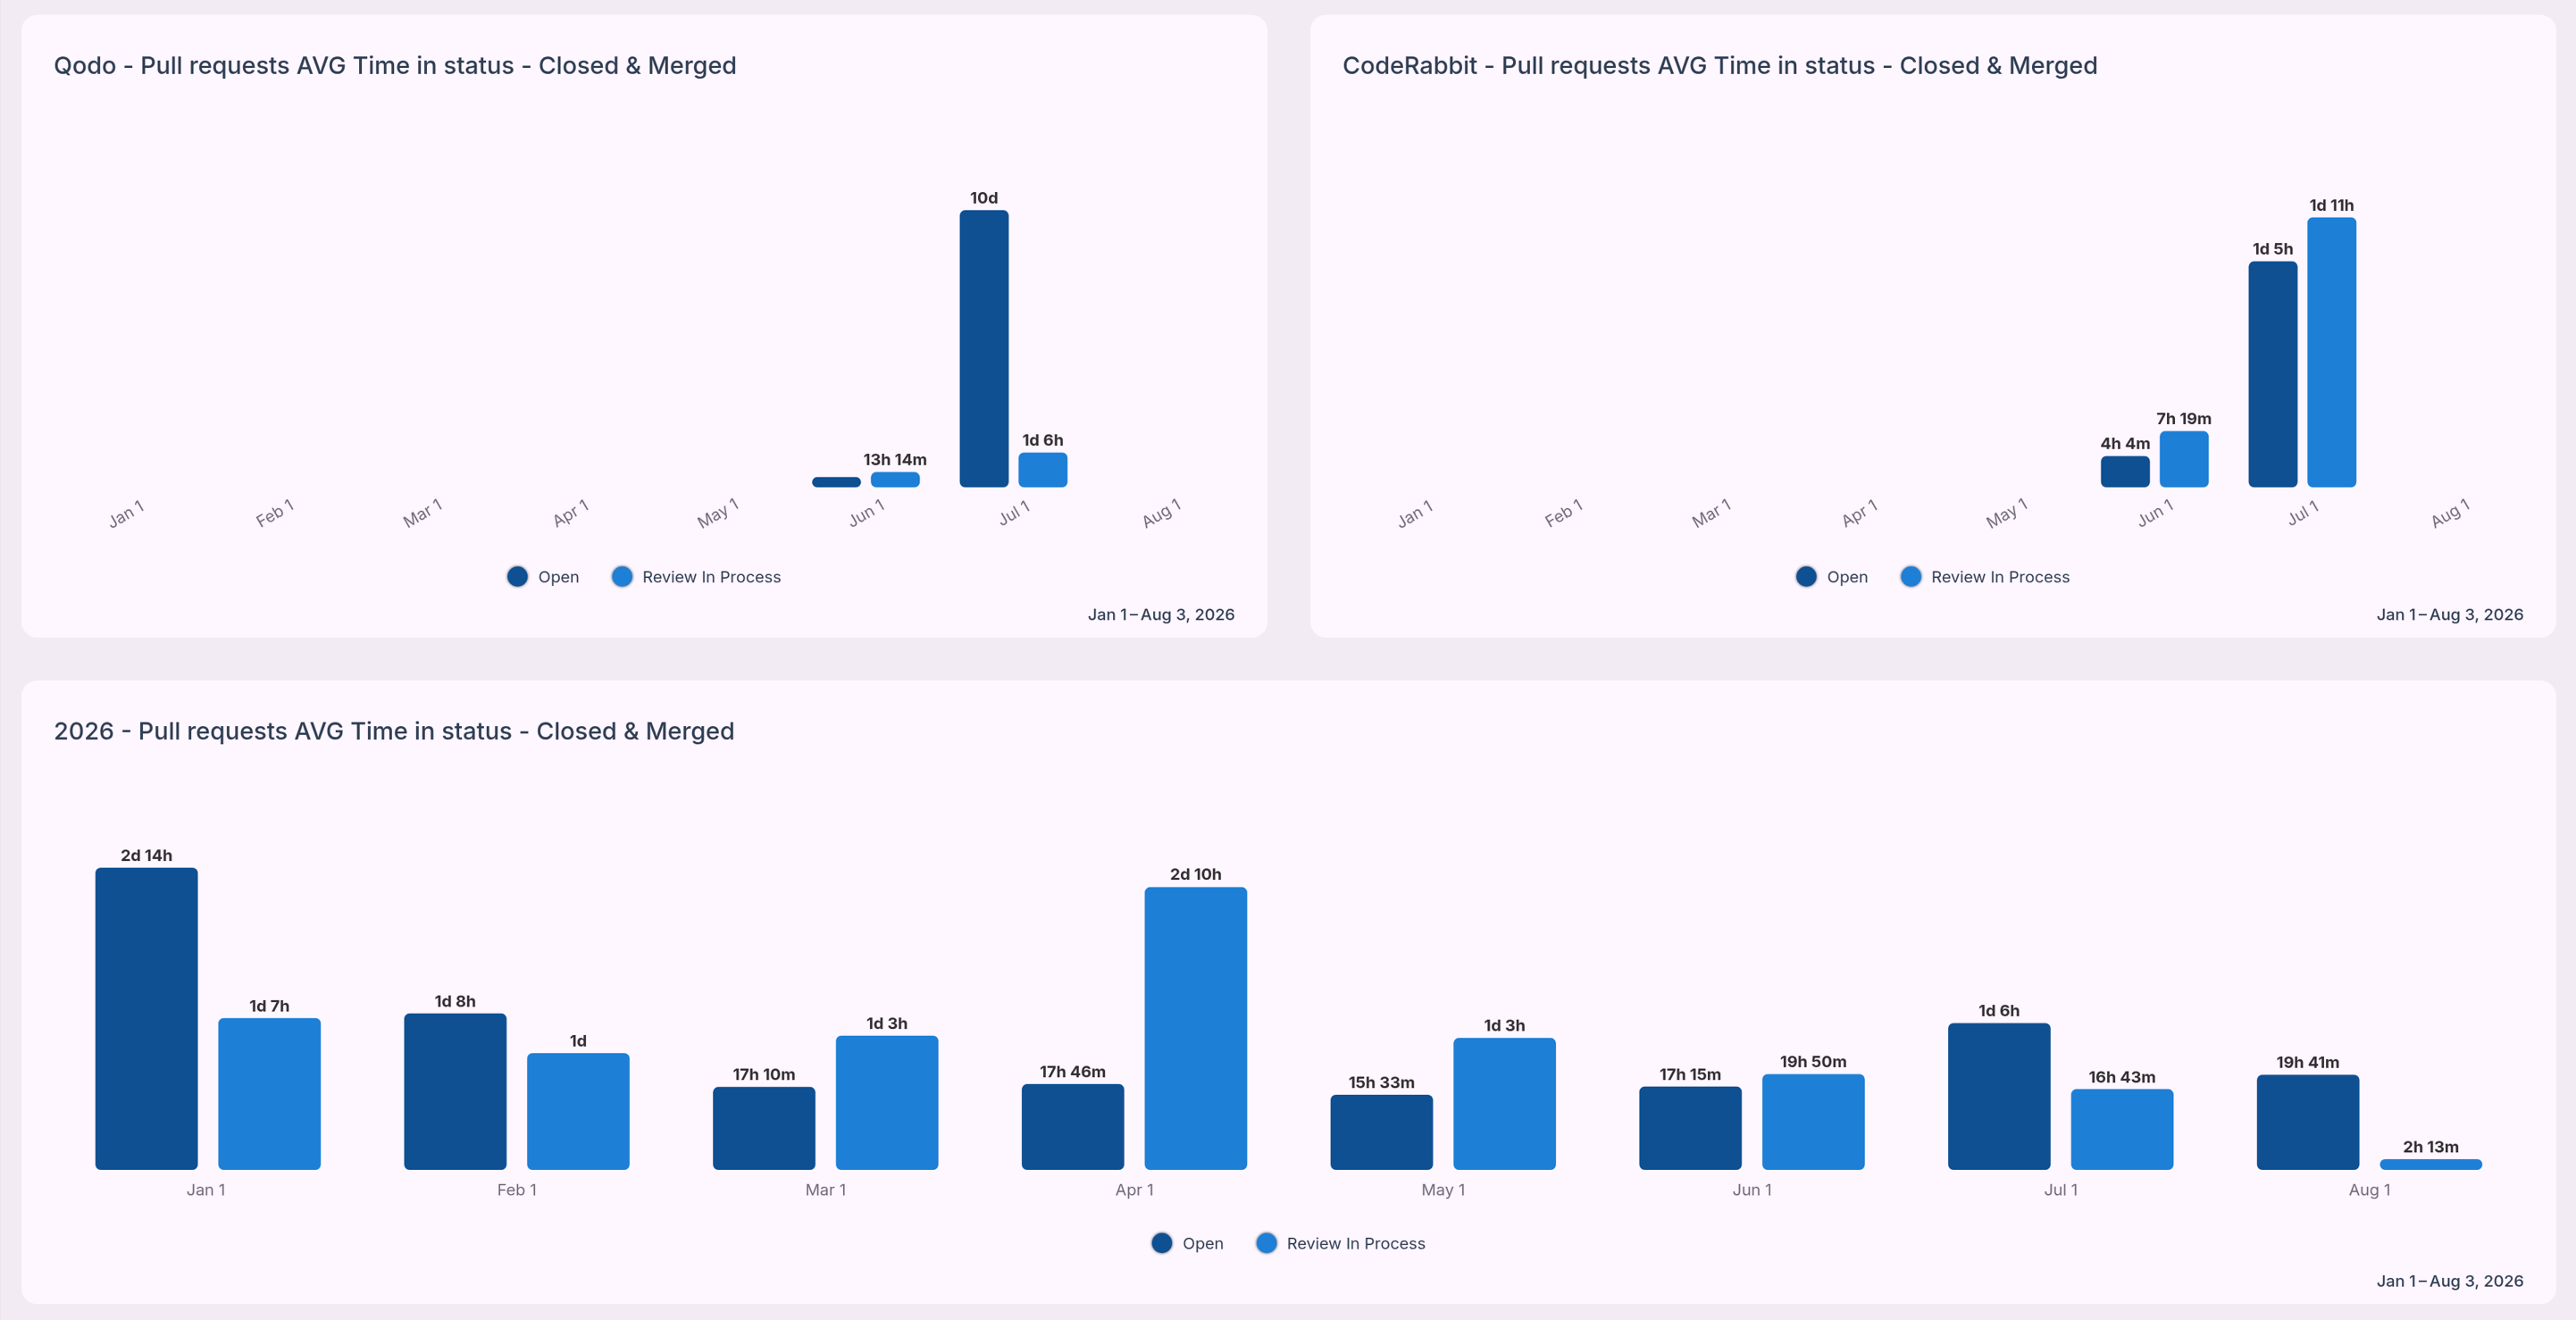
Overall cycle time shows that a difference exists. It does not explain where the delay occurred.
The customer therefore examined time spent in stages such as coding, waiting for review, active review, and merge.
This helped distinguish active work from waiting time and showed whether differences came from review pickup, review complexity, or later workflow stages.
Across the metrics selected for the proof of concept, the Qodo evaluation period showed stronger results than the CodeRabbit period.
The Qodo period recorded:
These results gave the customer a concrete basis for the selection decision.
The team was no longer deciding only which product looked more capable in a demonstration or which tool developers preferred. They could compare how each vendor affected real work inside their engineering system.
The result should remain specific to this customer. It does not establish a universal benchmark for either vendor. The outcome reflected the organization’s developers, repositories, processes, work mix, and evaluation periods.
That limitation does not weaken the analysis. It is what makes the result useful.
The customer needed to know which vendor performed better in its own environment.
A useful AI vendor POC should answer two questions: “Which tool did developers prefer?” and “What changed in the delivery system when the tool was introduced?”.
To build a stronger evaluation:
No single metric should decide the outcome.
A tool may reduce review time while increasing quality risk. Another may receive strong developer feedback but show little measurable effect on delivery. A complete evaluation balances operational outcomes with usability, risk, and cost.
AI engineering vendors should be evaluated on more than features, adoption, and perceived time savings.
The real question is whether a tool improves the flow, quality, and predictability of software delivery.
By testing Qodo and CodeRabbit with a defined group of developers, applying consistent operational metrics, and using TargetBoard Saved Filters to accelerate the analysis, this customer turned a typical POC into a more defensible purchasing decision.
The result was not simply another dashboard. It was a clearer understanding of what changed, where the differences appeared, and which vendor produced the stronger outcome for that organization.
TargetBoard helps engineering leaders compare vendor performance using operational data from their own teams and workflows.
See how TargetBoard can help you build a more objective, repeatable vendor evaluation process.
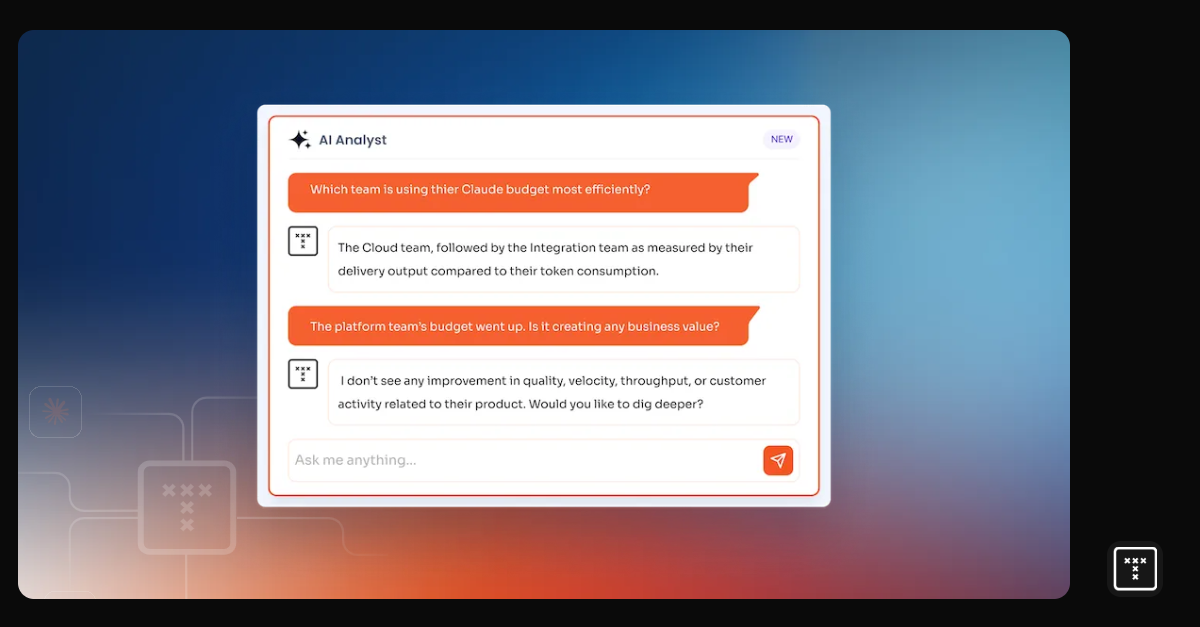
An ai code review is the process of using Large Language Models to automatically analyze pull requests. These tools scan source code analysis outputs to detect syntax errors and suggest refactoring options before a human reviewer steps in. They excel at identifying boilerplate code issues and enforcing standard automated linters. But they struggle with cross-service dependencies and complex business logic constraints.
The most effective engineering teams treat an ai code reviewer as a high-speed assistant rather than an autonomous decision-maker. AI models lack the operational context to make final architectural decisions. They can't negotiate API contracts or understand why a specific workaround exists for a legacy system.
That means a human-in-the-loop review remains absolutely critical. You use the AI to clear out the noise of code formatting and basic threat detection, so your senior engineers can focus their cognitive energy on system design and business logic.
A major limitation of current AI tools is their reliance on file-level analysis. An AI assistant might review a single pull request and confirm the syntax is perfect. Yet that same code might break cross-service dependencies three layers deep in your application.
This happens because AI context windows face strict VRAM limits and memory constraints, preventing them from holding your entire codebase in memory at once. Trusting AI file-level analysis without verifying the broader repository context is a common mistake that leads directly to architectural drift. Your delivery pipeline must connect code changes to system-wide impacts to prevent this risk.
Yes, a code review ai is highly accurate when evaluating isolated syntax and standard formatting rules. Conversely, accuracy drops to near zero when evaluating complex logic or proprietary frameworks. This drop in precision introduces high rates of false positives and AI hallucinations into your pull requests.
Consider a common scenario where an AI tool successfully identifies a missing variable declaration but completely misses a breaking change in your core payment processing logic. The AI then floods the pull request with dozens of comments about stylistic formatting. Developers end up arguing with an AI bot in the comments over subjective syntax choices, creating massive review churn.
This noise creates an overwhelming backlog for human reviewers and actively slows down sprint velocity. Developer overreliance on these tools compounds the problem. Junior engineers might blindly accept AI suggestions without understanding the underlying code, injecting hidden technical debt into the system. You must measure this friction continuously to ensure the tool is actually accelerating your workflow rather than just generating noise.
Selecting the best ai code review tools requires matching the platform's core capability to your specific workflow bottleneck. You must differentiate between tools that generate code, platforms that scan for vulnerabilities, and systems that measure the systemic impact of those changes.
Tools like CodeRabbit and Qodo focus heavily on pull request summarization. They read the diff and generate a plain-language summary of the changes, so human reviewers can grasp the intent faster. This approach often improves initial time-to-merge metrics for simple tasks.
But open source ai code review tools in this category can struggle when deployed on massive enterprise monorepos. The sheer volume of interconnected files overwhelms the model. This leads to generic summaries that fail to capture the actual architectural impact of the change.
GitHub Copilot and similar IDE extensions operate directly where developers write code. These tools use agentic workflows to suggest entire functions as the developer types. They are incredibly effective at reducing the time spent writing boilerplate syntax.
They operate with a limited view of the broader system. A native extension might suggest a highly efficient sorting algorithm, yet it can't verify if that logic violates broader API contracts established by another team. Human reviewers must still validate those systemic connections.
Enterprise platforms like SonarQube and Greptile focus on strict CI/CD integration. They run deep static analysis to ensure your codebase maintains OWASP compliance and prevents known vulnerabilities from reaching production. These tools are non-negotiable for teams operating in highly regulated environments.
A major consideration in this category is data sovereignty. Sending proprietary enterprise code to external models for security scanning introduces compliance risks. You must configure these tools to ensure sensitive data remains within your controlled infrastructure.
Adopting ai powered code review tools frequently increases raw output while secretly damaging delivery predictability. You need a way to measure this friction. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
TargetBoard connects data across company systems and uses domain-expert AI agents to understand workflow bottlenecks. It acts as the essential operational intelligence layer that shows you if your AI coding tools are actually improving sprint velocity or just creating massive review churn.
Implementing ai code reviews requires strict boundaries. You must configure the tool to handle objective rules while reserving subjective architectural decisions for human engineers. If you fail to set these boundaries, the AI will argue with your developers over code formatting and stylistic preferences.
This friction causes massive review churn and slows down your entire pipeline. You must structure the workflow to prevent this noise.
You must map exactly where the AI intervenes in your Software Development Lifecycle. The AI should run its analysis immediately upon pull request creation. It scans for syntax errors, basic code smells, and formatting violations.
The developer resolves these objective flags before a human reviewer is ever assigned to the pull requests. This sequence ensures your senior engineers only spend their time reviewing complex logic and system architecture.
You must train your AI tools using custom rule files specific to your repository. This step prevents the AI from suggesting changes that violate your internal business logic constraints. You can configure the tool to enforce DRY principles and flag code duplication automatically.
The interaction between these custom rule files, the model's context windows, and your code repositories determines the success of the tool. A well-configured rule file reduces false positives and ensures the AI only surfaces actionable insights.
You can't manage what you don't accurately measure. Relying on basic productivity metrics like lines of code written will mislead your leadership team. According to the 2023 DORA Report, true delivery predictability matters far more to business outcomes than raw development speed. You must measure if your ai code review tools are actually accelerating delivery or just shifting the bottleneck.
TargetBoard provides this critical measurement layer. It tracks the difference between AI-generated output and human review times. If an AI tool increases output by 40 percent but causes pull requests to sit in review for three extra days, your actual sprint velocity decreases. TargetBoard exposes these hidden workflow bottlenecks, so you can adjust your strategy based on objective operational intelligence rather than intuition.
The primary value of an AI code review tool is workflow efficiency, not replacing human architectural judgment. These tools are highly effective at clearing out boilerplate errors and enforcing basic code quality. Yet they introduce their own hidden complexities that require continuous systemic measurement.
According to 2024 GitHub Copilot research, AI assistants boost developer productivity by up to 55 percent. You must balance that speed with strict oversight to protect codebase maintainability and prevent the accumulation of technical debt. By running an operational intelligence layer alongside your AI tools, you can safely accelerate software delivery while maintaining complete confidence in your engineering metrics.
Value stream management (VSM) is an operational framework that connects business objectives to the software delivery lifecycle. The goal is to optimize how work moves from idea to production, helping leaders identify constraints and improve continuous flow. But tracking work is only the first step.
You must connect those tracking metrics to actual customer value and time-to-market outcomes. When you understand how value flows through your organization, you can stop reacting to delayed releases and start proactively removing the barriers that slow your teams down.
To build a reliable value delivery pipeline, you need to understand the foundational rules of the methodology. These principles guide teams toward predictable delivery and continuous improvement.
Applying these concepts to engineering requires a hard look at how your teams actually work. You likely track engineering performance using standard indicators like cycle time, lead time, and deployment frequency. These numbers provide a baseline for your delivery speed.
But a dashboard showing a spike in lead time doesn't solve the underlying problem. You have to trace that metric back to the specific workflow behaviors causing the delay. This requires connecting data across your planning and code systems to see the reality of your operations.
Workflow friction often hides inside routine development tasks. Consider a scenario where your overall cycle time suddenly spikes by 40 percent. The dashboard flags the delay, but it can't tell you that three high-complexity pull requests have been sitting in the review queue for four days.
The code is written, yet cross-team dependencies and unclear ownership prevent anyone from merging it. This code review churn artificially inflates your cycle time metrics. The work itself isn't slow, but the system is blocked. Identifying these specific constraints allows you to clear the path rather than just asking teams to code faster.
Traditional organizations fund temporary projects, which naturally creates organizational silos. Teams assemble, build a feature, and then disband. This breaks execution alignment and leaves no clear owner for long-term maintenance or technical debt.
Modern value stream management requires a shift toward a product-centric model. You fund stable, cross-functional teams that own a specific product from end to end. This structure improves capacity allocation because you align your best engineers with long-term value delivery rather than temporary task lists. The result is a more resilient delivery engine that adapts quickly to market changes.
Implementing this framework requires a structured approach to analyzing your value streams. You need to connect resource planning directly to your value delivery pipeline. This ensures you are solving the right problems instead of just optimizing isolated tasks.
Value stream mapping is the diagnostic tool you use to visualize how work flows through your organization. Follow these four steps to build an accurate map:
To improve flow efficiency, you must identify where engineering effort goes to waste. Modern software leaders face specific capacity concerns that look very different from physical manufacturing. Here is how the classic seven wastes translate to software delivery.
You can map your workflows perfectly, but legacy tools often fail because they rely on metrics without context. You see cycle time shifting, but you can't explain why execution breaks down. According to a 2023 Gartner report on engineering operations, most leaders struggle because their operational data is trapped in data silos.
This forces executives to rely on subjective updates from managers instead of trusted system-level reality. Tracking metrics provides visibility, but it doesn't provide understanding. TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
This shifts your organization from reactively monitoring dashboards to proactively fixing workflow friction. You gain the power to make confident execution decisions based on reality.
Artificial intelligence code generation accelerates output, so it fundamentally alters how work flows through your system. But higher output often introduces hidden delivery risk. For example, artificial intelligence code frequently experiences higher code review churn than human-written code because it requires intense scrutiny to verify complex logic.
If you only measure output volume, you miss the bottleneck forming in your review stage. This hidden complexity slows down the entire pipeline and delays critical execution decisions.
Tracking DevOps Research and Assessment metrics is a good start, but it's only showing you the symptoms of an inefficient system. You need to diagnose the disease through root cause analysis to achieve predictable delivery.
A common mistake in engineering leadership is treating performance metrics as goals rather than lagging indicators of system health. According to the 2023 Forrester Report on software delivery, teams that focus purely on metric targets often sacrifice long-term stability. When you stop chasing numbers and start focusing on resolving the underlying workflow constraints, your delivery confidence naturally improves.
This operational shift connects daily engineering tasks directly to broader business outcomes. By treating visibility as a starting point rather than the finish line, you create a culture of continuous improvement that actually scales. Understanding your system gives you a clear framework for your next planning session or your next board meeting.
Most AI coding tools can tell you whether they are being used.
You may be able to track active users, adoption rates, suggestions, acceptance rates, generated code, token consumption, or AI-assisted activity.
That information is useful, but it does not tell you whether engineering performance improved.
Consider two teams that both significantly increase AI adoption.
Both teams can report successful adoption.
Only one is showing clear evidence of better engineering outcomes.
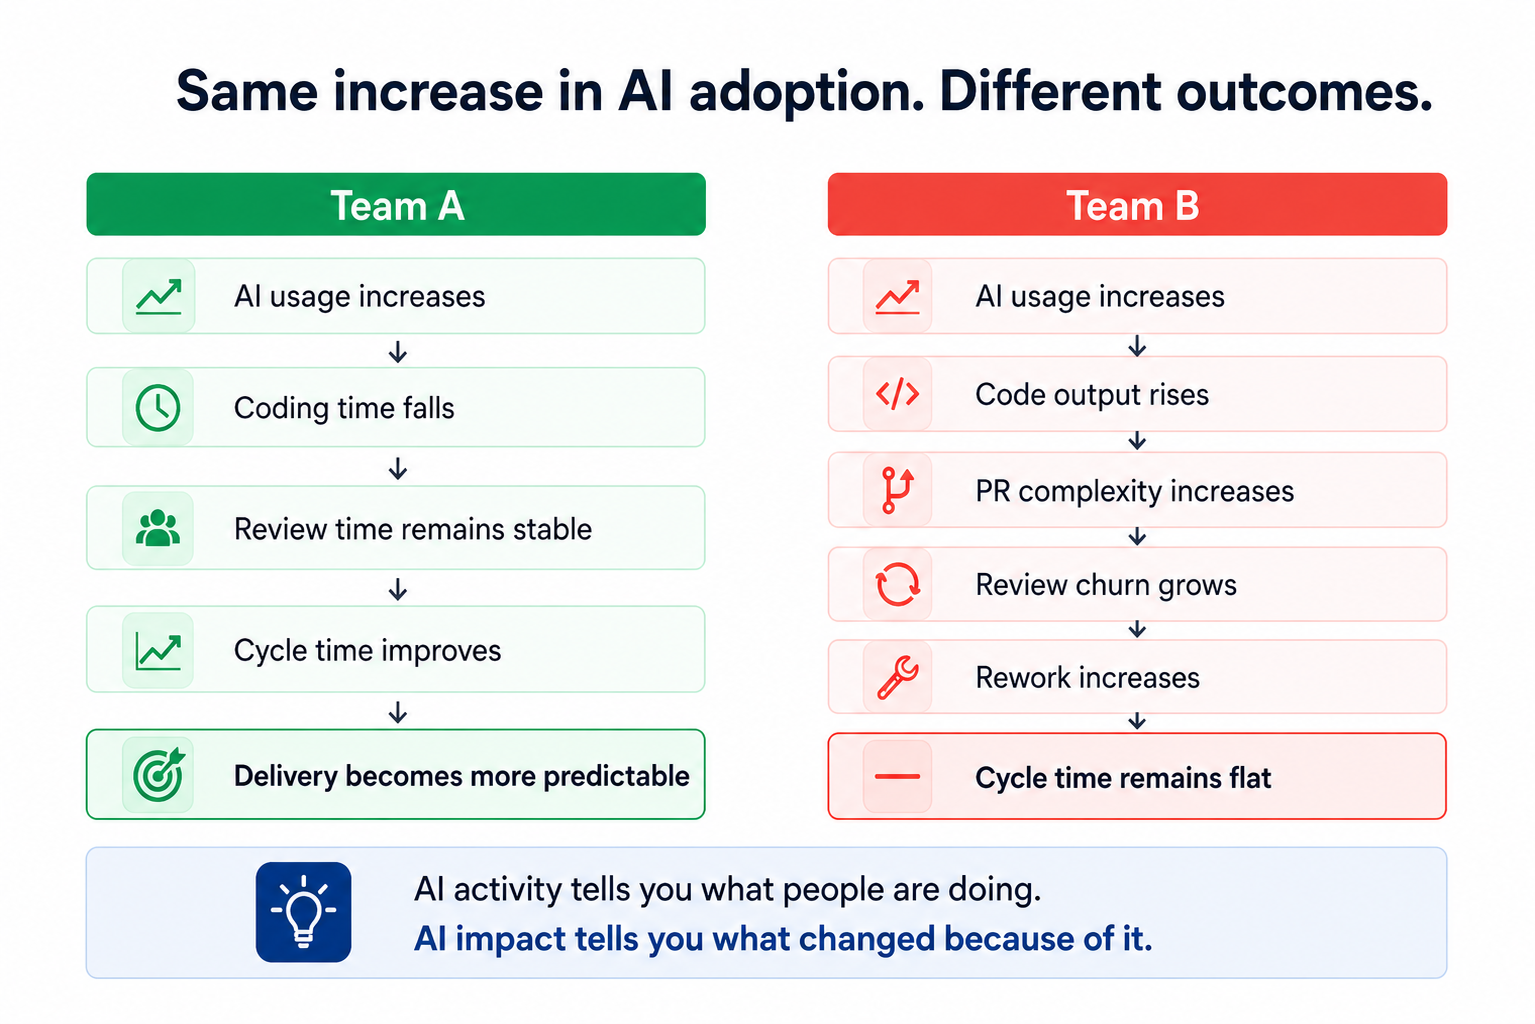
The mistake is jumping directly from adoption to ROI.
High usage does not automatically mean higher productivity, better delivery, or financial return. A more useful model is:
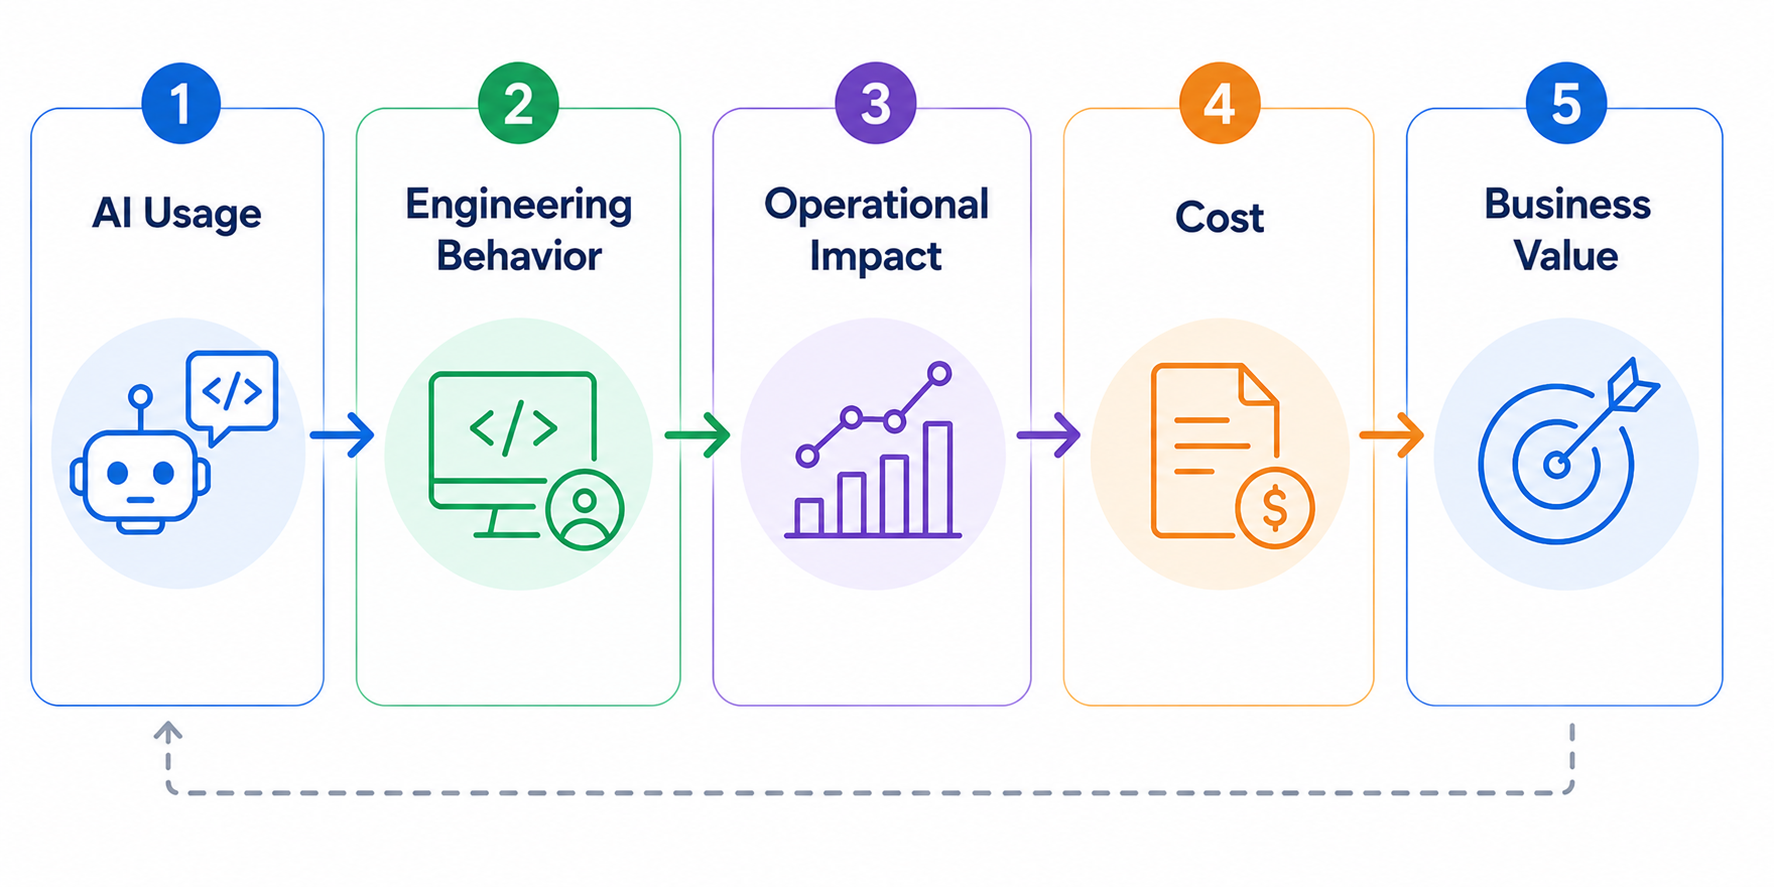
AI may reduce coding time but increase review effort.
It may increase throughput while also increasing rework.
It may deliver significant benefits to one team and almost none to another.
The useful question is not: “How much AI are we using?”
It is: “What happened to engineering performance where AI usage changed?”
Most organizations are not missing the underlying data.
The problem is that each system understands only its own part of the world.
A Cursor usage event does not know what initiative the developer was working on.
A GitHub pull request does not automatically know whether it was AI-assisted.
A Jira ticket does not understand what happened during code review.
An AI license does not tell you if the team using it became more productive.
Take a seemingly simple leadership question:
Answering it reliably may require you to:
Any one of these tasks is manageable.
The complexity comes from keeping all of them correct together.
Teams reorganize. Repositories move. Jira workflows change. AI vendors change. APIs evolve. New leadership questions appear.
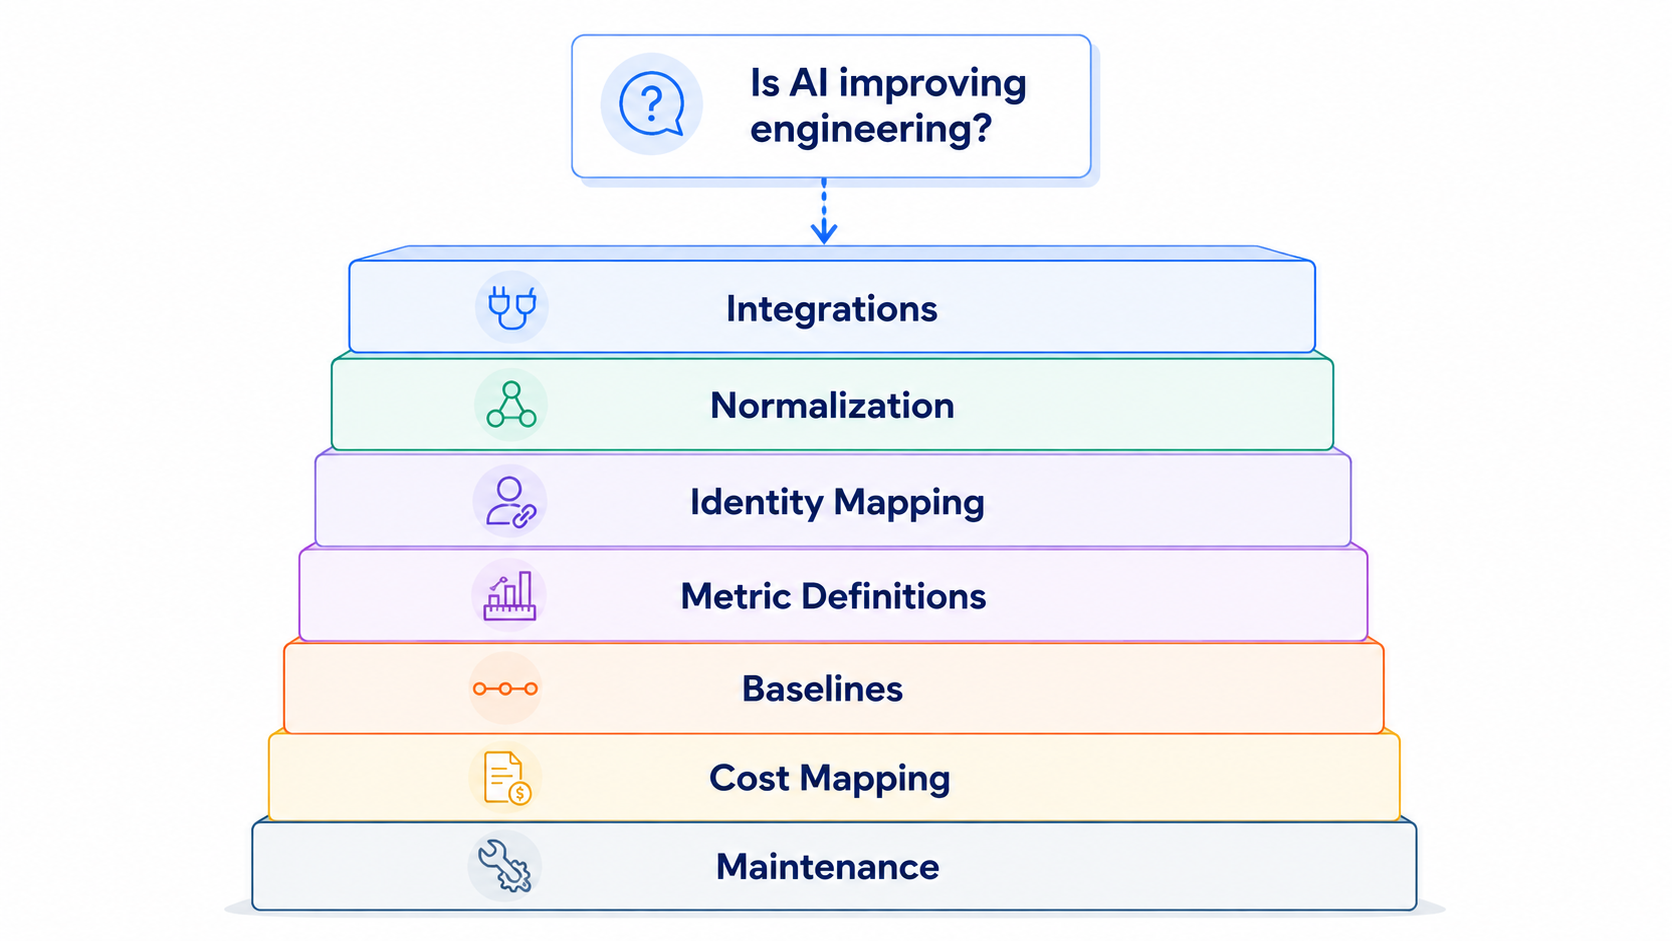
Most engineering organizations have the technical capability to build internal analytics.
APIs, warehouses, transformation tools, BI platforms, internal engineering teams, and increasingly capable AI models are all available.
The question is not whether you can build it.
It is what you want to own.
There is a big difference between connecting Jira and GitHub for a dashboard and maintaining a reliable operational model of the engineering organization.
That model needs to understand relationships between:
And those relationships need to remain accurate as the organization changes.
The internal solution therefore comes with ongoing ownership of connectors, schemas, metric governance, organizational mappings, historical consistency, tool migrations, and analytical logic.
The more useful build-vs-buy question is:
For some organizations, the answer may still be yes.
But it should be a deliberate decision.
A pull request alone can tell you its size, review time, comments, churn, and merge time. Add company context and you can also understand:
That changes the questions leadership can ask.
That is the difference between aggregating engineering data and understanding engineering performance.
Connecting the data still leaves one problem: interpretation.
A dashboard may tell you cycle time increased 18%.
Leadership still needs to determine:
Traditional reporting shows the metric.
Someone still has to explain it.
The next evolution of engineering analytics therefore cannot simply be:
more systems → one dashboard
It needs to be:
Engineering leaders need to understand what changed, what is driving it, and where action is required.
TargetBoard connects data across engineering, planning, AI, organizational, quality, cost, and other company systems while allowing teams to continue working in their existing tools.
That data is normalized into a consistent company context that preserves relationships between people, teams, repositories, work, initiatives, delivery, and outcomes.
On top of that context, domain-expert agents continuously interpret performance to surface what changed, what is driving it, and where risk or opportunity is emerging.
That enables engineering leaders to investigate questions such as:
The goal is not another dashboard. It is removing the data engineering and interpretation work standing between the question and a reliable answer.
AI coding assistants are individual-use tools, so per-seat pricing makes sense.
Engineering intelligence is different.
Its value comes from understanding the organization as a system. A developer does not need to log into an analytics platform for their work to contribute to the operational picture leadership needs.
TargetBoard does not use per-seat pricing.
The objective is organization-wide engineering and AI intelligence, not another product that has to be licensed developer by developer.
Measuring AI impact is technically solvable. The question is how much infrastructure your engineering organization wants to own in order to solve it.
If you build the capability internally, the commitment extends well beyond connecting a few APIs or creating a dashboard. Someone needs to maintain the data model, keep identities and organizational mappings accurate, absorb changes in source systems, preserve historical consistency, and continually adapt the analysis as new AI tools and new leadership questions emerge.
For organizations with highly specific requirements, that investment may be justified.
But for most engineering leaders, the more useful question is whether building and maintaining this measurement layer creates any strategic advantage.
The value is not in owning the pipelines.
It is in being able to answer, with confidence:
Those are management questions, not data-engineering outcomes.
The goal should be to spend less time assembling the evidence and more time using it to make better engineering decisions.
Most vendor evaluations combine a product demo, a limited developer trial, feature comparisons, and user feedback.
These inputs can show whether a tool is usable, trusted, secure, and compatible with the existing toolchain. They do not establish whether it improves delivery.
A developer may feel faster while using an AI assistant, yet pull requests may still require more review, create more rework, or spend longer waiting to be picked up.
Developer sentiment provides valuable context. Operational data shows what actually changed.
This distinction is particularly important for AI engineering tools. Faster code creation does not automatically lead to faster review, approval, or deployment. A tool may accelerate one stage while moving friction further downstream.
The customer wanted to compare two AI code review automation vendors: Qodo and CodeRabbit.
Rather than testing the tools with unrelated groups or comparing broad company-wide averages, the team used the same defined group of developers throughout the evaluation. Each vendor was tested during a separate period of approximately two weeks.
The methodology was straightforward:
This was not a laboratory experiment. Real engineering environments include differences in repository complexity, work type, team availability, and pull request size.
But it was a structured, real-world comparison that produced stronger evidence than a feature checklist or a collection of opinions.
The objective was not to prove that one vendor is universally better. It was to determine which vendor produced better outcomes in this customer’s environment.
The analysis depended on consistently isolating the developers participating in the POC.
Without a reusable filter, the team would have needed to rebuild the participant group for each metric and evaluation period, slowing the process and increasing the risk of inconsistent comparisons.
Using TargetBoard Saved Filters, the team defined the relevant contributors and pull request creators once, then reused the same cohort across the board.
This made it easier to:
The team could spend less time configuring the analysis and more time interpreting the results.
The customer focused on what happened after code entered the pull request workflow.
This measured the time from the first commit until the pull request was merged.
It provided an end-to-end view of whether work moved more efficiently during each vendor trial. In this evaluation, the Qodo period showed a shorter average cycle time than the CodeRabbit period.
Cycle time should be treated as a system signal. A higher result may reflect delays in pickup, review, coordination, approval, or integration.
The team also measured how many times a pull request returned to the author for changes before approval.
Fewer review cycles can indicate less back-and-forth and lower review churn. The Qodo period showed fewer average review cycles than the CodeRabbit period.
This was useful evidence, although a full quality assessment would also need to consider defects, incidents, rollbacks, and escaped issues.
Overall cycle time shows that a difference exists. It does not explain where the delay occurred.
The customer therefore examined time spent in stages such as coding, waiting for review, active review, and merge.
This helped distinguish active work from waiting time and showed whether differences came from review pickup, review complexity, or later workflow stages.
Across the metrics selected for the proof of concept, the Qodo evaluation period showed stronger results than the CodeRabbit period.
The Qodo period recorded:
These results gave the customer a concrete basis for the selection decision.
The team was no longer deciding only which product looked more capable in a demonstration or which tool developers preferred. They could compare how each vendor affected real work inside their engineering system.
The result should remain specific to this customer. It does not establish a universal benchmark for either vendor. The outcome reflected the organization’s developers, repositories, processes, work mix, and evaluation periods.
That limitation does not weaken the analysis. It is what makes the result useful.
The customer needed to know which vendor performed better in its own environment.
A useful AI vendor POC should answer two questions: “Which tool did developers prefer?” and “What changed in the delivery system when the tool was introduced?”.
To build a stronger evaluation:
No single metric should decide the outcome.
A tool may reduce review time while increasing quality risk. Another may receive strong developer feedback but show little measurable effect on delivery. A complete evaluation balances operational outcomes with usability, risk, and cost.
AI engineering vendors should be evaluated on more than features, adoption, and perceived time savings.
The real question is whether a tool improves the flow, quality, and predictability of software delivery.
By testing Qodo and CodeRabbit with a defined group of developers, applying consistent operational metrics, and using TargetBoard Saved Filters to accelerate the analysis, this customer turned a typical POC into a more defensible purchasing decision.
The result was not simply another dashboard. It was a clearer understanding of what changed, where the differences appeared, and which vendor produced the stronger outcome for that organization.
TargetBoard helps engineering leaders compare vendor performance using operational data from their own teams and workflows.
See how TargetBoard can help you build a more objective, repeatable vendor evaluation process.
An ai code review is the process of using Large Language Models to automatically analyze pull requests. These tools scan source code analysis outputs to detect syntax errors and suggest refactoring options before a human reviewer steps in. They excel at identifying boilerplate code issues and enforcing standard automated linters. But they struggle with cross-service dependencies and complex business logic constraints.
The most effective engineering teams treat an ai code reviewer as a high-speed assistant rather than an autonomous decision-maker. AI models lack the operational context to make final architectural decisions. They can't negotiate API contracts or understand why a specific workaround exists for a legacy system.
That means a human-in-the-loop review remains absolutely critical. You use the AI to clear out the noise of code formatting and basic threat detection, so your senior engineers can focus their cognitive energy on system design and business logic.
A major limitation of current AI tools is their reliance on file-level analysis. An AI assistant might review a single pull request and confirm the syntax is perfect. Yet that same code might break cross-service dependencies three layers deep in your application.
This happens because AI context windows face strict VRAM limits and memory constraints, preventing them from holding your entire codebase in memory at once. Trusting AI file-level analysis without verifying the broader repository context is a common mistake that leads directly to architectural drift. Your delivery pipeline must connect code changes to system-wide impacts to prevent this risk.
Yes, a code review ai is highly accurate when evaluating isolated syntax and standard formatting rules. Conversely, accuracy drops to near zero when evaluating complex logic or proprietary frameworks. This drop in precision introduces high rates of false positives and AI hallucinations into your pull requests.
Consider a common scenario where an AI tool successfully identifies a missing variable declaration but completely misses a breaking change in your core payment processing logic. The AI then floods the pull request with dozens of comments about stylistic formatting. Developers end up arguing with an AI bot in the comments over subjective syntax choices, creating massive review churn.
This noise creates an overwhelming backlog for human reviewers and actively slows down sprint velocity. Developer overreliance on these tools compounds the problem. Junior engineers might blindly accept AI suggestions without understanding the underlying code, injecting hidden technical debt into the system. You must measure this friction continuously to ensure the tool is actually accelerating your workflow rather than just generating noise.
Selecting the best ai code review tools requires matching the platform's core capability to your specific workflow bottleneck. You must differentiate between tools that generate code, platforms that scan for vulnerabilities, and systems that measure the systemic impact of those changes.
Tools like CodeRabbit and Qodo focus heavily on pull request summarization. They read the diff and generate a plain-language summary of the changes, so human reviewers can grasp the intent faster. This approach often improves initial time-to-merge metrics for simple tasks.
But open source ai code review tools in this category can struggle when deployed on massive enterprise monorepos. The sheer volume of interconnected files overwhelms the model. This leads to generic summaries that fail to capture the actual architectural impact of the change.
GitHub Copilot and similar IDE extensions operate directly where developers write code. These tools use agentic workflows to suggest entire functions as the developer types. They are incredibly effective at reducing the time spent writing boilerplate syntax.
They operate with a limited view of the broader system. A native extension might suggest a highly efficient sorting algorithm, yet it can't verify if that logic violates broader API contracts established by another team. Human reviewers must still validate those systemic connections.
Enterprise platforms like SonarQube and Greptile focus on strict CI/CD integration. They run deep static analysis to ensure your codebase maintains OWASP compliance and prevents known vulnerabilities from reaching production. These tools are non-negotiable for teams operating in highly regulated environments.
A major consideration in this category is data sovereignty. Sending proprietary enterprise code to external models for security scanning introduces compliance risks. You must configure these tools to ensure sensitive data remains within your controlled infrastructure.
Adopting ai powered code review tools frequently increases raw output while secretly damaging delivery predictability. You need a way to measure this friction. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
TargetBoard connects data across company systems and uses domain-expert AI agents to understand workflow bottlenecks. It acts as the essential operational intelligence layer that shows you if your AI coding tools are actually improving sprint velocity or just creating massive review churn.
Implementing ai code reviews requires strict boundaries. You must configure the tool to handle objective rules while reserving subjective architectural decisions for human engineers. If you fail to set these boundaries, the AI will argue with your developers over code formatting and stylistic preferences.
This friction causes massive review churn and slows down your entire pipeline. You must structure the workflow to prevent this noise.
You must map exactly where the AI intervenes in your Software Development Lifecycle. The AI should run its analysis immediately upon pull request creation. It scans for syntax errors, basic code smells, and formatting violations.
The developer resolves these objective flags before a human reviewer is ever assigned to the pull requests. This sequence ensures your senior engineers only spend their time reviewing complex logic and system architecture.
You must train your AI tools using custom rule files specific to your repository. This step prevents the AI from suggesting changes that violate your internal business logic constraints. You can configure the tool to enforce DRY principles and flag code duplication automatically.
The interaction between these custom rule files, the model's context windows, and your code repositories determines the success of the tool. A well-configured rule file reduces false positives and ensures the AI only surfaces actionable insights.
You can't manage what you don't accurately measure. Relying on basic productivity metrics like lines of code written will mislead your leadership team. According to the 2023 DORA Report, true delivery predictability matters far more to business outcomes than raw development speed. You must measure if your ai code review tools are actually accelerating delivery or just shifting the bottleneck.
TargetBoard provides this critical measurement layer. It tracks the difference between AI-generated output and human review times. If an AI tool increases output by 40 percent but causes pull requests to sit in review for three extra days, your actual sprint velocity decreases. TargetBoard exposes these hidden workflow bottlenecks, so you can adjust your strategy based on objective operational intelligence rather than intuition.
The primary value of an AI code review tool is workflow efficiency, not replacing human architectural judgment. These tools are highly effective at clearing out boilerplate errors and enforcing basic code quality. Yet they introduce their own hidden complexities that require continuous systemic measurement.
According to 2024 GitHub Copilot research, AI assistants boost developer productivity by up to 55 percent. You must balance that speed with strict oversight to protect codebase maintainability and prevent the accumulation of technical debt. By running an operational intelligence layer alongside your AI tools, you can safely accelerate software delivery while maintaining complete confidence in your engineering metrics.
Quick Answer: Platform engineering is the discipline of designing and building self-service workflows to minimize cognitive load for developers.
At its core, an internal developer platform provides:
This approach allows stream-aligned teams to ship code faster without managing underlying operational complexities.
Engineering departments often confuse these roles, and defining clear boundaries is critical for resource allocation. Platform engineers build the paved roads, and DevOps philosophies influence how those roads operate. Without a dedicated platform team, developers often get stuck managing shadow operations instead of writing product code.
Treating the internal developer platform as a mandatory IT project often leads to poor adoption. The Platform as a Product mindset shifts this approach by treating developers as actual customers. Key characteristics include:
The demand for the platform engineering discipline has surged because organizations are struggling to manage the AI impact on software delivery. Developers use artificial intelligence to generate massive volumes of code rapidly, so raw output metrics look incredibly high. But this AI-generated code often introduces hidden complexity and technical debt into the codebase.
Reviewers are forced to spend days validating auto-generated logic. This creates massive workflow friction where code writing is fast but merging is painfully slow. Platform engineering teams are now essential for building the guardrails needed to manage this code surge without sacrificing delivery predictability.
When developers submit highly complex pull requests generated by artificial intelligence, human reviewers can't process them efficiently. This mismatch causes severe workflow bottlenecks that directly inflate cycle time. Pull request churn increases as reviewers request continuous changes to understand the automated logic.
This rework and duplication stall progress across the entire department. When one stream-aligned team gets stuck in an endless review cycle, cross-team dependencies break down. You can't forecast delivery timelines accurately when massive code outputs sit unmerged in fragmented systems.
Platform engineering directly shapes software delivery performance by removing the operational hurdles that slow teams down. A well-designed platform improves execution predictability by:
Golden paths are highly opinionated, supported approaches for building and deploying software. By standardizing these paved roads, platform teams achieve specific outcomes:
Security checks often act as a massive roadblock right before a product launch. Relying on manual approvals and traditional ticket ops forces developers to wait days for a security review, and this actively delays critical releases. Platform engineering solves this by embedding security and compliance guardrails directly into Continuous Integration and Continuous Deployment pipelines.
Developers receive immediate feedback on vulnerabilities while they are still writing code. This shifts security left and eliminates the late-stage friction that frustrates stream-aligned teams.
To evaluate delivery tradeoffs and manage resource allocation effectively, engineering leaders rely on a structured approach to building platforms. According to the Cloud Native Computing Foundation (CNCF) framework, a robust platform requires specific functional areas to operate smoothly^1. These six pillars form the foundation of a predictable delivery system.
A self-service portal provides a single interface for developers to access tools and documentation without filing IT tickets. This centralization reduces context switching so teams can ship features faster.
This pillar automates the setup of cloud resources and deployment environments. You must clearly delineate between basic infrastructure orchestration, which just spins up servers, and advanced operational intelligence, which monitors how efficiently those systems support delivery.
Standardized pipelines govern how code moves from a local commit to a production deployment. Platform teams build these automated routes to ensure every stream-aligned team follows the same reliable path to production.
Automated security checks run in the background to prevent vulnerable code from advancing. This eliminates the need for manual security reviews right before a critical launch.
Observability tools provide real-time visibility into application health and infrastructure performance. If a deployment causes an issue, the platform automatically flags the root cause so developers can resolve it immediately.
Platform teams must track adoption rates and identify workflow bottlenecks to continuously improve the platform. This data proves whether the internal developer platform is actually reducing friction or just shifting the burden to a different system.
Problem: CTOs and engineering leaders often rely on subjective developer surveys or standard engineering metrics to gauge success. These metrics provide useful signals, but they fail to explain why performance is changing or where hidden workflow bottlenecks live within data silos.
Solution: You need an operational intelligence layer to connect fragmented data and track the actual business impact of your platform. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
It connects data across company systems and uses domain-expert artificial intelligence agents to guide execution decisions. Instead of looking at a static dashboard showing an unexplained drop in velocity, TargetBoard surfaces the exact workflow friction causing the delay so you can act immediately and improve system-level visibility.
Tracking engineering effectiveness requires a mix of output metrics and deep execution signals. You must measure how fast work moves and understand the context behind those movements to drive predictable delivery outcomes.
Standard DevOps Research and Assessment frameworks measure critical aspects of software delivery performance. They are excellent supporting signals for your organization. But they don't provide system-level visibility into why a team missed a deadline or why a specific repository is suddenly generating massive technical debt.
Consider the edge case where auto-generated code introduces hidden structural complexity. Standard delivery metrics entirely miss this technical debt until it causes a production incident months later. To truly measure engineering effectiveness, you must transition to operational intelligence that connects signals across planning, code, and delivery systems.
According to Gartner research, most software engineering organizations will establish platform engineering teams by 2026^2. But the platform engineering discipline requires internal cultural shifts and disciplined adoption. It's never just about purchasing software and hoping for a productivity spike.
Referencing Team Topologies provides a strong structural foundation for designing successful platform teams that interact smoothly with the rest of your engineering department^3. When you combine a well-structured platform team with proactive operational intelligence, you stop reacting to stale data. You gain the execution predictability needed to lead with complete confidence.
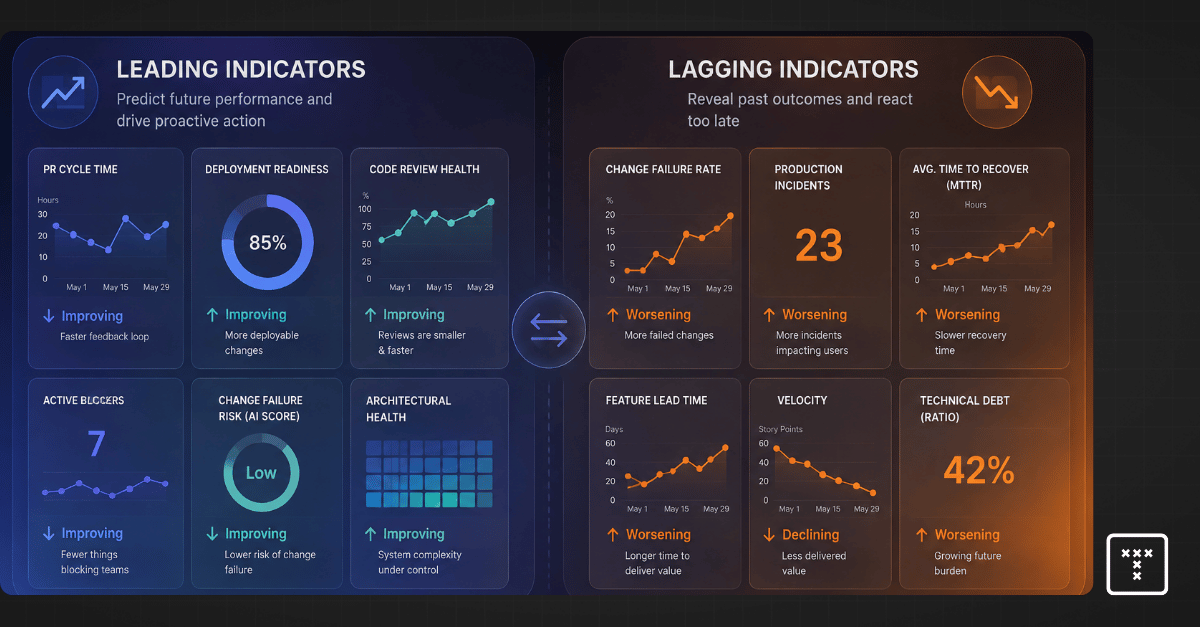
Leading and lagging indicators are the two primary data categories used to evaluate engineering performance. Lagging indicators measure the final results of a process after it concludes. Leading indicators measure the upstream activities and inputs that predict those future results.
Think of this dynamic through the classic windshield versus rearview mirror analogy because it clarifies how you use the data to make decisions. Leading indicators are forward-looking metrics that act as your windshield, helping you anticipate the road ahead. Lagging indicators are backward-looking metrics that serve as your rearview mirror, showing you exactly where you have been. You need both, so you can make accurate execution decisions.
You can quickly audit your current reporting dashboards to evaluate leading versus lagging indicators. Ask these diagnostic questions to determine if your data provides actionable insights or just a historical record:
Investopedia and standard corporate glossaries focus on marketing or sales data when defining leading and lagging indicators. Engineering executives need specific engineering performance metrics mapped to the software delivery lifecycle.
Lagging indicators confirm the final results of the software delivery lifecycle. They are essential for aligning engineering efforts with broader business outcomes. These metrics tell you if a project shipped on time or if a release met quality standards.
Platform engineering teams also track coincident indicators, which measure activity happening right now. The core value of a lagging indicator remains its definitive proof of past performance. Common examples include total bugs found in production and final release frequency.
Leading indicators highlight the friction points happening right now that will inevitably impact your final delivery metrics. These signals allow you to intervene early. If you track Pull Request size and complexity, you can predict which code reviews will stall.
High review churn acts as a clear warning sign, often predicting technical debt and poor code quality. Monitoring cross-team dependencies helps you spot coordination bottlenecks before they derail an entire release timeline. Managing these inputs gives you direct control over the eventual outcomes.
Standard measurement frameworks provide valuable signals about overall organizational health, but they lack the operational understanding needed to drive daily execution. CTOs and VPs of Engineering have experienced the frustration of presenting stalled delivery metrics to a board while their dashboard shows green across the board. Delivery can suddenly halt despite good past metrics because standard tools lack systemic visibility. They force you into a state of reactive management.
This gap becomes critical when teams introduce AI-generated code into their workflows. AI tools dramatically increase code output volume, which creates a false sense of speed. That sheer volume introduces hidden complexity and massive review bottlenecks that standard frameworks fail to catch until cycle time completely collapses. Output volume isn't the same thing as delivery predictability.
You can't manage a modern engineering organization by looking at outcomes alone. You must establish a clear cause-and-effect relationship between your daily engineering activities and your final business results.
Tracking both lead and lag indicators allows you to perform root cause analysis in real time. If you see a predictive signal flashing red, you can course-correct before the sprint fails. According to the 2023 Forrester Research report on engineering operations, teams that actively monitor upstream workflow friction achieve significantly higher delivery predictability than teams tracking only final deployment rates.
Engineering executives know they must track predictive signals to prevent delivery failures. The reality is that manually piecing together fragmented data across tools like Jira and GitHub to compare lagging vs leading indicators is completely unsustainable. You often end up with conflicting signals where Jira shows a project on track while GitHub shows massive review delays.
To truly act on predictive signals, leaders need a system that automatically connects cross-system workflow behavior to delivery metrics to explain why performance is changing. This requires an evolution from passive observation to active intervention.
By unifying this fragmented data, an operational intelligence layer gives you the context needed to make confident execution decisions. You stop relying on stale reports and start managing the actual flow of work.
Understanding the difference between outcome metrics and predictive signals changes how you run your engineering organization. You gain the ability to measure and manage performance based on operational reality rather than retrospective reporting.
This approach gives you a clear framework for technical risk mitigation and smarter resource allocation. By monitoring workflow friction early, you protect your long-term maintainability rather than waiting for a North Star Metric to drop at the end of the quarter. You stop reacting to missed deadlines and start actively guiding your engineering systems toward predictable and sustainable delivery.
Engineering analytics is the practice of analyzing data from the software development pipeline to understand and improve software delivery performance. It connects fragmented data points across issue trackers and code repositories to give leaders systemic visibility.
The goal is to move beyond simply measuring output and start governing the entire delivery system. This continuous evaluation of engineering metrics helps organizations identify bottlenecks and align daily work with strategic business outcomes.
Search results often mix these two distinct concepts. Analytics engineering is a specific job title within the modern data stack. These professionals build and maintain the data pipelines that data scientists use for business intelligence.
Engineering analytics is an operational discipline used by technical executives. VPs of Engineering and CTOs use this discipline to monitor workflow bottlenecks and maintain delivery predictability.
Imagine staring at a dashboard on Friday afternoon during a critical delivery cycle. Deployment frequency looks healthy, yet lead time for changes has doubled. Your engineering managers spent hours dealing with manual reporting overhead to build this view, but the dashboard can't explain the root cause of the delay.
This highlights the fundamental problem with passive reporting. Dashboards give you metrics without context. They show a snapshot of past performance but offer zero actionable insights to resolve the workflow friction. Analytics requires an operational intelligence layer to interpret those signals and guide your response.
Understanding the evolution of data maturity helps clarify why dashboards fall short. The industry breaks analytics into four operational stages.
AI coding tools are fundamentally changing how work is produced. They accelerate initial output, so developers ship more volume in less time. Traditional developer productivity frameworks look at this spike in velocity and assume the system is highly efficient.
But this volume introduces massive hidden complexity. The difference between AI-generated code vs. human-written code often shows up during the review phase. An AI tool might write a feature in ten minutes, but that high-complexity pull request can sit in review for four days. Human reviewers struggle to validate the dense logic, creating severe workflow friction.
The deployment metrics look temporarily inflated, yet technical debt quietly accumulates in the background. The delivery system slows down over time as developers spend hours untangling complex PRs instead of writing new features. You can't manage this new reality with basic dashboards because they measure the speed of creation while completely missing the downstream cost of code review.
The core issue is no longer a lack of visibility. Jira and GitHub provide enough raw data to achieve system-level visibility, yet engineering leaders still lack objective understanding. You need a reliable way to turn conflicting metrics into clear execution decisions without relying on manual analysis or guesswork.
TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance continuously, and uses domain-expert AI agents to guide execution decisions. It automatically interprets fragmented data across your tools to uncover hidden issues like PR churn.
This intelligence layer surfaces decision-ready insights for leaders. You can restore delivery predictability and identify bottlenecks objectively, allowing your teams to stop reacting to stale reports and start addressing workflow friction as it happens.
VPs of Engineering mistakenly treat deployment metrics as a complete measure of developer productivity rather than just a starting signal. According to the 2023 DORA report, elite performing teams prioritize delivery predictability and system reliability alongside raw speed. Frameworks like DORA metrics and the SPACE framework provide valuable benchmarks for these outcomes.
But these frameworks don't provide systemic understanding. They tell you that a metric shifted, yet they can't isolate the root cause behind the shift. You need an active intelligence layer to connect those framework signals to actual workflow behavior.
Real execution decisions happen when you connect data to specific workflow bottlenecks. Consider a sprint where cycle time spikes by 40 percent. A basic dashboard simply reports the delay, but operational intelligence reveals the actual mechanics.
According to 2023 industry benchmarks from LinearB, pull request review time accounts for 70 percent of delivery delays. In this scenario, three high-complexity pull requests sat in review for over four days due to cross-team dependencies, directly causing that 40 percent cycle time spike. Identifying pull request (PR) churn at this granular level allows you to reallocate senior engineers to clear the backlog immediately.
Selecting the right platform requires evaluating how well it moves your organization from reactive reporting to proactive governance. Modern engineering analytics systems and engineering analytics tools fall into three primary categories. You need a unified source of truth to manage complex delivery pipelines effectively.
Relying on output metrics alone creates a false sense of security, especially when AI tools inflate short-term velocity. True organizational improvement requires understanding how work flows through your entire delivery pipeline. Shifting from passive dashboards to operational intelligence gives you the context needed to drive execution alignment.
Understanding these patterns gives you a clear framework for your next resource allocation decision. You can stop reacting to delayed reports and start managing delivery predictability proactively.
Problem: Teams often prioritize short-term deadlines over sustainable software architecture to meet immediate market demands. This creates hidden structural compromises within the codebase.
Solution: Engineering leaders must treat this deferred maintenance as a measurable business liability that directly impacts engineering velocity and resource allocation.
Software developer Ward Cunningham coined the financial analogy of technical debt to explain this dynamic. Borrowing time to release faster is a perfectly acceptable business strategy, but you incur interest on that loan.
You must pay down the principal through regular software maintenance. If you fail to do this, the compounding interest eventually paralyzes the engineering team. Every new feature requires modifying fragile code, so the cost of future changes becomes prohibitively expensive.
Unmanaged debt inevitably causes critical missed delivery targets. A VP of Engineering might commit to a Q3 product launch based on current team capacity. But technical drag from a legacy billing module quickly causes endless pull request churn.
Developer productivity plummets as engineers spend weeks untangling fragile logic instead of building new capabilities. The result is severe system instability and missed business outcomes. Slower feature releases give competitors the advantage and directly impact revenue pacing.
Engineering leaders categorize tech debt by analyzing the intent behind the decision and the context in which it occurs. This framework helps teams distinguish between strategic technical tradeoffs and simple carelessness.
This occurs when a team explicitly knows the right way to build a feature but chooses the wrong way just to meet short-term deadlines. They might hardcode values or skip essential automated testing entirely.
The team makes these technical tradeoffs without any plan to fix the underlying issues later. This behavior signals a toxic engineering culture and guarantees future delivery failures.
Strategic leaders use this category as a calculated business lever. A team might choose a monolithic architecture over microservices to test a minimum viable product and accelerate time-to-market.
The leadership team understands the limitations and actively schedules future sprints to pay down the debt once the product proves its value. This approach aligns engineering efficiency directly with positive business outcomes.
This debt accumulates when teams simply don't know any better. A junior engineering team might build a complex feature without understanding the design patterns required to scale it.
The resulting code is sloppy and introduces massive operational overhead. Leaders must address this through better training, stricter review processes, and improved engineering efficiency standards.
Even the most talented teams accumulate this debt over time. You might build a brilliant system using the best available practices, but industry standards evolve and user demands shift two years later.
The original design no longer fits the current reality. This impacts codebase health and turns previously modern applications into legacy systems. The result is rising pull request churn as engineers struggle to adapt the old code to new requirements.
The rapid adoption of AI coding assistants fundamentally changes how organizations accumulate risk. AI tools allow developers to generate thousands of lines of code in seconds, so this massive spike in output creates a severe bottleneck downstream.
Human reviewers can't match the pace of the machine. AI doesn't necessarily write bad code, but it dramatically increases code complexity. Developers often accept AI suggestions without fully understanding the underlying logic, and this introduces hidden vulnerabilities.
This dynamic forces human reviewers to spend days deciphering convoluted pull requests. The operational overhead skyrockets, and codebase health deteriorates rapidly. You can't solve this modern friction with legacy metrics.
Engineering leaders can't fix every imperfect line of code. You must treat technical debt reduction as an ongoing resource allocation exercise. According to a 2022 McKinsey report, developers spend approximately 30% of their time managing technical debt1. A 2018 Stripe Developer Coefficient study found that engineers lose up to 17 hours a week to software maintenance and bad code2.
You can't afford that level of waste, so you need a systematic approach to identify which infrastructure debt actually threatens your business. Use this step-by-step guide to evaluate and prioritize your refactoring efforts:
You might track a drop in sprint velocity, but that metric alone doesn't reveal the root cause of the slowdown. A common leadership mistake is tracking metrics without contextualizing the underlying workflow bottlenecks.
A single complex pull request can cause severe code review delays, which blocks multiple engineers and creates a cascading delay across cross-team dependencies. You must perform a root cause analysis to understand exactly where the friction lives. Connecting code complexity directly to cycle time delays gives you the objective data needed to prioritize fixes before they derail your release schedule.
Engineering leaders struggle to justify debt to non-technical stakeholders because they lack objective data connecting code quality to business outcomes. Fragmented data across Jira and GitHub erodes trust in the boardroom. You are left relying on intuition rather than concrete signals to defend your resource allocation.
Standard frameworks and Agile methodologies provide signals of a slowdown, but they don't provide an understanding of the underlying causes when operating at scale. To properly evaluate operational friction and justify refactoring, leaders must implement an operational intelligence layer.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
Everyone who touches the product lifecycle shares responsibility for it. Product managers create debt when they push unrealistic deadlines without consulting engineering constraints. Developers create it when they skip technical documentation or ignore established coding standards.
Leadership ultimately owns the debt because they control the culture and the budget. You must foster an environment where engineering efficiency balances perfectly with speed to market. When you treat debt as a shared business reality, teams can openly discuss tradeoffs without fear of blame.
You can't walk into a board meeting and ask for a month to clean up bad code. You must frame the initiative around risk mitigation and delivery tradeoffs. Follow this step-by-step guide to build a compelling executive case:
Understanding these patterns gives you a clear framework for your next resource planning session. You no longer have to wait for a major outage to address technical entropy. You can monitor codebase health continuously and catch bit rot before it impacts your customers.
Start by auditing your current reporting systems to see if they actually explain why performance is changing. Move away from manual data aggregation and implement an intelligence layer that connects code complexity to delivery outcomes. This shift allows you to stop reacting to delayed releases and start driving predictable execution across your entire engineering organization.
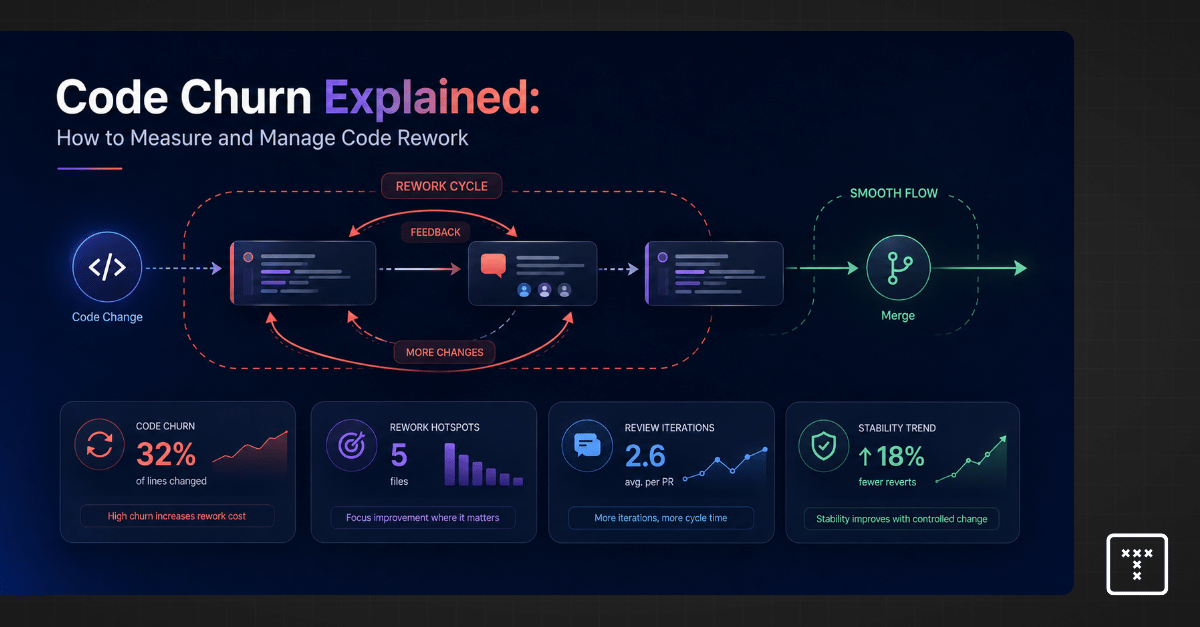
Code churn refers to the percentage of a developer's code that gets rewritten, modified, or deleted shortly after being written. Teams typically measure this within a strict 3-week timeframe. If an engineer writes a function and rewrites it two days later, that action is code churn.
When you ask what is code churn, the answer lies in your version control systems. These systems track the exact lines added, modified, and deleted before code reaches production. High churn over a short period indicates that the code was not stable upon its first commit.
You calculate churn code by dividing the number of lines modified or deleted within a specific period by the total number of lines added during that same period. You then multiply the result by 100 to get a percentage.
Here is how you calculate code rework step by step:
Keep in mind that commit frequency alone doesn't equal churn. A developer might commit frequently to save progress without rewriting the same lines of code.
Code churn isn't inherently bad. It is a natural part of the software development lifecycle. The goal is not to eliminate it, but to differentiate healthy prototyping from destructive rework.
Healthy churn happens during the initial design phase when engineers iterate on complex problems. Destructive rework happens when developers constantly rewrite code due to unclear requirements or accumulating technical debt. This unhealthy behavior creates workflow bottlenecks that delay delivery.
Consider a scenario where a team is updating an aging payment gateway. Working with legacy code naturally requires trial-and-error coding. A developer submits a pull request, and the reviewer requests multiple architectural changes because the original product requirements were vague.
The developer spends the next four days rewriting the same 500 lines of code. This is review churn. It isn't a developer defect, but a systemic issue caused by poorly defined upstream requirements. The engineering effort is wasted, so the entire sprint slows down.
A 5% churn rate is exceptionally low and generally indicates a highly stable, well-understood codebase. Industry research from LinearB1 suggests that a healthy churn threshold sits around 20% for most engineering teams. Appfire2 confirms that exceeding this limit often points to systemic process failures rather than individual coding errors.
But a single baseline doesn't apply universally. A team building a new product from scratch will naturally see higher churn than a team maintaining an established application. You must establish a baseline based on historical engineering metrics for each specific project. If a team's baseline is 15% and it suddenly spikes to 40%, you have a clear signal that sprint velocity is about to drop.
A sudden spike in code rework is a symptom of a deeper operational failure. You must perform a root cause analysis to understand why engineers are rewriting their work. If you ignore the underlying issues, you will see an increase in software bugs and a massive slowdown in cycle time.
Common drivers of destructive rework include:
Last quarter, a core delivery team saw their pull request review churn spike by 40%. The dashboard highlighted the developers as the problem, but the real issue was shifting requirements from product management. The developers were building features based on vague tickets.
When reviewers finally saw the code, they requested massive architectural changes to align with the actual business goals. These communication breakdowns force developers to rewrite working code. This constant rework inevitably leads to developer burnout and severely damages your overall delivery predictability.
Engineers sometimes dive into a problem without a clear architectural plan. This trial-and-error coding results in massive rewrites before the code even reaches the review stage. The issue often stems from failing to apply SOLID design principles early in the process.
When code complexity is high, every new addition breaks existing functionality. Developers have to constantly rewrite their logic to force the new code to fit. You can fix this by enforcing technical design documents before any coding begins.
Avoid using code churn as an individual performance punishment tool because high churn is a systemic workflow diagnostic rather than a developer defect.
You can identify these bottlenecks by tracking your workflow behavior through these steps:
Generative AI is fundamentally altering how software is built. AI coding tools increase raw output, but they often severely bog down review cycles. Developers can generate hundreds of lines of AI-generated code in seconds. This creates an illusion of high productivity.
But this code often contains hidden complexity and massive code duplication. Reviewers have to spend hours untangling the logic, and they frequently force the original developer to rewrite the entire section. This drives up your review churn and creates a massive bottleneck.
Industry frameworks like DORA metrics are excellent tools for measuring engineering performance. They provide valuable signals about speed and reliability. But these metrics only tell you that your cycle time dropped or your defect rate increased. They don't tell you why the change happened.
To manage the influx of AI-generated code and protect your delivery predictability, you need more than passive reporting. You need an operational intelligence layer that connects codebase health directly to delivery risk.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
This continuous intelligence allows you to differentiate between human-written and AI-generated code churn. You catch delivery risk before it gets merged, ensuring your execution stays aligned with your planning.
You can't improve what you don't understand. When you reduce destructive rework, you directly improve your delivery predictability. Teams stop wasting engineering effort on endless review cycles and start shipping reliable features on time.
You must stop treating engineering metrics as a retroactive scorecard. Delivery failures are system issues rather than developer defects. You need to use operational intelligence to catch workflow bottlenecks in real time. This approach restores trust in your reporting and gives you the confidence to allocate resources effectively.
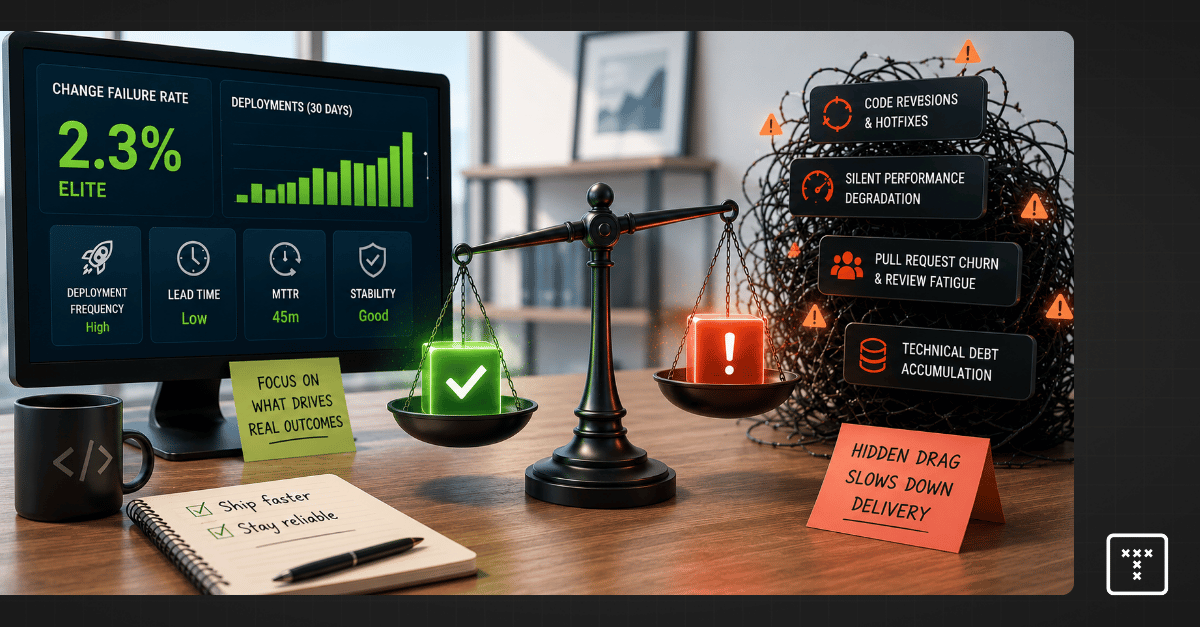
Change failure rate (CFR) measures the percentage of code deployments that result in a failure in production. The goal is to track how often your team pushes code that requires immediate remediation.
This metric serves as a critical counterbalance to deployment frequency. Optimizing strictly for speed often damages quality, so tracking failures ensures your team maintains system stability while shipping features faster. Engineering leaders use this DORA change failure rate signal to balance the inevitable tradeoff between quality versus speed.
Calculating this metric requires standardizing what counts as a deployment and what counts as a failure. You must define these terms consistently across your incident response tools and code repositories.
To calculate change failure rate, use this formula:
(Number of Failed Changes / Total Number of Changes) × 100
Industry benchmarks categorize engineering teams into performance tiers based on their ability to ship code reliably. According to the 2023 Accelerate State of DevOps Report by Google Cloud, you can measure change failure rate against these established standards to gauge your baseline delivery health.
Most engineering leaders limit the definition of failure strictly to hotfixes and rollbacks. This narrow scope misses the broader picture of system degradation.
If a deployment introduces massive technical debt or causes degraded service that doesn't trigger a critical alert, your dashboard will still show a success. This forces leaders to rely on intuition because incomplete data undermines the credibility of engineering reporting. Redefining failure for the modern era means looking at the entire workflow rather than just the final production state to capture the true cost of service patches.
Modern software delivery systems experience friction long before a catastrophic outage occurs. You must expand your definition of failure to capture the hidden costs of code delivery.
A dashboard can easily show an Elite status while your team is actually dealing with high pull request churn. This happens when teams game the metric or pollute the data with inconsistent definitions.
One common mistake is including fix-only deployments in the denominator of your calculation. If you push five hotfixes to resolve a single incident, counting those fixes as new deployments artificially lowers your failure rate. Another pitfall involves poor incident attribution, where third-party cloud outages are counted against internal team performance. These practices create a false sense of stability that operational intelligence must correct to restore trust in your reporting.
Executives must ensure their teams map incidents accurately across the software delivery lifecycle. Messy data makes it impossible to identify root causes and delays critical decision-making.
The rapid adoption of AI coding tools fundamentally changes how we measure delivery risk. These tools drastically increase developer output, so teams write and submit code faster than ever before. Yet this sheer volume of artificial intelligence-generated code contributions introduces unseen complexity into your repositories.
Downstream reviewers simply can't keep up with the flood of new pull requests. This imbalance creates severe review fatigue, where engineers lose the capacity to deeply inspect code for architectural flaws or long-term maintainability issues. The code compiles and passes basic tests, but the underlying structural health of the system degrades quietly.
Unmanaged complexity builds up in your repositories and creates massive workflow friction during the review stage. When a dense, highly complex pull request sits in review for days, engineers eventually rubber-stamp the approval just to clear their queues.
That code merges, sits in the pipeline, and fails days later in production. You then spend valuable engineering cycles on bug prioritization instead of shipping new features. The failure looks like a sudden event on your dashboard, but the root cause was the hidden complexity that bottlenecked your workflow days earlier.
Measuring a failure after it hits production is fundamentally a lagging indicator. Industry frameworks provide useful signals about your software delivery performance, but they don't provide an understanding of why that performance is changing. You need to know where risk enters your system before the code ships to production.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it's changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert artificial intelligence agents to guide execution decisions.
By surfacing hidden risks like review fatigue, code anomalies, and workflow bottlenecks during the actual code review process, TargetBoard allows you to neutralize the root causes of failure before they merge. This shifts your posture from reactive reporting to proactive delivery confidence, ultimately driving true engineering efficiency.
You can actively prevent production failures by changing how your team handles code before it reaches the main branch. Aligned with the foundational Continuous Delivery principles established by industry experts like Jez Humble and Martin Fowler, shifting quality checks left is critical.
Pushing for speed without guardrails creates severe systemic tradeoffs. You must balance how fast you ship with how well your system actually runs.
Requires connecting cross-system data to accurately predict where failures will occur.
Redefining failure requires you to look beyond standard production deployments and measure the friction happening inside your daily workflows.
Your dashboard is only as valuable as the decisions it enables. Passive metrics show you what broke, so you must adopt active operational intelligence to see why it broke. Understanding these patterns gives you a clear framework to improve engineering efficiency and ensure long-term delivery predictability. Moving away from lagging scorecards allows you to scale your software delivery performance safely and build trust with your board.