


Most AI coding tools can tell you whether they are being used.
You may be able to track active users, adoption rates, suggestions, acceptance rates, generated code, token consumption, or AI-assisted activity.
That information is useful, but it does not tell you whether engineering performance improved.
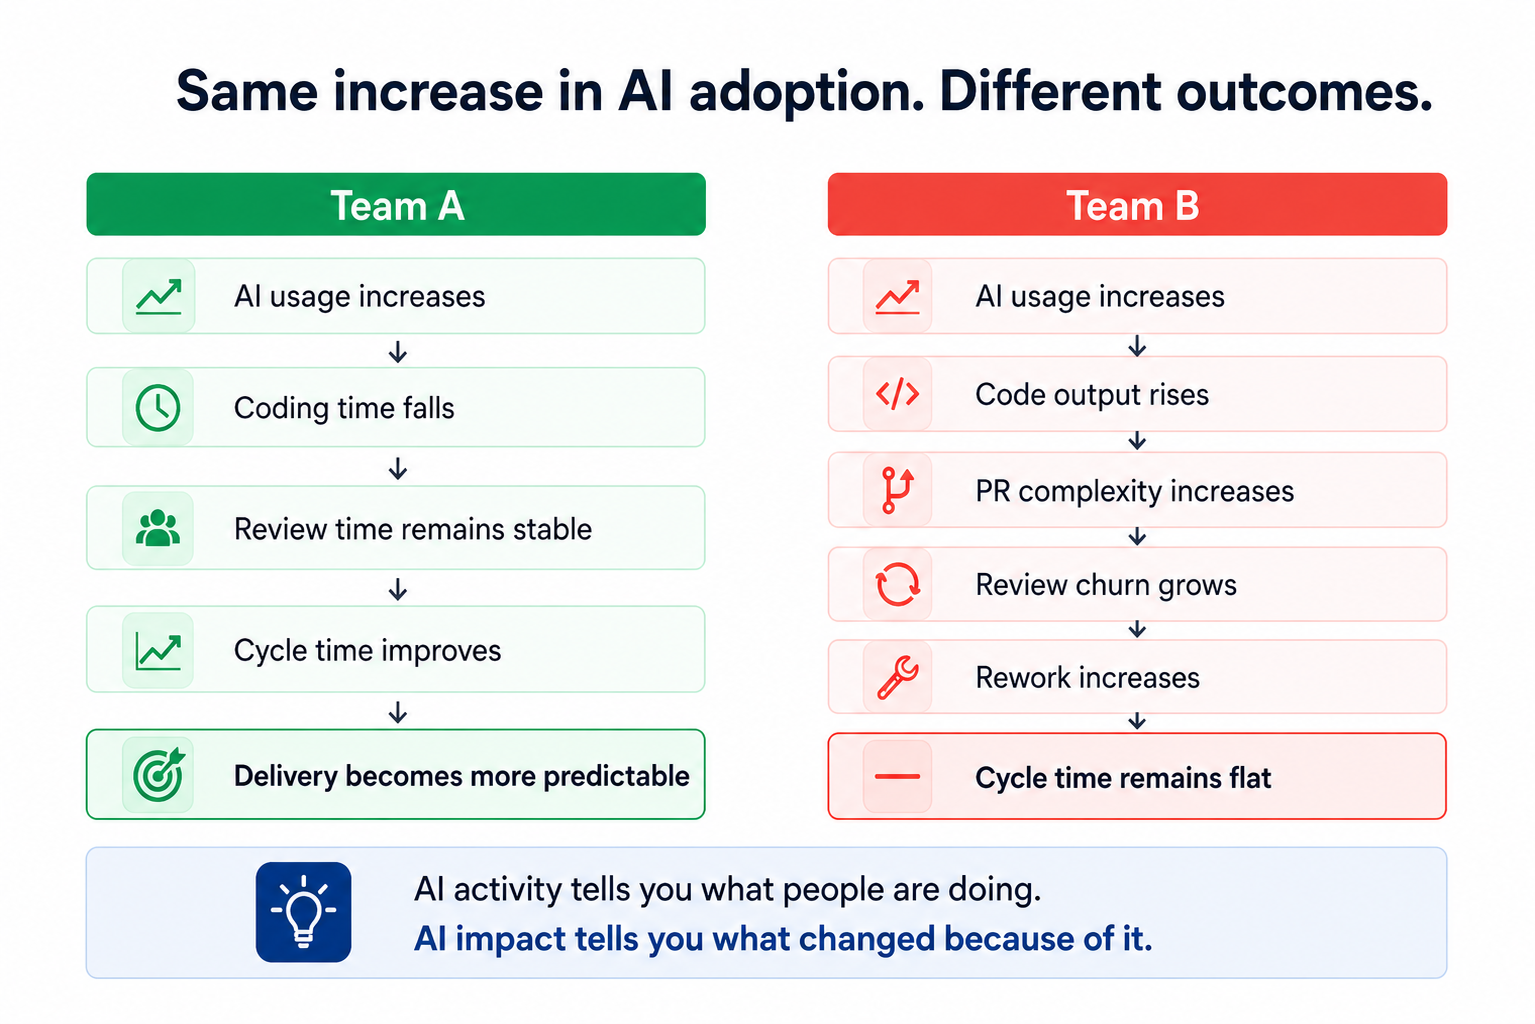
Consider two teams that both significantly increase AI adoption.
Both teams can report successful adoption.
Only one is showing clear evidence of better engineering outcomes.
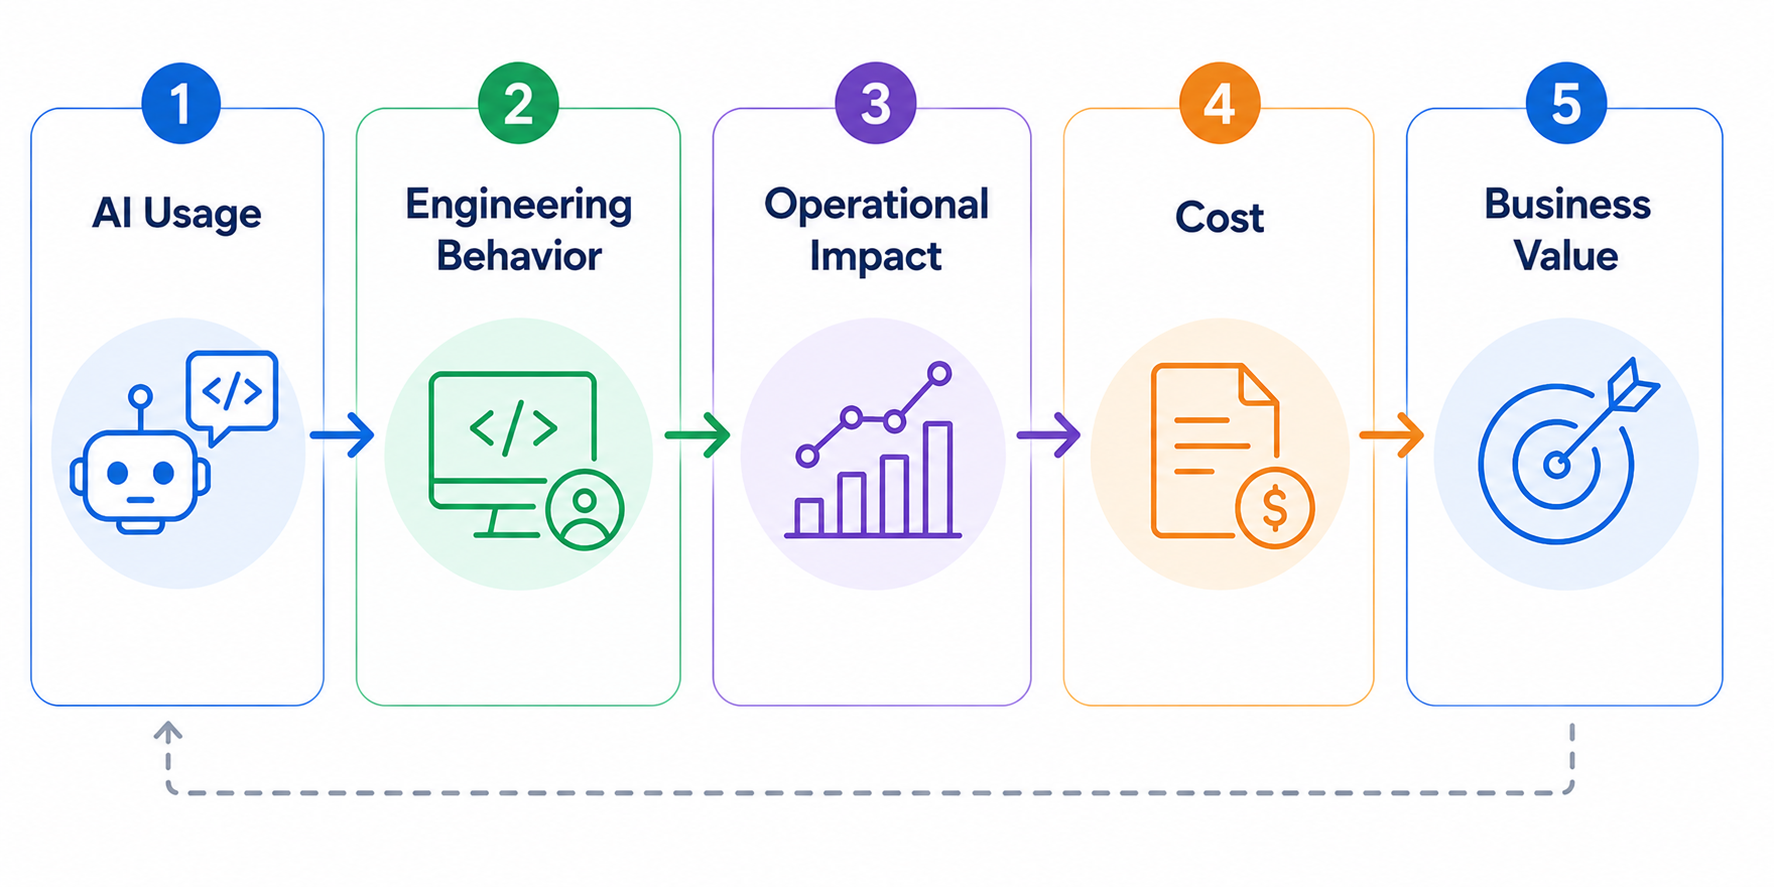
The mistake is jumping directly from adoption to ROI.
High usage does not automatically mean higher productivity, better delivery, or financial return. A more useful model is:
AI may reduce coding time but increase review effort.
It may increase throughput while also increasing rework.
It may deliver significant benefits to one team and almost none to another.
The useful question is not: “How much AI are we using?”
It is: “What happened to engineering performance where AI usage changed?”
Most organizations are not missing the underlying data.
The problem is that each system understands only its own part of the world.
A Cursor usage event does not know what initiative the developer was working on.
A GitHub pull request does not automatically know whether it was AI-assisted.
A Jira ticket does not understand what happened during code review.
An AI license does not tell you if the team using it became more productive.
Take a seemingly simple leadership question:
Answering it reliably may require you to:
Any one of these tasks is manageable.
The complexity comes from keeping all of them correct together.
Teams reorganize. Repositories move. Jira workflows change. AI vendors change. APIs evolve. New leadership questions appear.
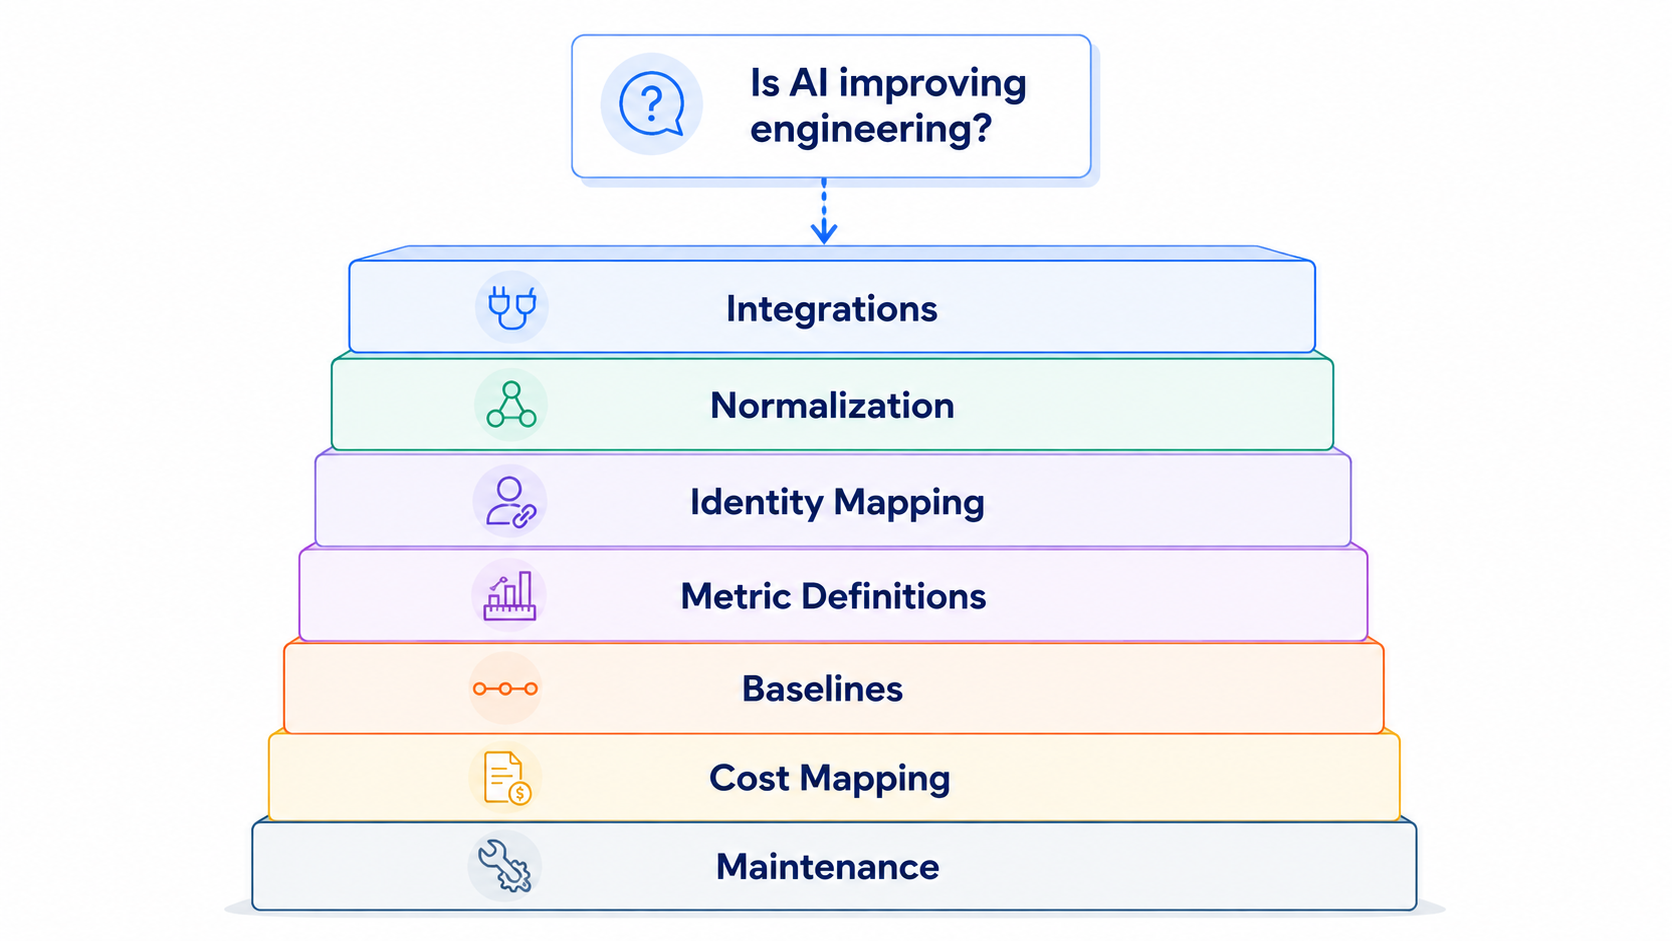
Most engineering organizations have the technical capability to build internal analytics.
APIs, warehouses, transformation tools, BI platforms, internal engineering teams, and increasingly capable AI models are all available.
The question is not whether you can build it.
It is what you want to own.
There is a big difference between connecting Jira and GitHub for a dashboard and maintaining a reliable operational model of the engineering organization.
That model needs to understand relationships between:
And those relationships need to remain accurate as the organization changes.
The internal solution therefore comes with ongoing ownership of connectors, schemas, metric governance, organizational mappings, historical consistency, tool migrations, and analytical logic.
The more useful build-vs-buy question is:
For some organizations, the answer may still be yes.
But it should be a deliberate decision.
A pull request alone can tell you its size, review time, comments, churn, and merge time. Add company context and you can also understand:
That changes the questions leadership can ask.
That is the difference between aggregating engineering data and understanding engineering performance.
Connecting the data still leaves one problem: interpretation.
A dashboard may tell you cycle time increased 18%.
Leadership still needs to determine:
Traditional reporting shows the metric.
Someone still has to explain it.
The next evolution of engineering analytics therefore cannot simply be:
more systems → one dashboard
It needs to be:
Engineering leaders need to understand what changed, what is driving it, and where action is required.
TargetBoard connects data across engineering, planning, AI, organizational, quality, cost, and other company systems while allowing teams to continue working in their existing tools.
That data is normalized into a consistent company context that preserves relationships between people, teams, repositories, work, initiatives, delivery, and outcomes.
On top of that context, domain-expert agents continuously interpret performance to surface what changed, what is driving it, and where risk or opportunity is emerging.
That enables engineering leaders to investigate questions such as:
The goal is not another dashboard. It is removing the data engineering and interpretation work standing between the question and a reliable answer.
AI coding assistants are individual-use tools, so per-seat pricing makes sense.
Engineering intelligence is different.
Its value comes from understanding the organization as a system. A developer does not need to log into an analytics platform for their work to contribute to the operational picture leadership needs.
TargetBoard does not use per-seat pricing.
The objective is organization-wide engineering and AI intelligence, not another product that has to be licensed developer by developer.
Measuring AI impact is technically solvable. The question is how much infrastructure your engineering organization wants to own in order to solve it.
If you build the capability internally, the commitment extends well beyond connecting a few APIs or creating a dashboard. Someone needs to maintain the data model, keep identities and organizational mappings accurate, absorb changes in source systems, preserve historical consistency, and continually adapt the analysis as new AI tools and new leadership questions emerge.
For organizations with highly specific requirements, that investment may be justified.
But for most engineering leaders, the more useful question is whether building and maintaining this measurement layer creates any strategic advantage.
The value is not in owning the pipelines.
It is in being able to answer, with confidence:
Those are management questions, not data-engineering outcomes.
The goal should be to spend less time assembling the evidence and more time using it to make better engineering decisions.

Value stream management (VSM) is an operational framework that connects business objectives to the software delivery lifecycle. The goal is to optimize how work moves from idea to production, helping leaders identify constraints and improve continuous flow. But tracking work is only the first step.
You must connect those tracking metrics to actual customer value and time-to-market outcomes. When you understand how value flows through your organization, you can stop reacting to delayed releases and start proactively removing the barriers that slow your teams down.
To build a reliable value delivery pipeline, you need to understand the foundational rules of the methodology. These principles guide teams toward predictable delivery and continuous improvement.
Applying these concepts to engineering requires a hard look at how your teams actually work. You likely track engineering performance using standard indicators like cycle time, lead time, and deployment frequency. These numbers provide a baseline for your delivery speed.
But a dashboard showing a spike in lead time doesn't solve the underlying problem. You have to trace that metric back to the specific workflow behaviors causing the delay. This requires connecting data across your planning and code systems to see the reality of your operations.
Workflow friction often hides inside routine development tasks. Consider a scenario where your overall cycle time suddenly spikes by 40 percent. The dashboard flags the delay, but it can't tell you that three high-complexity pull requests have been sitting in the review queue for four days.
The code is written, yet cross-team dependencies and unclear ownership prevent anyone from merging it. This code review churn artificially inflates your cycle time metrics. The work itself isn't slow, but the system is blocked. Identifying these specific constraints allows you to clear the path rather than just asking teams to code faster.
Traditional organizations fund temporary projects, which naturally creates organizational silos. Teams assemble, build a feature, and then disband. This breaks execution alignment and leaves no clear owner for long-term maintenance or technical debt.
Modern value stream management requires a shift toward a product-centric model. You fund stable, cross-functional teams that own a specific product from end to end. This structure improves capacity allocation because you align your best engineers with long-term value delivery rather than temporary task lists. The result is a more resilient delivery engine that adapts quickly to market changes.
Implementing this framework requires a structured approach to analyzing your value streams. You need to connect resource planning directly to your value delivery pipeline. This ensures you are solving the right problems instead of just optimizing isolated tasks.
Value stream mapping is the diagnostic tool you use to visualize how work flows through your organization. Follow these four steps to build an accurate map:
To improve flow efficiency, you must identify where engineering effort goes to waste. Modern software leaders face specific capacity concerns that look very different from physical manufacturing. Here is how the classic seven wastes translate to software delivery.
You can map your workflows perfectly, but legacy tools often fail because they rely on metrics without context. You see cycle time shifting, but you can't explain why execution breaks down. According to a 2023 Gartner report on engineering operations, most leaders struggle because their operational data is trapped in data silos.
This forces executives to rely on subjective updates from managers instead of trusted system-level reality. Tracking metrics provides visibility, but it doesn't provide understanding. TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
This shifts your organization from reactively monitoring dashboards to proactively fixing workflow friction. You gain the power to make confident execution decisions based on reality.
Artificial intelligence code generation accelerates output, so it fundamentally alters how work flows through your system. But higher output often introduces hidden delivery risk. For example, artificial intelligence code frequently experiences higher code review churn than human-written code because it requires intense scrutiny to verify complex logic.
If you only measure output volume, you miss the bottleneck forming in your review stage. This hidden complexity slows down the entire pipeline and delays critical execution decisions.
Tracking DevOps Research and Assessment metrics is a good start, but it's only showing you the symptoms of an inefficient system. You need to diagnose the disease through root cause analysis to achieve predictable delivery.
A common mistake in engineering leadership is treating performance metrics as goals rather than lagging indicators of system health. According to the 2023 Forrester Report on software delivery, teams that focus purely on metric targets often sacrifice long-term stability. When you stop chasing numbers and start focusing on resolving the underlying workflow constraints, your delivery confidence naturally improves.
This operational shift connects daily engineering tasks directly to broader business outcomes. By treating visibility as a starting point rather than the finish line, you create a culture of continuous improvement that actually scales. Understanding your system gives you a clear framework for your next planning session or your next board meeting.
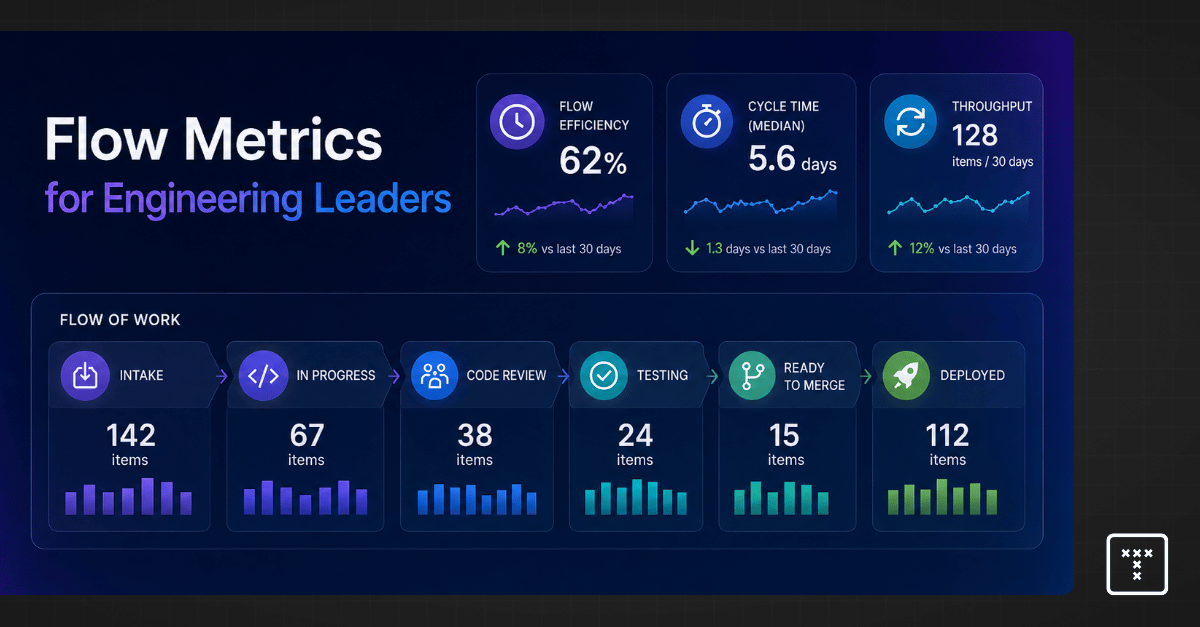
Understanding flow metrics means looking at how value moves from an initial idea to time-to-revenue. These metrics track work across the end-to-end value stream to help leaders spot hidden blockages before they impact delivery predictability. They provide clear signals about where workflow friction occurs, so you can diagnose system stress instead of blaming individual developers.
The 4 key flow metrics provide a foundational view of delivery health and system capacity.
The flow framework metrics defined by Dr. Mik Kersten offer a more specific lens for analyzing engineering performance signals.¹
Teams shipping 50+ deployments a week boast excellent DORA scores while struggling with terrible software delivery predictability. A team might deploy multiple times a day, yet their overall flow load is massive and critical features are constantly delayed.
This happens because DORA relies on point-in-time metrics that measure output events rather than the continuous progression of work across the development lifecycle. DORA shows you how fast you ship, while flow metrics reveal how work actually moves. Relying solely on speed creates proxy metrics limitations that hide the true cost of context switching.
DORA metrics focus purely on deployment speed and operational stability, originally established by the DevOps Research and Assessment team.²
DORA metrics and flow metrics act as complementary engineering performance signals. DORA measures the final mechanical steps of software delivery, focusing entirely on speed and stability. Measuring flow focuses on the entire value stream, tracking how work moves through cross-team dependencies from planning to execution.
When you combine both, you can see the delivery tradeoffs teams make. For example, a team might inflate deployment frequency by shipping tiny updates while larger feature requests rot in the backlog. Flow metrics expose these behaviors, giving leaders the context needed to make confident capacity decisions.
Identifying execution bottlenecks requires shifting from passive observation to active capacity allocation. When you spot workflow friction, you need a systematic approach to clear it and drive continuous improvement.
One of the most common bottlenecks occurs during the code review process. When you analyze wait time vs. active time, you often find that pull requests sit idle for days before receiving a review. This delay usually stems from subjective review decisions or massive PR sizes that intimidate reviewers.
Tracking Work Item Age helps you spot these stalled reviews early, allowing you to step in and facilitate delivery risk mitigation. By addressing code review risk directly, you prevent minor delays from snowballing into missed release dates. Tracking a specific pull request's age recently helped one engineering team prevent a critical release delay by highlighting a PR stuck in an endless, subjective review loop.
High Work in Progress directly correlates with reduced throughput. When Flow Load spikes, teams spend more time context-switching than actually writing code. You need system-level visibility to enforce strict WIP limits and stabilize the delivery pipeline.
AI tools allow developers to generate code faster than ever, yet this speed often creates throughput anomalies. You might see a massive increase in tickets closed, so you assume productivity is up. This artificial output spike often hides a surge in AI-generated code complexity.
Reviewers simply can't keep up with the volume. This bottleneck tanks flow efficiency and causes massive rework churn. You end up with a pipeline stuffed with code that is fast to write but incredibly slow to review, test, and merge.
Cycle time and throughput act as trailing indicators. By the time they show a slowdown, the damage is already done. AI accelerates the creation of new features, but it also accelerates technical debt accumulation. When developers push complex AI-assisted pull requests, they introduce hidden complexity into the codebase.
Over time, your team spends more time fixing bugs than building features. This shifts your capacity from value demand to failure demand, slowly strangling your delivery pipeline. You need visibility into code complexity before it merges, or your future delivery predictability will collapse.
Flow metrics are incredibly useful for spotting system stress, but optimizing for them in isolation creates a massive blind spot. Frameworks provide signals. They do not provide understanding. A metric dashboard might tell you that cycle time is up, but it can't explain that three high-complexity AI-generated pull requests are stalled in code review.
When you rely on data silos and fragmented reporting, executive decision-making becomes a guessing game. Leaders see the numbers shift but can't explain why, which erodes trust across the organization. To fix this, you must bridge the gap between static measurement and operational intelligence.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects cross-system data to continuously analyze performance, translating raw signals directly into decision-centric execution actions.
You can't achieve predictable delivery by simply staring at charts. True execution alignment requires connecting your planning data directly to your codebase. When you rely solely on passive measurement across the software delivery lifecycle, you risk optimizing the wrong things. Some teams even game throughput by breaking tickets into artificially small chunks without actually improving value delivery.
The mathematical realities of Little's Law dictate that cycle time equals work in progress divided by throughput. If you allow work in progress to expand indefinitely, cycle time mathematically must increase. You must shift from reporting on the past to predicting the future, using active intelligence to manage flow load and guide your daily operations.
Developer experience defines the operational reality of how engineers interact with your technical infrastructure to build and ship code. It measures the level of friction in daily workflows and directly impacts software delivery performance. A poor dev experience means your team spends more time fighting internal systems than solving actual business problems.
Board members and C-suite leaders often mistakenly treat what is developer experience as a cultural or HR initiative focused on office perks. You must treat developer experience as the UX for your engineering team. If the internal systems are slow or siloed, your team can't ship predictably.
You might notice a high-complexity pull request sitting in review for multiple days. That isn't a motivation problem. It's pure organizational drag caused by poor system design.
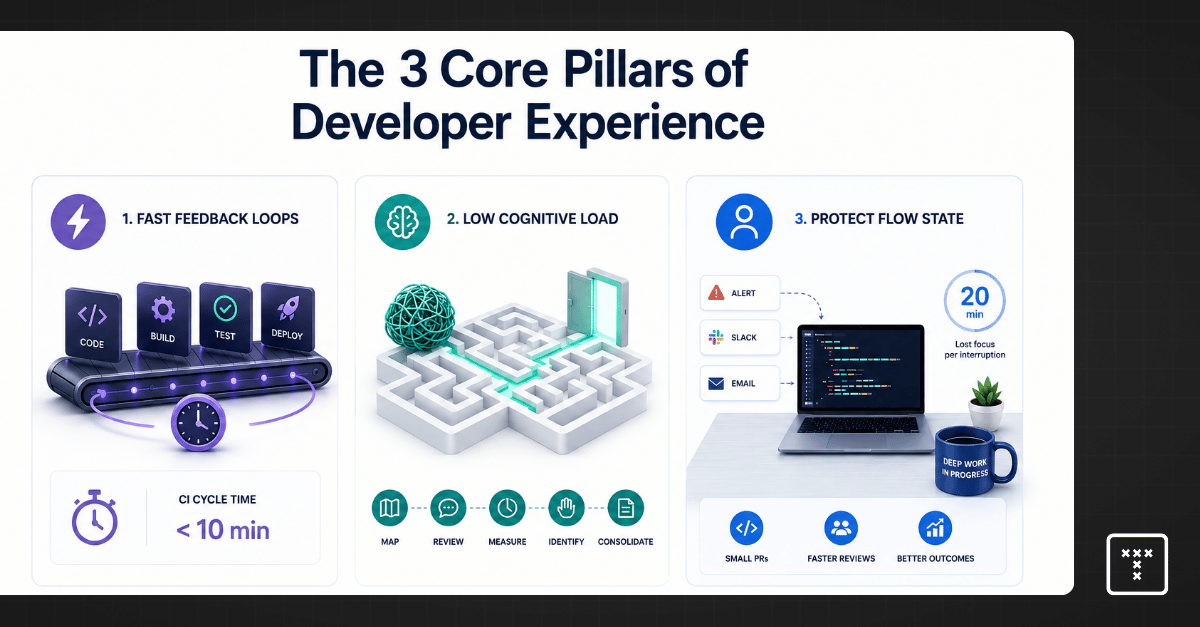
A good Developer Experience (DX) means your team can focus on execution without hitting hidden bottlenecks. Engineering effectiveness drops the moment developer friction increases. You can evaluate the health of your environment by looking at three specific operational pillars that dictate how work actually flows through your systems.
Fast feedback loops are critical for maintaining engineering momentum. Engineers need to know immediately if their code breaks the build. Long build and deployment times force developers to wait, so they lose context and switch to other tasks.
You must optimize your continuous integration and delivery pipelines to return results in minutes. Automated environment setups eliminate manual configuration errors and reduce wait times from hours to minutes. If your continuous integration cycle time exceeds ten minutes, you are actively burning engineering capacity and delaying your release schedule. Fast cycle times are usually a healthy signal, but you must ensure they don't indicate a lack of proper code review.
High cognitive load means your engineers spend more time deciphering complex architecture than writing functional code. Systemic complexity grows silently, and legacy system navigation quickly becomes a major bottleneck for new and existing staff. You can audit this burden using a structured approach to uncover hidden inefficiencies.
Engineering requires deep focus to achieve a productive flow state. Context switching destroys that focus instantly. Every broken pipeline alert or fragmented toolchain forces a developer to drop their current mental model, and regaining that focus takes up to 20 minutes per interruption.
This friction often stems from poor code review practices. Large pull request size and complexity mean reviews take days instead of hours. The author must switch back to the code long after they wrote it, and the reviewer has to dedicate half their afternoon just to understand the changes. Keeping pull requests small and focused protects flow state and accelerates delivery predictability.
When delivery slows down, leaders often look at output metrics instead of workflow inefficiencies and rework. You must identify where developer friction originates to fix the underlying system. Unstable or low-quality code forces engineers into constant firefighting loops, so they spend less time shipping new features and more time managing technical debt.
Generative AI fundamentally changes how your teams build software. The AI impact is massive because the difference between AI-generated vs. human-written code creates a false sense of speed. According to a 2024 GitHub report on AI adoption, an engineer can generate hundreds of lines of code in seconds, but that volume introduces hidden systemic complexity.
This surge in output overwhelms code reviewers and directly causes up to 3x the normal code review churn. The initial velocity looks great on paper, but the downstream reality is a bottleneck of untested logic. AI accelerates output, but it inherently introduces hidden systemic risks if your tooling cannot parse and manage that complexity.
You can't fix systemic issues by only treating the symptoms. Use this framework for root cause analysis to identify exactly where your delivery engine is breaking down.
Engineering leaders often rely on standard benchmarks like DORA metrics or the SPACE framework to track software delivery performance. According to the authors of the SPACE framework in 2021, productivity requires a balanced view of multiple dimensions. According to the 2023 DORA Report, high performers optimize for both speed and stability. These frameworks provide highly valuable signals, but they come with severe practical limitations.
They reveal that performance is changing, but they completely fail to explain why it's changing. Relying purely on lagging metrics or subjective developer sentiment surveys creates blind spots around hidden AI complexity and workflow bottlenecks. You need an operational intelligence layer to connect siloed engineering data and transform those subjective feelings into objective signals.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It creates an operational intelligence layer between data systems and execution. TargetBoard connects fragmented data across planning, code, and delivery systems to surface real-time execution risks before they disrupt predictability.
You need both subjective feelings vs. objective signals to get a complete picture of your engineering operations.
Moving from passive observation to active engineering operations requires a shift in how you use data.
Fixing your environment requires intentional investments in tooling and infrastructure. You must consolidate fragmented tools into internal developer platforms that reduce cognitive load. Proper toolchain integration ensures that data flows smoothly across your organization, so developers don't have to jump between five different applications to complete a single task.
A developer experience engineer builds and maintains the internal tools that keep your delivery engine running. They focus on creating self-service capabilities that allow engineers to provision environments without waiting on IT tickets. This role directly reduces developer onboarding time and eliminates the manual toil that causes burnout.
You can audit your current operations to uncover hidden inefficiencies. Follow these steps to align your engineering practices with delivery predictability.
Mastering developer experience gives you a clear framework to control your software delivery lifecycle. You can stop reacting to delayed releases and start managing the actual workflow friction that slows your teams down. Connecting your fragmented data into a unified operational model protects your engineering effectiveness.
Understanding these patterns gives you the confidence to allocate resources accurately and forecast delivery timelines. You can now present objective operational data to your board and explain exactly why performance is changing, which transforms your engineering organization into a resilient and predictable delivery engine.