Software development analytics historically focused on extracting data from repositories and issue trackers to measure developer output. But counting commits or lines of code often leads to measurement theater. Teams start gaming metrics to satisfy basic developer productivity tools, which corrupts the validity of passive dashboards and obscures actual workflow bottlenecks.
Mandating restrictive time-tracking software is a common leadership mistake in these scenarios. Instead, you need zero-overhead system integrations that capture actual work patterns.
The industry is now evolving toward software engineering intelligence (SEI). This approach connects planning data with code and delivery systems to explain the underlying causes of performance shifts. Leaders no longer want to know how many tickets were closed. They want to know why a critical initiative is at risk of missing its target date.
Industry frameworks provide valuable signals but they don't provide complete understanding. According to foundational DevOps Research and Assessment (DORA) reports, tracking metrics like deployment frequency, Mean Time to Restore (MTTR), and Change Failure Rate (CFR) helps evaluate delivery speed and system reliability. The SPACE framework adds necessary context around developer satisfaction and system efficiency.
Yet these standards share a critical limitation. If cycle time suddenly spikes, a DORA dashboard will flag the delay but it won't highlight the specific bloated pull request causing the bottleneck. Metrics alone can't explain why performance changes. They require an intelligence layer to translate those numerical shifts into operational reality.
Legacy engineering analytics tools operate as read-only mirrors of your data silos. They pull isolated numbers from CI/CD pipelines and Git analytics without linking the underlying workflow data. This leaves operations directors manually exporting spreadsheets to reconcile conflicting numbers before every board meeting.
Operational intelligence fundamentally changes this dynamic. It acts as an active layer that interprets performance continuously, offering system-level visibility across your entire toolchain. By unifying cross-system data, operational intelligence translates raw metrics into predictive analytics. This shift allows engineering leaders to perform immediate root cause analysis on delayed initiatives and elevate their strategy toward true value stream intelligence.
Artificial Intelligence coding assistants dramatically increase engineering output, so they fundamentally alter how work flows through a system. This acceleration introduces a severe predictability gap. AI-generated code often looks structurally sound but carries hidden technical debt that manual review processes weren't designed to catch.
Consider a common scenario from Q3 enterprise deployments. A team adopts AI coding assistants like Copilot or Cursor, and their raw output doubles in two weeks. But this surge in volume overwhelms the senior engineers responsible for approvals. Pull request size balloons, which drives up review wait time and creates massive workflow bottlenecks. Under this load, tracking maintainability trends becomes impossible.
The resulting review churn actively breaks standard delivery cycles because cross-team dependencies stall while waiting for code clearance. AI impact can't be managed by simply measuring output. Leaders must measure how this generated code affects the entire delivery system and where it introduces risk before it gets merged.
Transitioning from manual spreadsheet reporting to automated operational intelligence typically transforms how a leadership team operates. You stop arguing over whose Jira export is correct and start making immediate capacity decisions. But getting there requires evaluating software development analytics tools with a clear implementation framework. A poor Build vs. Buy decision here can trap your team in years of maintenance, so you must establish a predictable path to implementation.
Start by mapping where your engineering data currently lives, since fragmented systems hide the root causes of delivery delays. Fragmented data across issue tracking systems and continuous integration pipelines creates blind spots that hide cross-team dependencies, especially in distributed, hybrid work environments.
You need a platform that natively integrates with your existing toolchain without requiring developers to change their daily habits. Zero-overhead system integrations ensure your data remains accurate and comprehensive.
Next, focus on identifying where work actually gets stuck, because massive code blocks easily stall downstream testers. High PR size directly correlates to increased rework and extended review wait time. When a massive code block sits in review for four days, it actively breaks standard delivery cycles by stalling downstream testers and blocking dependent teams.
You can use code review intelligence to monitor these specific workflow bottlenecks before they compound. Catching PR latency early allows you to reallocate resources and maintain steady delivery momentum.
Finally, your engineering metrics must translate into business value. Evaluate tools based on their ability to track your investment profile, because engineering metrics must translate into defensible business value for the board.
According to the Financial Accounting Standards Board (FASB) ASC 350-40 guidelines for internal-use software, accurate capitalization reporting requires precise tracking of engineering hours dedicated to new features versus maintenance. A strong analytics platform automates this business alignment so you can defend your resource allocation and capacity planning with objective data.
Evaluating engineering management platforms requires understanding their specific strengths. While over 50 developer tracking tools exist, the top software development analytics platforms specialize in distinct operational areas.
Jellyfish excels at translating engineering activity into financial metrics. It helps leaders visualize their investment profile across different product initiatives. This visibility supports accurate capitalization reporting and allows executives to prove the ROI of their R&D investment to the broader business.
LinearB focuses heavily on the operational mechanics of software delivery. The platform identifies workflow bottlenecks by tracking review wait time and overall cycle time. It also provides automation features that route pull requests to the appropriate reviewers, helping teams clear code faster.
GetDX approaches engineering performance through the lens of human qualitative data. The platform measures developer experience (DevEx) by surveying engineers about friction points in their daily workflows. This qualitative approach supports sustainable development by highlighting cultural and tooling issues that quantitative metrics might miss.
TargetBoard provides a comprehensive view of engineering performance by analyzing data across five core dimensions: speed, quality, predictability, AI impact, and team health. This balanced approach allows leaders to move beyond basic metrics and gain a deeper understanding of how their teams execute. By correlating technical output with operational stability, TargetBoard helps organizations optimize their delivery while maintaining a healthy, sustainable development culture.
Standard engineering analytics tools provide valuable signals, but they don't explain why those metrics change or what to do about them. Dashboards force leaders to manually interpret data silos and guess the root cause of fluctuating engineering performance. This passive approach breaks down entirely in the modern era because Artificial Intelligence accelerates output and introduces hidden complexity that traditional tools can't parse.
You need a system that actively drives execution. TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance continuously, and deploys domain-expert AI agents to guide execution decisions. It connects fragmented data across Jira and GitHub to provide a single trusted operational model.
By deploying domain-expert AI agents, TargetBoard continuously monitors software engineering intelligence to detect AI impact and hidden complexity from generated code. This translates raw metrics into proactive, decision-ready inputs that secure your delivery predictability before risk ever enters the codebase.
Understanding these data patterns gives you a clear framework for your next resource allocation decision. You can now transition your organization from reacting to stale dashboard metrics to proactively managing engineering performance.
Keep in mind that no single tool guarantees success, so your operational systems must fundamentally align with your internal engineering culture and processes. Start by auditing your current data silos and identifying where code generation tools are introducing hidden review bottlenecks, which ensures your delivery predictability remains stable as velocity scales.
Cognitive complexity is a software metric that evaluates how difficult it is for a human to read and understand a block of code. It assigns a numerical score based on the presence of structures that interrupt the linear flow of reading. A high score signals that the code is hard to parse.
This directly threatens code maintainability and readability. Developers struggle to understand highly complex modules, so they spend more time deciphering logic than writing new features. This metric prioritizes human-readable code over raw mathematical execution. It helps you pinpoint exactly where subjective review decisions will bottleneck your workflow.
The human brain can only hold a limited amount of information in its working memory. When a developer reads a function, they must mentally track every variable and conditional branch to understand the outcome. Deeply nested logic forces the reader to hold multiple contexts simultaneously.
According to cognitive psychology research on working memory, this spikes their cognitive load. Human-readable code minimizes this mental burden by keeping the execution path as linear as possible. So when you measure how developers perceive information, you are actually measuring how quickly they can safely modify the codebase.
Engineering leaders often confuse these two metrics, yet treating them interchangeably is a common management mistake. Cyclomatic complexity is a strict mathematical measurement of every possible execution path through a program. It counts the number of distinct routes the machine can take.
However, code that is simple for a machine to execute can still be incredibly difficult for a human to read. Cognitive complexity ignores machine paths and focuses entirely on human readability. Understanding cyclomatic vs cognitive complexity is critical for execution predictability because only the latter explains why your team is struggling to review a specific module.
Cognitive complexity is not merely a technical grievance. It is a primary driver of workflow coordination failure. While traditional metrics treat all lines of code as equal, this scoring model exposes the hidden tax that dense, non-linear logic imposes on your delivery pipeline. Every time a developer encounters a break in the linear reading flow, they must pause to mentally map a new branch of logic. This mental mapping consumes time and cognitive energy that should be spent on feature delivery.
When code is structured through deeply nested loops and conditional branches, the difficulty of understanding that code scales exponentially rather than linearly. The operational consequence is a review-system saturation point where senior engineers can no longer verify the safety of a change quickly.
The core friction in engineering organizations often stems from how we penalize or fail to penalize complexity. A flat list of conditional checks is manageable. However, placing those same checks inside a nested loop creates a massive spike in complexity that traditional volume metrics ignore.
Focusing on the mechanics of scoring rules misses the broader strategic point. High complexity scores are leading indicators of delivery trust erosion. When your engineers are trapped in a cycle of deciphering dense logic, they are not building new value.
By monitoring these scores, leadership can identify the specific modules that are driving up the cost of change. Reducing cognitive complexity is not about making code look pretty. It is about lowering the barrier to entry for collaboration and ensuring that coordinated decision-making remains possible even as the system grows. High complexity is a signal that your delivery machine is becoming brittle, and ignoring it is a direct threat to long-term system predictability.
When developers write code quickly, they often build logic sequentially. This habit creates structures that are incredibly difficult to review later. A common example of java cognitive complexity is a single method containing multiple "if" and "else if" blocks nested inside a "while" loop. The machine executes this perfectly, yet a human reviewer must mentally map a massive decision tree just to verify a minor bug fix.
Switch statements and overloaded functions present another common trap. An overloaded function with too many parameters forces the developer to constantly check the signature definition, while a switch statement with twenty cases forces the developer to scroll endlessly to find the relevant logic. Recursive methods also drive up complexity scores because they force the reader to mentally simulate the call stack to understand how the loop eventually terminates.
High complexity doesn't stay contained in your codebase. It leaks directly into your engineering operations and destroys workflow efficiency. When a developer submits a highly complex pull request, the reviewer immediately struggles to understand the logic. This confusion leads to subjective review decisions.
Reviewers leave vague comments, the original author pushes back, and the pull request stalls. This creates a massive pull request (PR) churn. To eliminate these delivery bottlenecks, you need a system that connects code-level metrics to workflow behavior.
The rapid adoption of AI coding assistants fundamentally changes how work is produced. These tools generate massive amounts of code instantly, and this output almost always passes automated unit tests. However, AI models don't optimize for human readability by default.
They often output highly nested, verbose logic. When developers submit this AI-generated code impact without refactoring it, they pass an enormous cognitive burden onto human reviewers. This hidden risk quietly accumulates in your repositories, driving up the long-term codebase cost and slowing down future feature development.
You can't eliminate complexity entirely, but you can systematically reduce it through targeted refactoring techniques. The goal is to flatten the logic so the execution path reads linearly from top to bottom. Implement these steps to clean up high-risk modules.
Refactoring complex code pays immediate operational dividends. When you lower the mental burden required to read a file, developer productivity / DevEx improves dramatically. Engineers spend their time building new features instead of deciphering old logic.
This clarity also accelerates developer onboarding. New hires can read the codebase and start contributing safely in their first week. Most importantly, prioritizing readable code prevents the silent accumulation of technical debt, protecting your team's capacity for future quarters.
Tracking a static complexity score from tools like SonarQube is only the first step. A raw number tells you that a file is hard to read, but it doesn't explain how that file impacts your delivery predictability. To manage risk effectively, engineering operations need system-level visibility.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects granular codebase complexity directly to workflow friction and delivery metrics.
TargetBoard uses domain-expert AI agents to flag high-risk pull requests and surface code review intelligence in real time. This means you stop reacting to delayed cycle time reports and start catching hidden risks before they merge into your main branch.
High cognitive complexity is more than a technical debt marker. It is a direct tax on your operational infrastructure. When code becomes unreadable, it triggers a cascade of organizational drag: reviewer cognitive overload, escalating PR churn, and a permanent onboarding drag that stifles workflow scalability.
Ultimately, maintainability economics dictate your delivery speed. If your team cannot reason about the system efficiently, coordinated decision-making collapses. You must treat human readability as a core pillar of your execution flow. Ignoring this hidden operational friction ensures that complexity will paralyze your organization long before the dashboards flag a crisis.
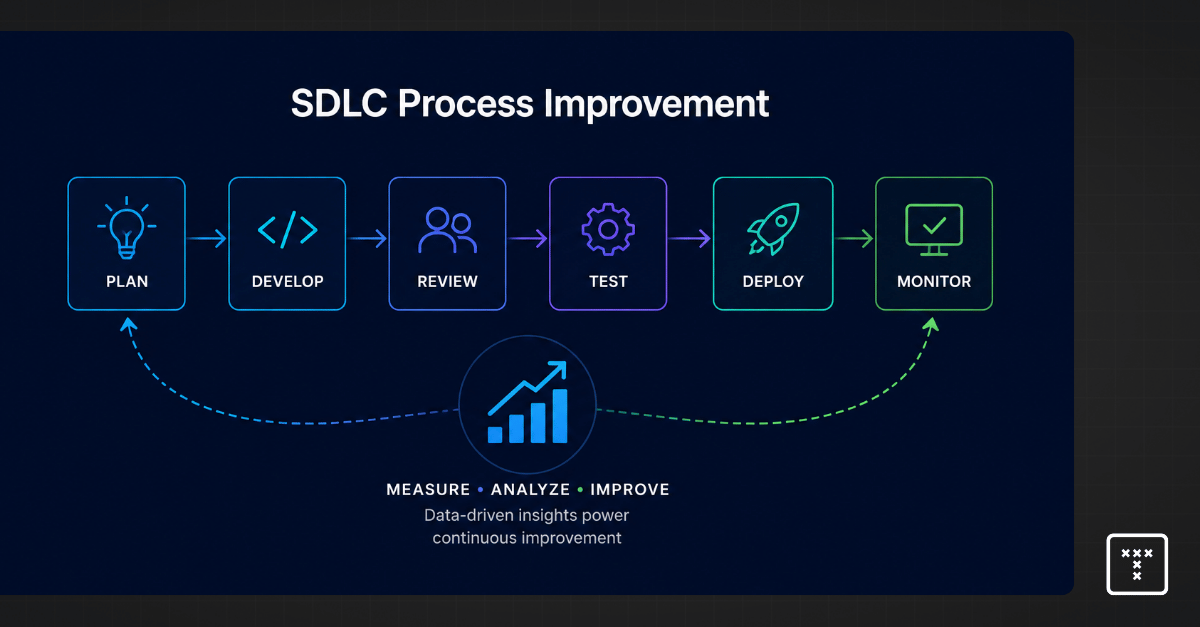
SDLC improvement is the practice of identifying and eliminating workflow bottlenecks across the software delivery lifecycle to increase speed and maintainability. Improving the software development lifecycle traditionally meant adopting continuous integration automation or refining Agile ceremonies.
Today, achieving true SDLC efficiency requires optimizing your end-to-end flow system by focusing on three core areas:
Continuous improvement now depends on treating the delivery pipeline as an interconnected system rather than isolated stages.
Engineering leaders often try to fix delivery delays by adding more continuous integration pipeline automation. They assume faster pipelines will naturally speed up releases, but this ignores the human workflow bottlenecks that actually dictate pace.
Modern software development methodologies now rely heavily on AI coding assistants. These tools allow developers to generate massive volumes of code instantly, which creates catastrophic hidden queues during the code review phase. Reviewers become overwhelmed, and this leads to AI-induced review saturation.
Focusing purely on pipeline automation means you miss the fragmented operational realities happening on the ground. A developer might mark a ticket as complete in Jira, while the actual pull request languishes in GitHub awaiting a senior engineer's approval.
This conflicting data creates a massive blind spot. Relying solely on tracking metrics in this environment leads to missed deadlines because the underlying coordination friction remains completely ignored.
Industry standards like DORA metrics and SPACE frameworks are highly effective at measuring the outcomes of software delivery performance and tracking developer productivity trends. They tell you your deployment frequency dropped or your lead time increased. But these are lagging indicators vs leading signals.
They show you what happened, so they can't explain why it happened or how to fix it. A dashboard might show a 40 percent drop in velocity. It won't tell you that three high-complexity pull requests are blocking your critical path. Frameworks provide signals, yet they don't provide the operational understanding required to make confident execution decisions.
The push for faster development cycles has driven massive adoption of AI tools. AI-generated code contributions often lack the broader architectural context of your system, and this accelerates the accumulation of technical debt.
Balancing code generation speed against long-term maintainability risks is now a primary executive responsibility. If you don't manage this balance, the hidden cost of faster coding will manifest as severe delivery drag down the line.
To improve SDLC process efficiency, engineering leaders must shift their focus from local pipeline metrics to global flow-system optimization. This means identifying workflow bottlenecks across the entire lifecycle rather than just accelerating the coding phase.
Improving SDLC practices requires treating the delivery pipeline as an interconnected system. You can't fix a stalled delivery by pushing developers to code faster when the real constraint sits in the review queue.
Implementing SDLC best practices historically meant adopting Agile methodologies to structure team ceremonies or introducing shift-left testing to catch defects earlier. But optimizing an end-to-end delivery flow requires a completely different approach to governance.
The five steps of process improvement for modern software delivery include baselining your delivery flow, unifying data silos, identifying hidden queues, mapping dependencies, and automating execution signals.
This specific sequence reduces coordination friction and provides the system-level visibility required to make confident execution decisions.
Start by measuring your current cycle time trends across the entire lifecycle because you need a factual baseline of your true delivery speed. You must track a feature from the initial commit all the way through the final deployment phase so you can measure future improvements accurately.
Data trapped in fragmented systems creates severe operational blind spots for leadership. You must implement Jira and GitHub integrations to connect planning data directly with actual code activity. Unifying these data silos ensures your reporting reflects reality rather than just manual ticket updates.
Work often stalls quietly between active development stages. You need to identify hidden queueing systems where code waits for manual approval. Tracking pull request (PR) churn and applying code review intelligence helps you pinpoint the exact workflow bottlenecks causing review saturation across your engineering teams.
A fast engineering team can still miss deadlines if they wait on external approvals. You must map cross-team dependencies to understand exactly where work gets blocked in the broader organization. Resolving this coordination friction is critical for maintaining a predictable delivery cadence.
Manual reporting forces leaders to rely on stale data for critical resource allocation. You must automate actionable execution signals that flag high-risk pull requests and scope creep in real time. This proactive approach directly increases your overall delivery confidence and keeps execution aligned with planning.
Standard frameworks provide signals, but they fail to deliver operational understanding. To achieve predictable delivery, engineering executives need an operational intelligence layer that connects planning, code, and delivery systems seamlessly.
Agentic operational intelligence represents the modern standard for executive decision-making. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond by deploying domain-expert AI agents to guide execution decisions.
You can't fix a bottleneck if you don't know it exists, so TargetBoard creates a unified operational model that removes the guesswork from engineering governance.
Scaling a development organization requires continuous alignment between planning and execution. You must prove engineering ROI by demonstrating that faster code generation translates into quality delivery. Tracking raw output is no longer sufficient for modern technology leadership.
This requires consistent post-deployment measurement to ensure that new AI tools don't degrade system stability. Leaders who govern their delivery systems proactively can scale their teams without accumulating hidden technical debt.
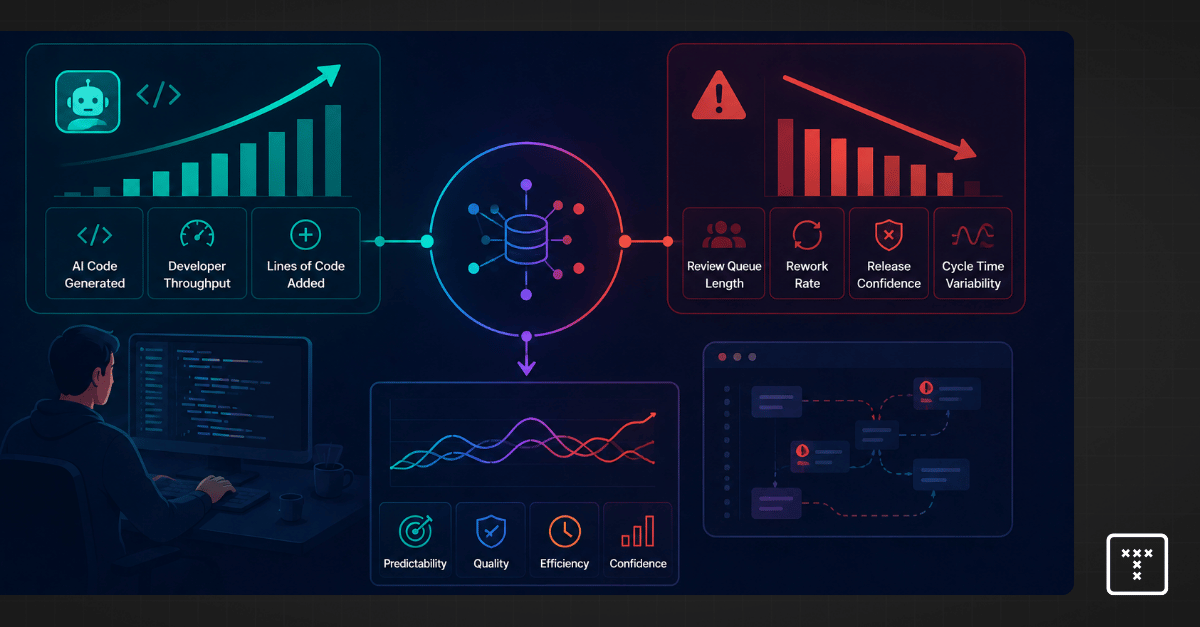
When one part of a system accelerates without upgrading the downstream constraints, the entire system degrades. This is the reality of the engineering management paradox. Developers use AI agents to write code at unprecedented speeds, so the volume of pull requests hits the review stage much faster than human reviewers can process them.
This AI-induced asymmetry breaks the flow of work. You get a massive backlog of unreviewed code, which causes pull request churn and delays. Leaders look at the high output metrics and assume teams are flying, but the delivery timeline keeps slipping.
Code generation volume scales exponentially with AI. Human review limits remain fixed by cognitive capacity and working hours. When you measure code generation volume without measuring the capacity to review it, you create a dangerous imbalance.
Review capacity saturation happens when reviewers are overwhelmed by the sheer size and frequency of pull requests. This forces developers to context-switch constantly, which degrades overall code quality and slows down the merge process.
Metric-gaming and output bias occur when teams are rewarded for merging code faster. Developers might use AI to generate boilerplate code just to hit velocity targets. This creates an illusion of increased developer productivity.
The flow of work matters more than the volume of work. Generating ten features that sit in a testing queue for three weeks doesn't help the business. True productivity requires moving code from a developer's machine into production without breaking the system.
The DevOps Research and Assessment frameworks provide valuable baseline signals for software delivery performance. They track deployment frequency and lead time for changes, but they don't explain why those metrics change.
If your cycle time or time to merge increases, traditional frameworks can't tell you if the delay is caused by complex AI-generated code or a breakdown in cross-team coordination. They measure the symptom, so they mask the underlying AI-induced risk. You need a deeper intelligence layer to understand the root cause of the delay.
Organizations adopting tools like GitHub Copilot or Tabnine often rely on developer sentiment and DevEx surveys to measure AI adoption. Developers often report feeling highly productive when using AI coding assistants. This qualitative data is useful for understanding team morale.
However, developer sentiment often contradicts objective operational signals. A developer might feel fast while writing code, but objective metrics might show that their pull requests require three rounds of rework. You must balance qualitative data vs. objective operational signals to see the true systemic impact.
Tracking the number of lines written or the volume of pull requests created is a flawed approach to measuring ai. Output volume / lines of code don't guarantee a stable delivery pipeline. You must measure the downstream delivery impact of that code.
Systemic execution tracking looks at the entire lifecycle. It measures how code generation affects QA testing, security reviews, and deployment reliability.
Software delivery is a manufacturing pipeline governed by global system constraints. You can apply academic queueing theory directly to the software delivery lifecycle to understand where work gets stuck. Little's Law dictates that the number of items in a system equals the arrival rate multiplied by the time they spend in that system.
AI coding assistants drastically increase the arrival rate of new code, so if the processing time at the review stage remains static, the queue length explodes. I recently watched an engineering organization celebrate a 40 percent increase in code generation, but their review queues expanded so fast that release confidence deteriorated entirely within two sprints.
You must track the exact moment your human reviewers become the bottleneck. Bottleneck detection and resolution require looking at wait states rather than active coding time. When review queues grow too long, developers switch contexts to start new tasks.
This creates severe coordination breakdowns across teams. A front-end team might generate UI components at record speed, yet they can't ship because the backend API review is stalled. I frequently have to reallocate senior engineering resources away from feature development specifically to unblock downstream bottlenecks caused by upstream AI acceleration.
AI often generates highly verbose code blocks that look syntactically correct but lack architectural coherence. Pull request complexity and size naturally inflate when developers rely heavily on generation tools. Reviewers then have to parse massive, unfamiliar logic structures.
This fundamentally alters your execution decisions and tradeoffs. A reviewer facing a 1,200-line AI-generated pull request will likely either rubber-stamp it or reject it entirely out of fatigue. Both outcomes carry a massive downstream delivery impact. Rubber-stamping introduces production defects, and blanket rejections destroy the flow of work.
Measuring ai code assistants requires a complete shift in perspective. You have to stop tracking the sheer volume of developer output. You must focus entirely on execution stability and the operational tradeoffs required to maintain a predictable pipeline.
This systemic AI measurement framework provides a structured model to evaluate how generated code interacts with your existing constraints. It helps you diagnose friction before it stalls your entire engineering department.
The first step is identifying where AI-induced asymmetry occurs between teams. Engineering leaders often make the mistake of using localized metrics out of context to claim an overall productivity increase while systemic stability degrades. One team might use AI to ship rapidly, but they overwhelm a dependent team that lacks the same tools.
You have to map cross-team dependencies to spot these imbalances. High AI output means nothing if cross-team coordination breaks down completely at the integration phase.
Objective measurement requires analyzing what happens after a developer opens a pull request. You must track rework patterns and pull request churn to see if the generated code actually survives peer review.
Direct observation across multiple engineering organizations shows a clear trend. Pull request churn often doubles for AI-generated code compared to human-written code. According to 2024 operations research on software pipelines, high rework rates are the leading cause of release confidence deterioration. You spend more time fixing generated logic than you would have spent writing it manually.
AI introduces a specific type of hidden complexity that easily evades initial code review. The code functions perfectly in isolated tests, yet it creates architectural friction that surfaces later. You have to track codebase health and technical debt to catch this early.
This hidden complexity acts as a long-term engineering drag. A function might be generated in seconds, but it might take hours to refactor when requirements change next quarter. You have to measure the cognitive complexity of the codebase over time to ensure you are not trading long-term maintainability for short-term speed.
Relying on isolated metrics to manage an engineering organization is a losing strategy. Industry frameworks provide useful baseline signals, but true understanding requires an agentic intelligence layer. You need a way to map local AI output directly to downstream workflow bottlenecks and review capacity saturation.
TargetBoard provides this system-level visibility by connecting planning, code, and delivery systems into a single trusted model. It moves you past passive reporting and subjective sentiment. By exposing hidden complexity and AI-induced risk before it slows the team down, TargetBoard gives you the objective operational signals needed to make confident execution decisions.
The current landscape forces engineering leaders into a difficult position. AI creates local acceleration but systemic instability. You can generate code faster than ever before, but that speed actively degrades your global system constraints and systems economics.
The organizations that benefit most from AI will not be the ones generating the most code. They will be the ones that best understand how AI reshapes review capacity, workflow coordination, system stability, and execution outcomes across the entire engineering organization.
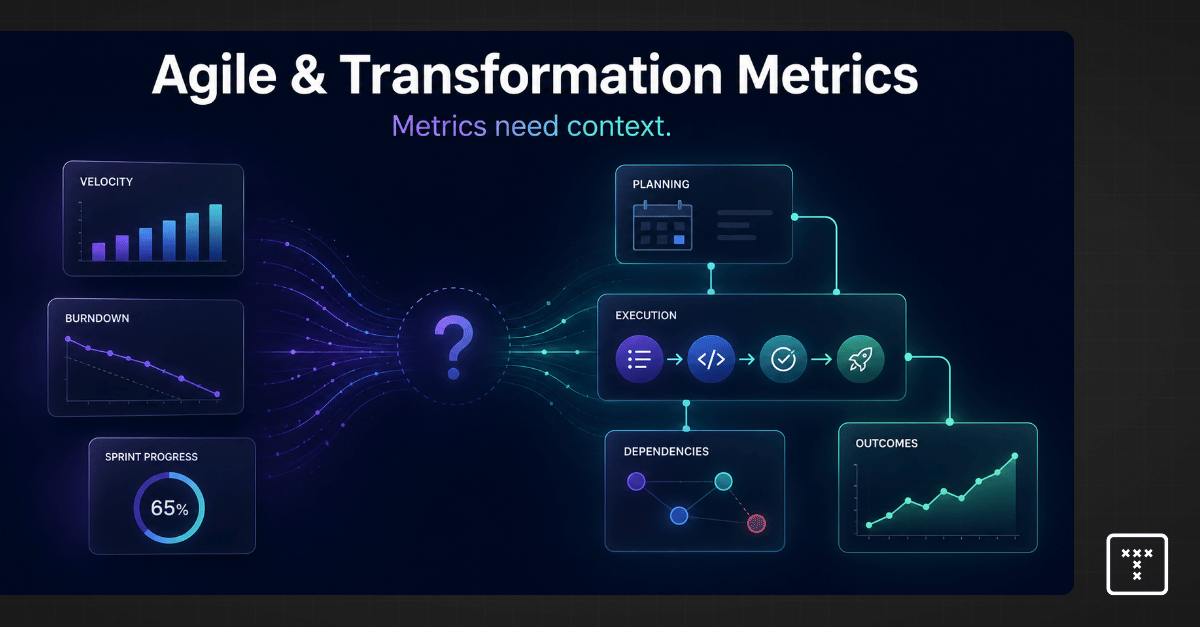
Tracking sprint velocity on a dashboard gives you a false sense of control. These raw numbers easily become vanity metrics when they are disconnected from the actual engineering work. Teams quickly learn how to manipulate the dashboard when leaders only look at surface-level progress tracking.
This dynamic leads to inflated estimations just to show an upward trend. Forcing output to meet an arbitrary target is a dangerous anti-pattern that breaks your delivery process. It prioritizes speed over sustainable architecture and hides real bottlenecks.
Your data silos make this problem much worse. Jira might show a ticket is in progress, yet GitHub shows it's actually stalled in a complex review cycle. You must transition from simply observing disconnected data to actively interpreting it.
Executive leadership often treats KPIs as "truth," when in reality, they are merely symptoms. To lead effectively, you must understand where these metrics provide clarity and where they create dangerous illusions of progress.
Leaders often misinterpret flow as a measure of hustle, failing to see that these numbers are primarily indicators of workflow coordination failures.
Dashboards like burnups and flow diagrams are meant to expose workflow dynamics, yet they are often used merely for status reporting.
Speed without stability is just debt with a different name. Leaders who ignore quality signals in favor of flow metrics are inadvertently funding a future delivery collapse.
The surge in AI-assisted coding has introduced a dangerous era of false confidence for engineering leaders. On a standard dashboard, the acceleration looks spectacular: developers are shipping more code, more frequently, than ever before. However, this raw output masks a fundamental local productivity vs. system stability conflict. While an individual engineer’s throughput may spike, the systemic cost of managing that output often brings the entire delivery machine to a halt.
Traditional forecasting assumptions are breaking because they were built on the premise of human-scale output. AI-generated code creates a black box of hidden complexity that traditional metrics are not designed to flag until a deadline is already missed.
The following table highlights how AI-accelerated development creates review-system saturation and ultimately leads to delivery predictability collapse.
The most significant leadership risk is the false signal of "Green" metrics. A team might show record-breaking velocity, yet their actual progress toward a milestone remains stagnant. This is because AI can solve the "writing" problem while simultaneously exploding the "coordination" problem.
When your metrics focus on code production rather than workflow dynamics, you miss the moment your review pipeline becomes saturated and your senior engineers become overwhelmed. To maintain executive trust, leaders must look past the "AI-productivity" hype and measure the friction that high-speed output creates across the entire delivery lifecycle.
The primary challenge in modern engineering is no longer a lack of data; it is an interpretation gap. Frameworks like DORA or SPACE provide vital signals regarding speed and reliability, but they stop short of explaining the workflow behavior driving those numbers. They can tell you that cycle time has spiked, but they cannot articulate the underlying agile leadership blind spots or the hidden coordination failures that caused the shift.
To reclaim delivery trust, organizations need more than passive reporting. They require a layer of active interpretation that connects planning, execution, and delivery into a single, cohesive narrative. This is where TargetBoard shifts the paradigm – moving from raw data collection to coordinated decision-making.
TargetBoard is an agentic platform designed to expose the "why" behind your agile metrics. It unifies disparate data points into a trusted model, deploying domain-expert AI agents to translate fluctuating signals into actionable executive insights. By identifying the friction between conflicting operational realities, TargetBoard ensures that leaders are no longer reacting to dashboards, but actively steering their organizations based on a deep understanding of team dynamics.
Without a layer of active interpretation, leadership remains trapped in a cycle of reactive management. TargetBoard moves beyond the surface level to expose the systemic issues that standard frameworks miss:
By moving from measurement to interpretation, TargetBoard transforms agile metrics from a source of confusion into a foundation for delivery trust.
A sudden spike in cycle time is a symptom rather than the root cause. You must move past the surface data to uncover the actual bottlenecks and workflow friction. Here is how you can systematically diagnose the delay.
Driving sustainable execution is not a matter of following best practices, but of managing the inherent tensions within a high-pressure delivery environment. Leaders must actively navigate the following operational tradeoffs to ensure that engineering output translates into genuine business value.
Rewarding teams solely for the volume of closed tickets creates a dangerous incentive for local optimization. When throughput is prioritized over quality, teams often bypass rigorous testing or architectural standards to meet immediate quotas.
The most common agile leadership blind spot is the belief that capacity can be expanded through pressure alone. When teams are pushed beyond their sustainable flow, the first thing to suffer is maintainability.
A fast delivery process is a liability if it results in unstable code and a fractured user experience. Speed and stability are not mutually exclusive, but they do require a constant rebalancing of priorities.
Leaders often focus on the performance of individual teams, failing to see how those teams interact within the broader organization.
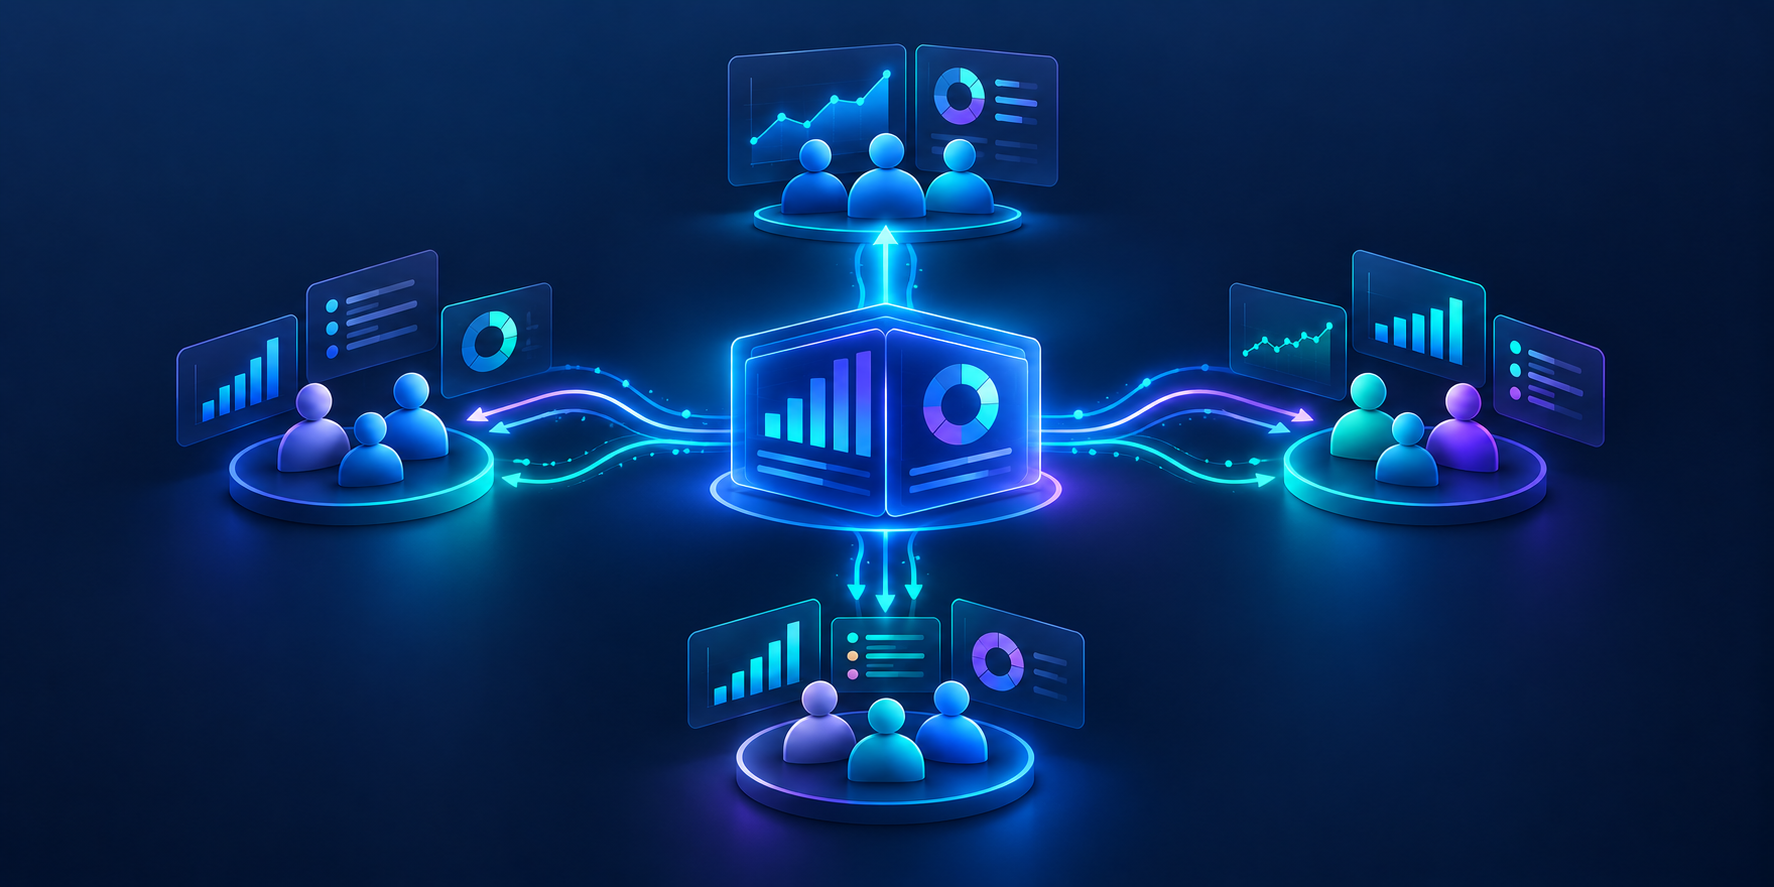
In an era where data drives decisions, the ability to effectively communicate within an organization is more crucial than ever. This communication takes several forms: upward to superiors, downward to teams, and sideways among peers. TargetBoard plans to stands at the forefront of facilitating these diverse communication flows through data.
Upward communication involves conveying information from subordinates to management. In this context, data plays a pivotal role in justifying decisions, presenting results, and suggesting improvements. TargetBoard simplifies this process by providing clear, concise, and compelling data visualizations. This enables employees at all levels to present their findings and insights to upper management effectively, fostering a culture of informed decision-making.
Downward communication is about disseminating information from management to employees. It's essential for creating alignment and directing teams towards common goals. With TargetBoard, leaders can share data-rich, insightful dashboards that clearly articulate goals, progress, and expectations. This approach not only informs teams but also empowers them with the understanding necessary to contribute meaningfully towards organizational objectives.
Sideways or lateral communication is crucial for collaboration among peers. In environments where teams must work together to solve problems and innovate, trust in data and shared understanding are key. TargetBoard fosters this environment by providing a platform where peers can easily share data, insights, and collaborate in real-time. This not only enhances trust but also ensures that problem-solving is grounded in factual, data-driven insights.
Many BI and analytics systems fall short in supporting these types of collaborative communications within a company, often adopting a passive, do-it-yourself, minimalistic approach. TargetBoard is designed to be different. It is not just about presenting data; it’s about creating a space where insights can be shared and acted upon across all levels of your organization. The days of pasting screenshots into management decks are over.
In conclusion, TargetBoard is paving the way for a new era of organizational communication. By enhancing upward, downward, and sideways communication through data, it empowers organizations to operate more cohesively and efficiently. Discover the power of effective communication with TargetBoard. Explore how it can transform your organization's approach to data collaboration.
Employee performance management in modern engineering is the continuous process of aligning software delivery systems to business goals by identifying and removing workflow bottlenecks. It shifts the leadership focus away from isolated developer output and toward systemic execution alignment.
The traditional performance management process relies on individual appraisals, subjective feedback, and isolated activity metrics like lines of code. This outdated approach assumes that maximizing individual effort will automatically result in faster delivery.
The modern engineering approach recognizes that software development is a highly collaborative system. An individual developer might produce code rapidly, but that code can sit in a review queue for days due to complex architecture or cross-team dependencies. Modern performance management measures these systemic workflows to explain why delivery slows down and how leaders can restore predictability.
The standard human resources performance management cycle involves five distinct phases: planning, monitoring, developing, rating, and rewarding. Traditional corporate departments use this continuous feedback loop to evaluate staff and conduct traditional performance reviews.
This framework completely breaks down in agile software development. Tracking individual output ignores the reality of cross-team coordination and hidden technical debt. Software delivery is a complex system, so you can't fix a systemic bottleneck by rating a single developer's isolated metrics.
Modern engineering organizations replace this outdated cycle with an execution alignment model. This updated approach focuses on objective data signals and operational intelligence to drive better delivery decisions.
You know the frustration of unpredictable delivery. You sit in leadership meetings drowning in data silos across Jira and GitHub, yet you still can't explain exactly why velocity is dropping. The immediate instinct is to buy employee monitoring software to see what developers are doing all day. That approach destroys morale and completely misses the mark.
Visibility is no longer the problem, so you need to focus on true understanding. To manage performance effectively, you must stop asking who is working and start identifying where the work is actually stuck. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it's changing, and how to respond.
It acts as the connective tissue that translates fragmented decision-making signals into clear execution priorities without relying on toxic employee surveillance.
CEOs and board members often ask about the top employee performance metrics to track, but tracking individual KPIs like lines of code creates a toxic culture and incentivizes the wrong behaviors. Research indicates that strict individual productivity monitoring actively degrades team morale and reduces overall output by creating environments of low trust.
Studies on agile environments confirm that evaluating a complex system by isolating a single contributor consistently fails to improve delivery speeds². Instead, you need to track systemic workflow key performance indicators that actually impact delivery predictability.
Artificial intelligence is fundamentally changing how work is produced. I recently worked with an engineering organization that rolled out AI coding assistants across their teams. Within a month, their raw code output spiked dramatically. The leadership team initially celebrated this increase in volume, yet their actual delivery timelines quickly ground to a halt.
The problem was a massive bottleneck in the code review phase. The teams were generating code faster than human reviewers could safely validate it. This created a surge in pull request complexity and introduced hidden technical debt into the codebase.
You can't solve this artificial intelligence impact by telling reviewers to work faster. You have to use a systemic performance approach to manage this new complexity gap, ensuring that increased output does not destroy downstream predictability.
Standard measurement frameworks like DORA and SPACE are highly popular in modern engineering. These frameworks provide useful signals about software delivery performance, but they do not provide true operational understanding. A dashboard might show you that your lead time is increasing, yet it will not tell you why that delay is happening or how to fix it.
Metrics without context actively erode engineering team trust. When leaders see numbers shift but can't explain the cause, they make poor decisions based on assumptions.
To find the actual root cause analysis, you must map workflow friction across your systems visually. You might discover that a drop in velocity is not a developer productivity issue, but a cross-team coordination breakdown blocking a critical path.
Engineering leaders face intense pressure to justify their budgets to the board. When you rely on outdated performance appraisals and individual tracking, you can't confidently explain how engineering effort translates into business value. You end up with a frustrated team and skeptical executives.
Transitioning away from individual surveillance and toward systemic execution alignment is the only sustainable way to build operational trust. This shift provides the objective data signals and real-time operational visibility required to empower your teams. When you focus on removing blockers and optimizing workflows, you restore delivery predictability and clearly demonstrate your engineering return on investment.
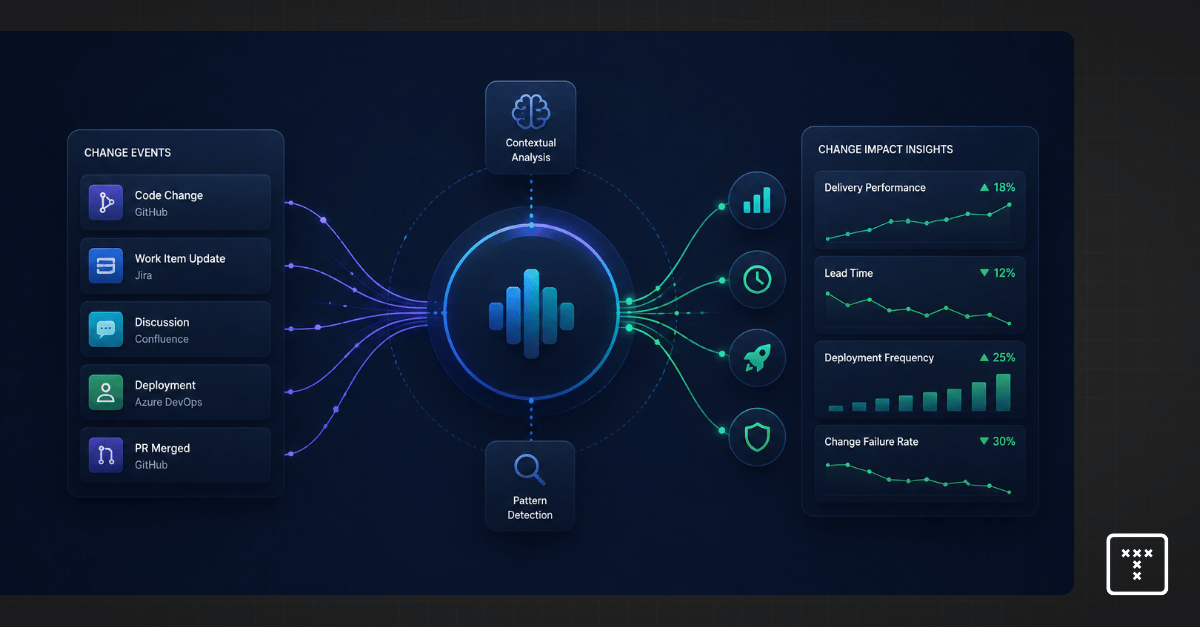
Tracking change management requires measuring how an organization adapts its workflows and delivery systems to new initiatives. Whether you are managing Artificial Intelligence integration or complex mergers and acquisitions, the modern executive approach moves beyond static checklists to analyze real-time execution data. You can track change management tracking initiatives effectively by focusing on three core areas:
This approach ensures you measure the actual impact on delivery predictability rather than just ticking off implementation milestones. It shifts the focus from reactive reporting to proactive performance understanding.
Legacy tracking systems still serve a foundational purpose for basic organizational alignment. They provide a structured way to document project scope adjustments and basic employee readiness. But these tools are strictly administrative. They log the plan rather than measure the reality of execution on the ground.
Most organizations start with standard change management tools to organize their initial rollout. These foundational formats usually include:
These change management templates work well for basic workforce shifts. They break down completely when you need to understand complex engineering workflows and system-level friction.
Measuring change management at the administrative level usually involves tracking adoption rates. Leadership teams look at standard lagging indicators to estimate the Return on Investment for a new tool or process. Common metrics include:
These metrics show if employees are using a new system. They don't reveal if that system is actively damaging your delivery predictability or creating coordination bottlenecks.
An implemented change doesn't equal successful execution adaptation. You might deploy a new Artificial Intelligence tool and see adoption rates hit 90 percent. Administrative change management tools will flag this organizational change initiative as a massive success. But on the ground, your engineering delivery speed might be crawling.
Artificial Intelligence accelerates developer output, which naturally increases the volume of code entering your system. According to a 2024 Forrester analysis on AI-assisted development, this rapid code generation often leads to a massive spike in pull request review churn. Standard tracking tools miss this entirely because they only measure the initial output.
A developer uses the tool to write code faster, so the adoption metric looks great. Yet that highly productive individual output chokes your systemic delivery throughput because human reviewers can't process the complex code fast enough. The result is a severe coordination bottleneck that administrative logs cannot detect.
You must measure how the entire system digests a change. Tracking delivery-system adaptation means looking at the friction between teams. If you introduce a new testing protocol, measuring change management can't stop at confirming the team read the memo.
You need to monitor cycle time trends and review churn to see if the new protocol creates duplicated effort. This requires continuous operational intelligence signals rather than lagging output indicators.
Different tools offer vastly different levels of visibility. Here is how foundational tracking methods compare to modern operational intelligence platforms:
As an engineering leader, you know the frustration of watching delivery metrics drop while adoption metrics rise. Traditional change management tracking only logs that a change occurred. It fails to explain why delivery performance drops or how a systemic change introduces hidden workflow friction.
The primary barrier is no longer the visibility of data. The real challenge is gaining an automated understanding of why that data fluctuates. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert Artificial Intelligence agents to guide execution decisions. This shift from passive reporting to active intelligence restores your decision-confidence. Using modern change management tools requires this level of cross-system understanding to maintain delivery predictability.
The five pillars of change management for engineering execution are alignment for system adaptation, cross-team execution coordination, proactive measurement, risk mitigation, and continuous performance interpretation. These pillars ensure your organizational change initiatives maintain delivery predictability during major transitions.
Foundational models like ADKAR focus heavily on individual awareness and desire. But in complex engineering environments, you must pivot to system-level adaptation. Alignment means ensuring your planning, code, and delivery systems all reflect the new initiative seamlessly.
A change in one department often creates a bottleneck in another. You need strict execution coordination to ensure a new testing framework does not stall your deployment pipeline. Tracking this requires real-time visibility into cross-team dependencies.
You can't wait for lagging output indicators to tell you a project failed. Proactive measuring change management requires continuous operational intelligence signals. This allows you to catch friction early before it compounds into a systemic delay.
Speed often comes at the expense of long-term code cost. You must track how a new process impacts structural complexity and technical debt. Protecting future maintainability ensures your delivery system remains stable long after the initial rollout.
Data without context is useless to an executive. Continuous interpretation means you always know why cycle time trends are shifting. This context gives you the confidence to adjust resource allocation immediately and keep teams aligned.
Measuring the true impact of change management tracking requires a structured approach. Follow these four steps to measure the real Return on Investment of your next transition.
You can't measure impact if your data lives in isolated silos. Connect your Jira, GitHub, and HR systems to create a unified view of your delivery baseline before the change begins. This single source of truth prevents conflicting reports later.
Monitor how quickly teams adopt the new process or software. This provides the initial signal that the rollout is active. Just keep in mind that high adoption rates don't guarantee delivery success.
Compare your current cycle times and review churn against your historical baseline. According to a 2023 Gartner report on digital transformations, over 70 percent of complex change initiatives fail to meet their original speed targets. You must watch these benchmarks closely to avoid becoming part of that statistic.
Assess whether the change created new technical debt or coordination gaps. A successful transition improves systemic throughput without sacrificing the long-term health of your codebase. Connect your code decisions to future maintenance risks to ensure lasting Return on Investment.
Evaluating a transition requires looking past the surface. While the SPACE framework and DORA metrics provide useful high-level signals, they can't explain why those signals change. Here is how traditional measuring change management metrics compare against a systemic operational approach using modern change management tools:
Operational intelligence is a supportive layer that guides your strategy, so it doesn't replace executive human judgment. When you integrate agentic tracking into your change management tracking efforts, you empower your leaders to make objective decisions based on reality.
You stop reacting to stale organizational change initiatives and start proactively managing your delivery pipeline. Understanding these patterns gives you a clear framework to maintain delivery predictability, reduce manual reporting overhead, and build lasting trust with your board.

Software development performance metrics are operational signals that measure how efficiently a team delivers code to production. The industry standard baseline relies on the four core DevOps Research and Assessment metrics. These engineering Key Performance Indicators divide performance into speed and stability.
VPs of Engineering often fall into a scoreboard mentality when tracking these numbers. They spend hours manually aggregating point-in-time reports, treating the metrics as the final goal rather than a diagnostic signal. Improving these software delivery performance metrics requires understanding the workflow friction beneath the numbers. Frameworks provide signals, so they don't provide full understanding on their own. You must connect these signals to actual execution decisions to improve delivery predictability.
Problem: Teams ship features slowly and can't pinpoint where work gets stuck in the pipeline.
Solution: Measure cycle time to identify bottlenecks in the review and deployment phases.
Artificial intelligence code generation fundamentally changes how software is built. Tools like Copilot and Cursor allow developers to write thousands of lines of code in minutes. And this massive increase in raw throughput completely breaks traditional software developer productivity metrics.
You look at your dashboards and see record-high commit volumes. The metrics suggest the team is moving faster than ever, yet overall delivery predictability drops. This happens because increased output actively masks hidden complexity. AI tools generate code quickly, but that code often lacks systemic context. The resulting codebase becomes brittle, and the organization accumulates technical debt faster than human developers can refactor it.
Quantitative data only tells half the story, so engineering leaders must also track qualitative metrics to understand the reality on the ground. Frameworks like the SPACE framework provide a more balanced view by combining qualitative and quantitative data. This approach prevents leaders from optimizing a system to the point of breaking the people running it.
You can't measure system health without measuring Developer Experience. High workflow friction directly degrades how developers feel about their work. When developers constantly fight broken pipelines or wait days for code reviews, their satisfaction plummets and delivery slows down.
Problem: Teams take on too many tasks at once, so context switching destroys their focus and stalls delivery.
Solution: Implement work in progress limits to force completion before starting new tasks and increase delivery confidence.
Enterprise engineering teams still rely on outdated measurement tactics that incentivize the wrong behaviors. Measuring the wrong things creates a toxic culture and actively hides systemic risks.
Tracking lines of code is the fastest way to destroy developer effectiveness. This metric was always flawed, but Artificial Intelligence makes it actively dangerous. AI tools can generate thousands of lines of boilerplate code in seconds. If you measure volume, your metrics will look incredible while your codebase becomes an unmaintainable mess. You need to measure the value delivered to the customer instead of the raw output.
Software development is a complex team operation. Tracking team performance vs. individual performance is a critical distinction. Pitting developers against each other creates a toxic environment where senior engineers refuse to help juniors. If a lead engineer spends all week reviewing pull requests, their individual commit metrics will drop. Yet their work is exactly what keeps the entire system moving. You must measure how the team delivers as a unified unit.
Executives often demand faster delivery without understanding the speed vs. quality tradeoffs. Pushing teams to ship faster without investing in automated testing leads to a massive spike in production failures. The system will eventually grind to a halt under the weight of its own technical debt. True predictability requires balancing feature development with continuous system maintenance.
Dashboard fatigue is a very real problem for modern engineering leaders. You have a Jira dashboard for issue tracking and a GitHub dashboard for pull requests. These Jira and GitHub data silos provide conflicting signals. Jira says the sprint was successful, but GitHub shows massive code review churn.
This disconnect forces leaders to rely on intuition rather than data. You can't make confident execution decisions when your tools refuse to talk to each other. Dashboards are static scoreboards that show you what happened yesterday. They don't tell you why it happened or what you should do about it today.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It unifies performance data across systems into a trusted model and deploys domain-expert AI agents to translate insights into decision-ready inputs that guide execution.
Tracking software development performance metrics isn't the end goal. The goal is to build a reliable delivery system that consistently drives business outcomes. Staring at a static scoreboard won't help you identify the hidden complexity introduced by Artificial Intelligence or the workflow friction slowing down your senior engineers.
You must shift your focus from measuring isolated outputs to understanding your interconnected systems. This systemic visibility gives you a clear framework for your next resource allocation discussion or board meeting. It replaces guesswork with actual delivery predictability. Take a hard look at your current reporting structure and ask yourself if your data actually helps you make better execution decisions, because visibility without action is just overhead. If it just gives you another number to report, it's time to upgrade your operational intelligence.
Value stream management (VSM) is an operational framework that connects business objectives to the software delivery lifecycle. The goal is to optimize how work moves from idea to production, helping leaders identify constraints and improve continuous flow. But tracking work is only the first step.
You must connect those tracking metrics to actual customer value and time-to-market outcomes. When you understand how value flows through your organization, you can stop reacting to delayed releases and start proactively removing the barriers that slow your teams down.
To build a reliable value delivery pipeline, you need to understand the foundational rules of the methodology. These principles guide teams toward predictable delivery and continuous improvement.
Applying these concepts to engineering requires a hard look at how your teams actually work. You likely track engineering performance using standard indicators like cycle time, lead time, and deployment frequency. These numbers provide a baseline for your delivery speed.
But a dashboard showing a spike in lead time doesn't solve the underlying problem. You have to trace that metric back to the specific workflow behaviors causing the delay. This requires connecting data across your planning and code systems to see the reality of your operations.
Workflow friction often hides inside routine development tasks. Consider a scenario where your overall cycle time suddenly spikes by 40 percent. The dashboard flags the delay, but it can't tell you that three high-complexity pull requests have been sitting in the review queue for four days.
The code is written, yet cross-team dependencies and unclear ownership prevent anyone from merging it. This code review churn artificially inflates your cycle time metrics. The work itself isn't slow, but the system is blocked. Identifying these specific constraints allows you to clear the path rather than just asking teams to code faster.
Traditional organizations fund temporary projects, which naturally creates organizational silos. Teams assemble, build a feature, and then disband. This breaks execution alignment and leaves no clear owner for long-term maintenance or technical debt.
Modern value stream management requires a shift toward a product-centric model. You fund stable, cross-functional teams that own a specific product from end to end. This structure improves capacity allocation because you align your best engineers with long-term value delivery rather than temporary task lists. The result is a more resilient delivery engine that adapts quickly to market changes.
Implementing this framework requires a structured approach to analyzing your value streams. You need to connect resource planning directly to your value delivery pipeline. This ensures you are solving the right problems instead of just optimizing isolated tasks.
Value stream mapping is the diagnostic tool you use to visualize how work flows through your organization. Follow these four steps to build an accurate map:
To improve flow efficiency, you must identify where engineering effort goes to waste. Modern software leaders face specific capacity concerns that look very different from physical manufacturing. Here is how the classic seven wastes translate to software delivery.
You can map your workflows perfectly, but legacy tools often fail because they rely on metrics without context. You see cycle time shifting, but you can't explain why execution breaks down. According to a 2023 Gartner report on engineering operations, most leaders struggle because their operational data is trapped in data silos.
This forces executives to rely on subjective updates from managers instead of trusted system-level reality. Tracking metrics provides visibility, but it doesn't provide understanding. TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
This shifts your organization from reactively monitoring dashboards to proactively fixing workflow friction. You gain the power to make confident execution decisions based on reality.
Artificial intelligence code generation accelerates output, so it fundamentally alters how work flows through your system. But higher output often introduces hidden delivery risk. For example, artificial intelligence code frequently experiences higher code review churn than human-written code because it requires intense scrutiny to verify complex logic.
If you only measure output volume, you miss the bottleneck forming in your review stage. This hidden complexity slows down the entire pipeline and delays critical execution decisions.
Tracking DevOps Research and Assessment metrics is a good start, but it's only showing you the symptoms of an inefficient system. You need to diagnose the disease through root cause analysis to achieve predictable delivery.
A common mistake in engineering leadership is treating performance metrics as goals rather than lagging indicators of system health. According to the 2023 Forrester Report on software delivery, teams that focus purely on metric targets often sacrifice long-term stability. When you stop chasing numbers and start focusing on resolving the underlying workflow constraints, your delivery confidence naturally improves.
This operational shift connects daily engineering tasks directly to broader business outcomes. By treating visibility as a starting point rather than the finish line, you create a culture of continuous improvement that actually scales. Understanding your system gives you a clear framework for your next planning session or your next board meeting.
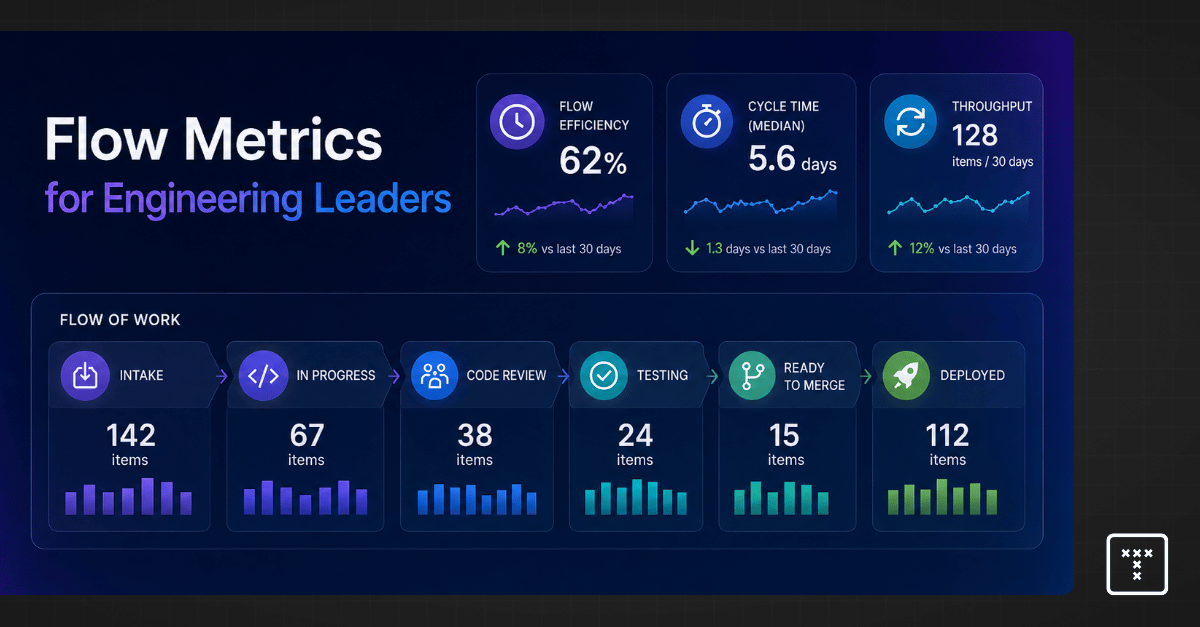
Understanding flow metrics means looking at how value moves from an initial idea to time-to-revenue. These metrics track work across the end-to-end value stream to help leaders spot hidden blockages before they impact delivery predictability. They provide clear signals about where workflow friction occurs, so you can diagnose system stress instead of blaming individual developers.
The 4 key flow metrics provide a foundational view of delivery health and system capacity.
The flow framework metrics defined by Dr. Mik Kersten offer a more specific lens for analyzing engineering performance signals.¹
Teams shipping 50+ deployments a week boast excellent DORA scores while struggling with terrible software delivery predictability. A team might deploy multiple times a day, yet their overall flow load is massive and critical features are constantly delayed.
This happens because DORA relies on point-in-time metrics that measure output events rather than the continuous progression of work across the development lifecycle. DORA shows you how fast you ship, while flow metrics reveal how work actually moves. Relying solely on speed creates proxy metrics limitations that hide the true cost of context switching.
DORA metrics focus purely on deployment speed and operational stability, originally established by the DevOps Research and Assessment team.²
DORA metrics and flow metrics act as complementary engineering performance signals. DORA measures the final mechanical steps of software delivery, focusing entirely on speed and stability. Measuring flow focuses on the entire value stream, tracking how work moves through cross-team dependencies from planning to execution.
When you combine both, you can see the delivery tradeoffs teams make. For example, a team might inflate deployment frequency by shipping tiny updates while larger feature requests rot in the backlog. Flow metrics expose these behaviors, giving leaders the context needed to make confident capacity decisions.
Identifying execution bottlenecks requires shifting from passive observation to active capacity allocation. When you spot workflow friction, you need a systematic approach to clear it and drive continuous improvement.
One of the most common bottlenecks occurs during the code review process. When you analyze wait time vs. active time, you often find that pull requests sit idle for days before receiving a review. This delay usually stems from subjective review decisions or massive PR sizes that intimidate reviewers.
Tracking Work Item Age helps you spot these stalled reviews early, allowing you to step in and facilitate delivery risk mitigation. By addressing code review risk directly, you prevent minor delays from snowballing into missed release dates. Tracking a specific pull request's age recently helped one engineering team prevent a critical release delay by highlighting a PR stuck in an endless, subjective review loop.
High Work in Progress directly correlates with reduced throughput. When Flow Load spikes, teams spend more time context-switching than actually writing code. You need system-level visibility to enforce strict WIP limits and stabilize the delivery pipeline.
AI tools allow developers to generate code faster than ever, yet this speed often creates throughput anomalies. You might see a massive increase in tickets closed, so you assume productivity is up. This artificial output spike often hides a surge in AI-generated code complexity.
Reviewers simply can't keep up with the volume. This bottleneck tanks flow efficiency and causes massive rework churn. You end up with a pipeline stuffed with code that is fast to write but incredibly slow to review, test, and merge.
Cycle time and throughput act as trailing indicators. By the time they show a slowdown, the damage is already done. AI accelerates the creation of new features, but it also accelerates technical debt accumulation. When developers push complex AI-assisted pull requests, they introduce hidden complexity into the codebase.
Over time, your team spends more time fixing bugs than building features. This shifts your capacity from value demand to failure demand, slowly strangling your delivery pipeline. You need visibility into code complexity before it merges, or your future delivery predictability will collapse.
Flow metrics are incredibly useful for spotting system stress, but optimizing for them in isolation creates a massive blind spot. Frameworks provide signals. They do not provide understanding. A metric dashboard might tell you that cycle time is up, but it can't explain that three high-complexity AI-generated pull requests are stalled in code review.
When you rely on data silos and fragmented reporting, executive decision-making becomes a guessing game. Leaders see the numbers shift but can't explain why, which erodes trust across the organization. To fix this, you must bridge the gap between static measurement and operational intelligence.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects cross-system data to continuously analyze performance, translating raw signals directly into decision-centric execution actions.
You can't achieve predictable delivery by simply staring at charts. True execution alignment requires connecting your planning data directly to your codebase. When you rely solely on passive measurement across the software delivery lifecycle, you risk optimizing the wrong things. Some teams even game throughput by breaking tickets into artificially small chunks without actually improving value delivery.
The mathematical realities of Little's Law dictate that cycle time equals work in progress divided by throughput. If you allow work in progress to expand indefinitely, cycle time mathematically must increase. You must shift from reporting on the past to predicting the future, using active intelligence to manage flow load and guide your daily operations.
Developer experience defines the operational reality of how engineers interact with your technical infrastructure to build and ship code. It measures the level of friction in daily workflows and directly impacts software delivery performance. A poor dev experience means your team spends more time fighting internal systems than solving actual business problems.
Board members and C-suite leaders often mistakenly treat what is developer experience as a cultural or HR initiative focused on office perks. You must treat developer experience as the UX for your engineering team. If the internal systems are slow or siloed, your team can't ship predictably.
You might notice a high-complexity pull request sitting in review for multiple days. That isn't a motivation problem. It's pure organizational drag caused by poor system design.
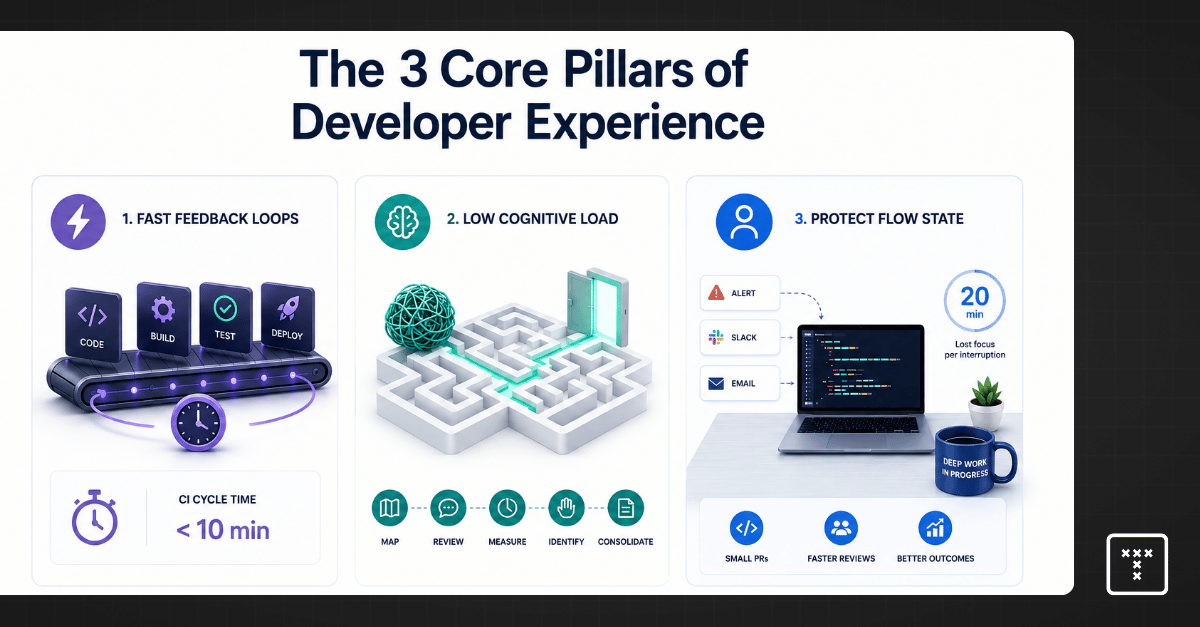
A good Developer Experience (DX) means your team can focus on execution without hitting hidden bottlenecks. Engineering effectiveness drops the moment developer friction increases. You can evaluate the health of your environment by looking at three specific operational pillars that dictate how work actually flows through your systems.
Fast feedback loops are critical for maintaining engineering momentum. Engineers need to know immediately if their code breaks the build. Long build and deployment times force developers to wait, so they lose context and switch to other tasks.
You must optimize your continuous integration and delivery pipelines to return results in minutes. Automated environment setups eliminate manual configuration errors and reduce wait times from hours to minutes. If your continuous integration cycle time exceeds ten minutes, you are actively burning engineering capacity and delaying your release schedule. Fast cycle times are usually a healthy signal, but you must ensure they don't indicate a lack of proper code review.
High cognitive load means your engineers spend more time deciphering complex architecture than writing functional code. Systemic complexity grows silently, and legacy system navigation quickly becomes a major bottleneck for new and existing staff. You can audit this burden using a structured approach to uncover hidden inefficiencies.
Engineering requires deep focus to achieve a productive flow state. Context switching destroys that focus instantly. Every broken pipeline alert or fragmented toolchain forces a developer to drop their current mental model, and regaining that focus takes up to 20 minutes per interruption.
This friction often stems from poor code review practices. Large pull request size and complexity mean reviews take days instead of hours. The author must switch back to the code long after they wrote it, and the reviewer has to dedicate half their afternoon just to understand the changes. Keeping pull requests small and focused protects flow state and accelerates delivery predictability.
When delivery slows down, leaders often look at output metrics instead of workflow inefficiencies and rework. You must identify where developer friction originates to fix the underlying system. Unstable or low-quality code forces engineers into constant firefighting loops, so they spend less time shipping new features and more time managing technical debt.
Generative AI fundamentally changes how your teams build software. The AI impact is massive because the difference between AI-generated vs. human-written code creates a false sense of speed. According to a 2024 GitHub report on AI adoption, an engineer can generate hundreds of lines of code in seconds, but that volume introduces hidden systemic complexity.
This surge in output overwhelms code reviewers and directly causes up to 3x the normal code review churn. The initial velocity looks great on paper, but the downstream reality is a bottleneck of untested logic. AI accelerates output, but it inherently introduces hidden systemic risks if your tooling cannot parse and manage that complexity.
You can't fix systemic issues by only treating the symptoms. Use this framework for root cause analysis to identify exactly where your delivery engine is breaking down.
Engineering leaders often rely on standard benchmarks like DORA metrics or the SPACE framework to track software delivery performance. According to the authors of the SPACE framework in 2021, productivity requires a balanced view of multiple dimensions. According to the 2023 DORA Report, high performers optimize for both speed and stability. These frameworks provide highly valuable signals, but they come with severe practical limitations.
They reveal that performance is changing, but they completely fail to explain why it's changing. Relying purely on lagging metrics or subjective developer sentiment surveys creates blind spots around hidden AI complexity and workflow bottlenecks. You need an operational intelligence layer to connect siloed engineering data and transform those subjective feelings into objective signals.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It creates an operational intelligence layer between data systems and execution. TargetBoard connects fragmented data across planning, code, and delivery systems to surface real-time execution risks before they disrupt predictability.
You need both subjective feelings vs. objective signals to get a complete picture of your engineering operations.
Moving from passive observation to active engineering operations requires a shift in how you use data.
Fixing your environment requires intentional investments in tooling and infrastructure. You must consolidate fragmented tools into internal developer platforms that reduce cognitive load. Proper toolchain integration ensures that data flows smoothly across your organization, so developers don't have to jump between five different applications to complete a single task.
A developer experience engineer builds and maintains the internal tools that keep your delivery engine running. They focus on creating self-service capabilities that allow engineers to provision environments without waiting on IT tickets. This role directly reduces developer onboarding time and eliminates the manual toil that causes burnout.
You can audit your current operations to uncover hidden inefficiencies. Follow these steps to align your engineering practices with delivery predictability.
Mastering developer experience gives you a clear framework to control your software delivery lifecycle. You can stop reacting to delayed releases and start managing the actual workflow friction that slows your teams down. Connecting your fragmented data into a unified operational model protects your engineering effectiveness.
Understanding these patterns gives you the confidence to allocate resources accurately and forecast delivery timelines. You can now present objective operational data to your board and explain exactly why performance is changing, which transforms your engineering organization into a resilient and predictable delivery engine.
Quick Answer: Platform engineering is the discipline of designing and building self-service workflows to minimize cognitive load for developers.
At its core, an internal developer platform provides:
This approach allows stream-aligned teams to ship code faster without managing underlying operational complexities.
Engineering departments often confuse these roles, and defining clear boundaries is critical for resource allocation. Platform engineers build the paved roads, and DevOps philosophies influence how those roads operate. Without a dedicated platform team, developers often get stuck managing shadow operations instead of writing product code.
Treating the internal developer platform as a mandatory IT project often leads to poor adoption. The Platform as a Product mindset shifts this approach by treating developers as actual customers. Key characteristics include:
The demand for the platform engineering discipline has surged because organizations are struggling to manage the AI impact on software delivery. Developers use artificial intelligence to generate massive volumes of code rapidly, so raw output metrics look incredibly high. But this AI-generated code often introduces hidden complexity and technical debt into the codebase.
Reviewers are forced to spend days validating auto-generated logic. This creates massive workflow friction where code writing is fast but merging is painfully slow. Platform engineering teams are now essential for building the guardrails needed to manage this code surge without sacrificing delivery predictability.
When developers submit highly complex pull requests generated by artificial intelligence, human reviewers can't process them efficiently. This mismatch causes severe workflow bottlenecks that directly inflate cycle time. Pull request churn increases as reviewers request continuous changes to understand the automated logic.
This rework and duplication stall progress across the entire department. When one stream-aligned team gets stuck in an endless review cycle, cross-team dependencies break down. You can't forecast delivery timelines accurately when massive code outputs sit unmerged in fragmented systems.
Platform engineering directly shapes software delivery performance by removing the operational hurdles that slow teams down. A well-designed platform improves execution predictability by:
Golden paths are highly opinionated, supported approaches for building and deploying software. By standardizing these paved roads, platform teams achieve specific outcomes:
Security checks often act as a massive roadblock right before a product launch. Relying on manual approvals and traditional ticket ops forces developers to wait days for a security review, and this actively delays critical releases. Platform engineering solves this by embedding security and compliance guardrails directly into Continuous Integration and Continuous Deployment pipelines.
Developers receive immediate feedback on vulnerabilities while they are still writing code. This shifts security left and eliminates the late-stage friction that frustrates stream-aligned teams.
To evaluate delivery tradeoffs and manage resource allocation effectively, engineering leaders rely on a structured approach to building platforms. According to the Cloud Native Computing Foundation (CNCF) framework, a robust platform requires specific functional areas to operate smoothly^1. These six pillars form the foundation of a predictable delivery system.
A self-service portal provides a single interface for developers to access tools and documentation without filing IT tickets. This centralization reduces context switching so teams can ship features faster.
This pillar automates the setup of cloud resources and deployment environments. You must clearly delineate between basic infrastructure orchestration, which just spins up servers, and advanced operational intelligence, which monitors how efficiently those systems support delivery.
Standardized pipelines govern how code moves from a local commit to a production deployment. Platform teams build these automated routes to ensure every stream-aligned team follows the same reliable path to production.
Automated security checks run in the background to prevent vulnerable code from advancing. This eliminates the need for manual security reviews right before a critical launch.
Observability tools provide real-time visibility into application health and infrastructure performance. If a deployment causes an issue, the platform automatically flags the root cause so developers can resolve it immediately.
Platform teams must track adoption rates and identify workflow bottlenecks to continuously improve the platform. This data proves whether the internal developer platform is actually reducing friction or just shifting the burden to a different system.
Problem: CTOs and engineering leaders often rely on subjective developer surveys or standard engineering metrics to gauge success. These metrics provide useful signals, but they fail to explain why performance is changing or where hidden workflow bottlenecks live within data silos.
Solution: You need an operational intelligence layer to connect fragmented data and track the actual business impact of your platform. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
It connects data across company systems and uses domain-expert artificial intelligence agents to guide execution decisions. Instead of looking at a static dashboard showing an unexplained drop in velocity, TargetBoard surfaces the exact workflow friction causing the delay so you can act immediately and improve system-level visibility.
Tracking engineering effectiveness requires a mix of output metrics and deep execution signals. You must measure how fast work moves and understand the context behind those movements to drive predictable delivery outcomes.
Standard DevOps Research and Assessment frameworks measure critical aspects of software delivery performance. They are excellent supporting signals for your organization. But they don't provide system-level visibility into why a team missed a deadline or why a specific repository is suddenly generating massive technical debt.
Consider the edge case where auto-generated code introduces hidden structural complexity. Standard delivery metrics entirely miss this technical debt until it causes a production incident months later. To truly measure engineering effectiveness, you must transition to operational intelligence that connects signals across planning, code, and delivery systems.
According to Gartner research, most software engineering organizations will establish platform engineering teams by 2026^2. But the platform engineering discipline requires internal cultural shifts and disciplined adoption. It's never just about purchasing software and hoping for a productivity spike.
Referencing Team Topologies provides a strong structural foundation for designing successful platform teams that interact smoothly with the rest of your engineering department^3. When you combine a well-structured platform team with proactive operational intelligence, you stop reacting to stale data. You gain the execution predictability needed to lead with complete confidence.
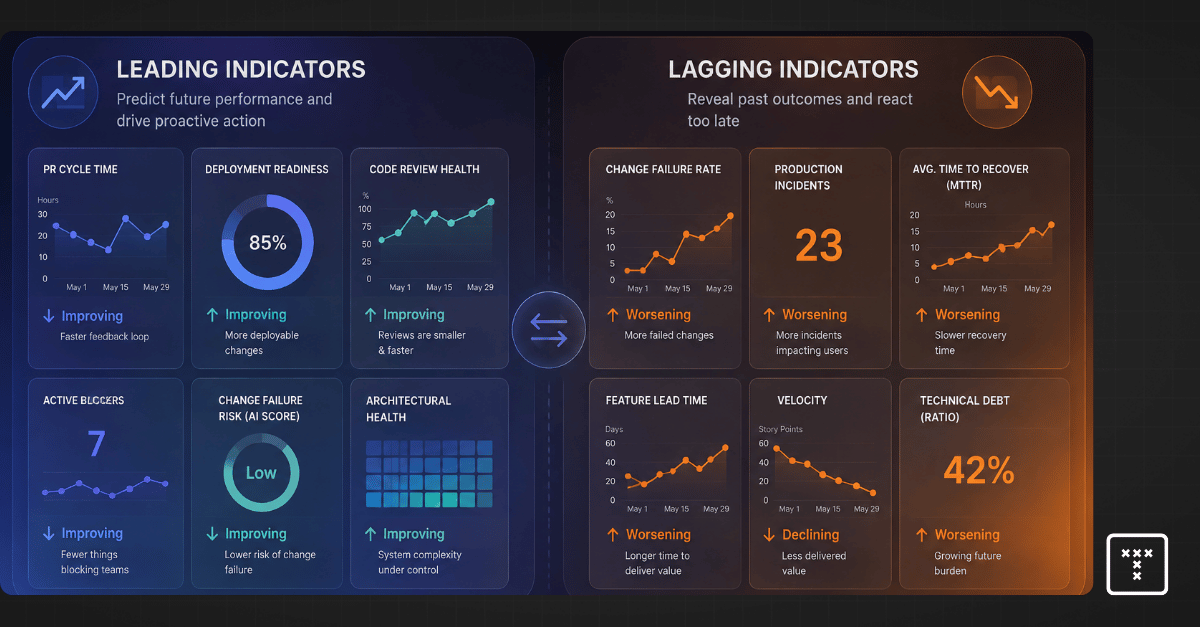
Leading and lagging indicators are the two primary data categories used to evaluate engineering performance. Lagging indicators measure the final results of a process after it concludes. Leading indicators measure the upstream activities and inputs that predict those future results.
Think of this dynamic through the classic windshield versus rearview mirror analogy because it clarifies how you use the data to make decisions. Leading indicators are forward-looking metrics that act as your windshield, helping you anticipate the road ahead. Lagging indicators are backward-looking metrics that serve as your rearview mirror, showing you exactly where you have been. You need both, so you can make accurate execution decisions.
You can quickly audit your current reporting dashboards to evaluate leading versus lagging indicators. Ask these diagnostic questions to determine if your data provides actionable insights or just a historical record:
Investopedia and standard corporate glossaries focus on marketing or sales data when defining leading and lagging indicators. Engineering executives need specific engineering performance metrics mapped to the software delivery lifecycle.
Lagging indicators confirm the final results of the software delivery lifecycle. They are essential for aligning engineering efforts with broader business outcomes. These metrics tell you if a project shipped on time or if a release met quality standards.
Platform engineering teams also track coincident indicators, which measure activity happening right now. The core value of a lagging indicator remains its definitive proof of past performance. Common examples include total bugs found in production and final release frequency.
Leading indicators highlight the friction points happening right now that will inevitably impact your final delivery metrics. These signals allow you to intervene early. If you track Pull Request size and complexity, you can predict which code reviews will stall.
High review churn acts as a clear warning sign, often predicting technical debt and poor code quality. Monitoring cross-team dependencies helps you spot coordination bottlenecks before they derail an entire release timeline. Managing these inputs gives you direct control over the eventual outcomes.
Standard measurement frameworks provide valuable signals about overall organizational health, but they lack the operational understanding needed to drive daily execution. CTOs and VPs of Engineering have experienced the frustration of presenting stalled delivery metrics to a board while their dashboard shows green across the board. Delivery can suddenly halt despite good past metrics because standard tools lack systemic visibility. They force you into a state of reactive management.
This gap becomes critical when teams introduce AI-generated code into their workflows. AI tools dramatically increase code output volume, which creates a false sense of speed. That sheer volume introduces hidden complexity and massive review bottlenecks that standard frameworks fail to catch until cycle time completely collapses. Output volume isn't the same thing as delivery predictability.
You can't manage a modern engineering organization by looking at outcomes alone. You must establish a clear cause-and-effect relationship between your daily engineering activities and your final business results.
Tracking both lead and lag indicators allows you to perform root cause analysis in real time. If you see a predictive signal flashing red, you can course-correct before the sprint fails. According to the 2023 Forrester Research report on engineering operations, teams that actively monitor upstream workflow friction achieve significantly higher delivery predictability than teams tracking only final deployment rates.
Engineering executives know they must track predictive signals to prevent delivery failures. The reality is that manually piecing together fragmented data across tools like Jira and GitHub to compare lagging vs leading indicators is completely unsustainable. You often end up with conflicting signals where Jira shows a project on track while GitHub shows massive review delays.
To truly act on predictive signals, leaders need a system that automatically connects cross-system workflow behavior to delivery metrics to explain why performance is changing. This requires an evolution from passive observation to active intervention.
By unifying this fragmented data, an operational intelligence layer gives you the context needed to make confident execution decisions. You stop relying on stale reports and start managing the actual flow of work.
Understanding the difference between outcome metrics and predictive signals changes how you run your engineering organization. You gain the ability to measure and manage performance based on operational reality rather than retrospective reporting.
This approach gives you a clear framework for technical risk mitigation and smarter resource allocation. By monitoring workflow friction early, you protect your long-term maintainability rather than waiting for a North Star Metric to drop at the end of the quarter. You stop reacting to missed deadlines and start actively guiding your engineering systems toward predictable and sustainable delivery.
Engineering analytics is the practice of analyzing data from the software development pipeline to understand and improve software delivery performance. It connects fragmented data points across issue trackers and code repositories to give leaders systemic visibility.
The goal is to move beyond simply measuring output and start governing the entire delivery system. This continuous evaluation of engineering metrics helps organizations identify bottlenecks and align daily work with strategic business outcomes.
Search results often mix these two distinct concepts. Analytics engineering is a specific job title within the modern data stack. These professionals build and maintain the data pipelines that data scientists use for business intelligence.
Engineering analytics is an operational discipline used by technical executives. VPs of Engineering and CTOs use this discipline to monitor workflow bottlenecks and maintain delivery predictability.
Imagine staring at a dashboard on Friday afternoon during a critical delivery cycle. Deployment frequency looks healthy, yet lead time for changes has doubled. Your engineering managers spent hours dealing with manual reporting overhead to build this view, but the dashboard can't explain the root cause of the delay.
This highlights the fundamental problem with passive reporting. Dashboards give you metrics without context. They show a snapshot of past performance but offer zero actionable insights to resolve the workflow friction. Analytics requires an operational intelligence layer to interpret those signals and guide your response.
Understanding the evolution of data maturity helps clarify why dashboards fall short. The industry breaks analytics into four operational stages.
AI coding tools are fundamentally changing how work is produced. They accelerate initial output, so developers ship more volume in less time. Traditional developer productivity frameworks look at this spike in velocity and assume the system is highly efficient.
But this volume introduces massive hidden complexity. The difference between AI-generated code vs. human-written code often shows up during the review phase. An AI tool might write a feature in ten minutes, but that high-complexity pull request can sit in review for four days. Human reviewers struggle to validate the dense logic, creating severe workflow friction.
The deployment metrics look temporarily inflated, yet technical debt quietly accumulates in the background. The delivery system slows down over time as developers spend hours untangling complex PRs instead of writing new features. You can't manage this new reality with basic dashboards because they measure the speed of creation while completely missing the downstream cost of code review.
The core issue is no longer a lack of visibility. Jira and GitHub provide enough raw data to achieve system-level visibility, yet engineering leaders still lack objective understanding. You need a reliable way to turn conflicting metrics into clear execution decisions without relying on manual analysis or guesswork.
TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance continuously, and uses domain-expert AI agents to guide execution decisions. It automatically interprets fragmented data across your tools to uncover hidden issues like PR churn.
This intelligence layer surfaces decision-ready insights for leaders. You can restore delivery predictability and identify bottlenecks objectively, allowing your teams to stop reacting to stale reports and start addressing workflow friction as it happens.
VPs of Engineering mistakenly treat deployment metrics as a complete measure of developer productivity rather than just a starting signal. According to the 2023 DORA report, elite performing teams prioritize delivery predictability and system reliability alongside raw speed. Frameworks like DORA metrics and the SPACE framework provide valuable benchmarks for these outcomes.
But these frameworks don't provide systemic understanding. They tell you that a metric shifted, yet they can't isolate the root cause behind the shift. You need an active intelligence layer to connect those framework signals to actual workflow behavior.
Real execution decisions happen when you connect data to specific workflow bottlenecks. Consider a sprint where cycle time spikes by 40 percent. A basic dashboard simply reports the delay, but operational intelligence reveals the actual mechanics.
According to 2023 industry benchmarks from LinearB, pull request review time accounts for 70 percent of delivery delays. In this scenario, three high-complexity pull requests sat in review for over four days due to cross-team dependencies, directly causing that 40 percent cycle time spike. Identifying pull request (PR) churn at this granular level allows you to reallocate senior engineers to clear the backlog immediately.
Selecting the right platform requires evaluating how well it moves your organization from reactive reporting to proactive governance. Modern engineering analytics systems and engineering analytics tools fall into three primary categories. You need a unified source of truth to manage complex delivery pipelines effectively.
Relying on output metrics alone creates a false sense of security, especially when AI tools inflate short-term velocity. True organizational improvement requires understanding how work flows through your entire delivery pipeline. Shifting from passive dashboards to operational intelligence gives you the context needed to drive execution alignment.
Understanding these patterns gives you a clear framework for your next resource allocation decision. You can stop reacting to delayed reports and start managing delivery predictability proactively.
Problem: Teams often prioritize short-term deadlines over sustainable software architecture to meet immediate market demands. This creates hidden structural compromises within the codebase.
Solution: Engineering leaders must treat this deferred maintenance as a measurable business liability that directly impacts engineering velocity and resource allocation.
Software developer Ward Cunningham coined the financial analogy of technical debt to explain this dynamic. Borrowing time to release faster is a perfectly acceptable business strategy, but you incur interest on that loan.
You must pay down the principal through regular software maintenance. If you fail to do this, the compounding interest eventually paralyzes the engineering team. Every new feature requires modifying fragile code, so the cost of future changes becomes prohibitively expensive.
Unmanaged debt inevitably causes critical missed delivery targets. A VP of Engineering might commit to a Q3 product launch based on current team capacity. But technical drag from a legacy billing module quickly causes endless pull request churn.
Developer productivity plummets as engineers spend weeks untangling fragile logic instead of building new capabilities. The result is severe system instability and missed business outcomes. Slower feature releases give competitors the advantage and directly impact revenue pacing.
Engineering leaders categorize tech debt by analyzing the intent behind the decision and the context in which it occurs. This framework helps teams distinguish between strategic technical tradeoffs and simple carelessness.
This occurs when a team explicitly knows the right way to build a feature but chooses the wrong way just to meet short-term deadlines. They might hardcode values or skip essential automated testing entirely.
The team makes these technical tradeoffs without any plan to fix the underlying issues later. This behavior signals a toxic engineering culture and guarantees future delivery failures.
Strategic leaders use this category as a calculated business lever. A team might choose a monolithic architecture over microservices to test a minimum viable product and accelerate time-to-market.
The leadership team understands the limitations and actively schedules future sprints to pay down the debt once the product proves its value. This approach aligns engineering efficiency directly with positive business outcomes.
This debt accumulates when teams simply don't know any better. A junior engineering team might build a complex feature without understanding the design patterns required to scale it.
The resulting code is sloppy and introduces massive operational overhead. Leaders must address this through better training, stricter review processes, and improved engineering efficiency standards.
Even the most talented teams accumulate this debt over time. You might build a brilliant system using the best available practices, but industry standards evolve and user demands shift two years later.
The original design no longer fits the current reality. This impacts codebase health and turns previously modern applications into legacy systems. The result is rising pull request churn as engineers struggle to adapt the old code to new requirements.
The rapid adoption of AI coding assistants fundamentally changes how organizations accumulate risk. AI tools allow developers to generate thousands of lines of code in seconds, so this massive spike in output creates a severe bottleneck downstream.
Human reviewers can't match the pace of the machine. AI doesn't necessarily write bad code, but it dramatically increases code complexity. Developers often accept AI suggestions without fully understanding the underlying logic, and this introduces hidden vulnerabilities.
This dynamic forces human reviewers to spend days deciphering convoluted pull requests. The operational overhead skyrockets, and codebase health deteriorates rapidly. You can't solve this modern friction with legacy metrics.
Engineering leaders can't fix every imperfect line of code. You must treat technical debt reduction as an ongoing resource allocation exercise. According to a 2022 McKinsey report, developers spend approximately 30% of their time managing technical debt1. A 2018 Stripe Developer Coefficient study found that engineers lose up to 17 hours a week to software maintenance and bad code2.
You can't afford that level of waste, so you need a systematic approach to identify which infrastructure debt actually threatens your business. Use this step-by-step guide to evaluate and prioritize your refactoring efforts:
You might track a drop in sprint velocity, but that metric alone doesn't reveal the root cause of the slowdown. A common leadership mistake is tracking metrics without contextualizing the underlying workflow bottlenecks.
A single complex pull request can cause severe code review delays, which blocks multiple engineers and creates a cascading delay across cross-team dependencies. You must perform a root cause analysis to understand exactly where the friction lives. Connecting code complexity directly to cycle time delays gives you the objective data needed to prioritize fixes before they derail your release schedule.
Engineering leaders struggle to justify debt to non-technical stakeholders because they lack objective data connecting code quality to business outcomes. Fragmented data across Jira and GitHub erodes trust in the boardroom. You are left relying on intuition rather than concrete signals to defend your resource allocation.
Standard frameworks and Agile methodologies provide signals of a slowdown, but they don't provide an understanding of the underlying causes when operating at scale. To properly evaluate operational friction and justify refactoring, leaders must implement an operational intelligence layer.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
Everyone who touches the product lifecycle shares responsibility for it. Product managers create debt when they push unrealistic deadlines without consulting engineering constraints. Developers create it when they skip technical documentation or ignore established coding standards.
Leadership ultimately owns the debt because they control the culture and the budget. You must foster an environment where engineering efficiency balances perfectly with speed to market. When you treat debt as a shared business reality, teams can openly discuss tradeoffs without fear of blame.
You can't walk into a board meeting and ask for a month to clean up bad code. You must frame the initiative around risk mitigation and delivery tradeoffs. Follow this step-by-step guide to build a compelling executive case:
Understanding these patterns gives you a clear framework for your next resource planning session. You no longer have to wait for a major outage to address technical entropy. You can monitor codebase health continuously and catch bit rot before it impacts your customers.
Start by auditing your current reporting systems to see if they actually explain why performance is changing. Move away from manual data aggregation and implement an intelligence layer that connects code complexity to delivery outcomes. This shift allows you to stop reacting to delayed releases and start driving predictable execution across your entire engineering organization.
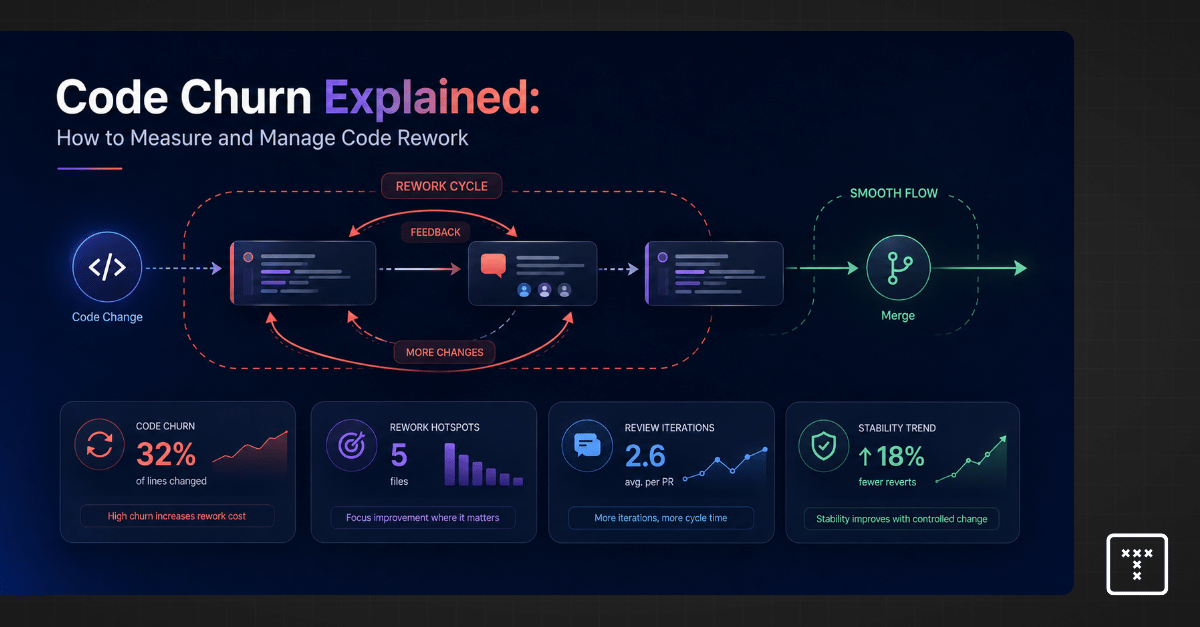
Code churn refers to the percentage of a developer's code that gets rewritten, modified, or deleted shortly after being written. Teams typically measure this within a strict 3-week timeframe. If an engineer writes a function and rewrites it two days later, that action is code churn.
When you ask what is code churn, the answer lies in your version control systems. These systems track the exact lines added, modified, and deleted before code reaches production. High churn over a short period indicates that the code was not stable upon its first commit.
You calculate churn code by dividing the number of lines modified or deleted within a specific period by the total number of lines added during that same period. You then multiply the result by 100 to get a percentage.
Here is how you calculate code rework step by step:
Keep in mind that commit frequency alone doesn't equal churn. A developer might commit frequently to save progress without rewriting the same lines of code.
Code churn isn't inherently bad. It is a natural part of the software development lifecycle. The goal is not to eliminate it, but to differentiate healthy prototyping from destructive rework.
Healthy churn happens during the initial design phase when engineers iterate on complex problems. Destructive rework happens when developers constantly rewrite code due to unclear requirements or accumulating technical debt. This unhealthy behavior creates workflow bottlenecks that delay delivery.
Consider a scenario where a team is updating an aging payment gateway. Working with legacy code naturally requires trial-and-error coding. A developer submits a pull request, and the reviewer requests multiple architectural changes because the original product requirements were vague.
The developer spends the next four days rewriting the same 500 lines of code. This is review churn. It isn't a developer defect, but a systemic issue caused by poorly defined upstream requirements. The engineering effort is wasted, so the entire sprint slows down.
A 5% churn rate is exceptionally low and generally indicates a highly stable, well-understood codebase. Industry research from LinearB1 suggests that a healthy churn threshold sits around 20% for most engineering teams. Appfire2 confirms that exceeding this limit often points to systemic process failures rather than individual coding errors.
But a single baseline doesn't apply universally. A team building a new product from scratch will naturally see higher churn than a team maintaining an established application. You must establish a baseline based on historical engineering metrics for each specific project. If a team's baseline is 15% and it suddenly spikes to 40%, you have a clear signal that sprint velocity is about to drop.
A sudden spike in code rework is a symptom of a deeper operational failure. You must perform a root cause analysis to understand why engineers are rewriting their work. If you ignore the underlying issues, you will see an increase in software bugs and a massive slowdown in cycle time.
Common drivers of destructive rework include:
Last quarter, a core delivery team saw their pull request review churn spike by 40%. The dashboard highlighted the developers as the problem, but the real issue was shifting requirements from product management. The developers were building features based on vague tickets.
When reviewers finally saw the code, they requested massive architectural changes to align with the actual business goals. These communication breakdowns force developers to rewrite working code. This constant rework inevitably leads to developer burnout and severely damages your overall delivery predictability.
Engineers sometimes dive into a problem without a clear architectural plan. This trial-and-error coding results in massive rewrites before the code even reaches the review stage. The issue often stems from failing to apply SOLID design principles early in the process.
When code complexity is high, every new addition breaks existing functionality. Developers have to constantly rewrite their logic to force the new code to fit. You can fix this by enforcing technical design documents before any coding begins.
Avoid using code churn as an individual performance punishment tool because high churn is a systemic workflow diagnostic rather than a developer defect.
You can identify these bottlenecks by tracking your workflow behavior through these steps:
Generative AI is fundamentally altering how software is built. AI coding tools increase raw output, but they often severely bog down review cycles. Developers can generate hundreds of lines of AI-generated code in seconds. This creates an illusion of high productivity.
But this code often contains hidden complexity and massive code duplication. Reviewers have to spend hours untangling the logic, and they frequently force the original developer to rewrite the entire section. This drives up your review churn and creates a massive bottleneck.
Industry frameworks like DORA metrics are excellent tools for measuring engineering performance. They provide valuable signals about speed and reliability. But these metrics only tell you that your cycle time dropped or your defect rate increased. They don't tell you why the change happened.
To manage the influx of AI-generated code and protect your delivery predictability, you need more than passive reporting. You need an operational intelligence layer that connects codebase health directly to delivery risk.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert AI agents to guide execution decisions.
This continuous intelligence allows you to differentiate between human-written and AI-generated code churn. You catch delivery risk before it gets merged, ensuring your execution stays aligned with your planning.
You can't improve what you don't understand. When you reduce destructive rework, you directly improve your delivery predictability. Teams stop wasting engineering effort on endless review cycles and start shipping reliable features on time.
You must stop treating engineering metrics as a retroactive scorecard. Delivery failures are system issues rather than developer defects. You need to use operational intelligence to catch workflow bottlenecks in real time. This approach restores trust in your reporting and gives you the confidence to allocate resources effectively.
Change failure rate (CFR) measures the percentage of code deployments that result in a failure in production. The goal is to track how often your team pushes code that requires immediate remediation.
This metric serves as a critical counterbalance to deployment frequency. Optimizing strictly for speed often damages quality, so tracking failures ensures your team maintains system stability while shipping features faster. Engineering leaders use this DORA change failure rate signal to balance the inevitable tradeoff between quality versus speed.
Calculating this metric requires standardizing what counts as a deployment and what counts as a failure. You must define these terms consistently across your incident response tools and code repositories.
To calculate change failure rate, use this formula:
(Number of Failed Changes / Total Number of Changes) × 100
Industry benchmarks categorize engineering teams into performance tiers based on their ability to ship code reliably. According to the 2023 Accelerate State of DevOps Report by Google Cloud, you can measure change failure rate against these established standards to gauge your baseline delivery health.
Most engineering leaders limit the definition of failure strictly to hotfixes and rollbacks. This narrow scope misses the broader picture of system degradation.
If a deployment introduces massive technical debt or causes degraded service that doesn't trigger a critical alert, your dashboard will still show a success. This forces leaders to rely on intuition because incomplete data undermines the credibility of engineering reporting. Redefining failure for the modern era means looking at the entire workflow rather than just the final production state to capture the true cost of service patches.
Modern software delivery systems experience friction long before a catastrophic outage occurs. You must expand your definition of failure to capture the hidden costs of code delivery.
A dashboard can easily show an Elite status while your team is actually dealing with high pull request churn. This happens when teams game the metric or pollute the data with inconsistent definitions.
One common mistake is including fix-only deployments in the denominator of your calculation. If you push five hotfixes to resolve a single incident, counting those fixes as new deployments artificially lowers your failure rate. Another pitfall involves poor incident attribution, where third-party cloud outages are counted against internal team performance. These practices create a false sense of stability that operational intelligence must correct to restore trust in your reporting.
Executives must ensure their teams map incidents accurately across the software delivery lifecycle. Messy data makes it impossible to identify root causes and delays critical decision-making.
The rapid adoption of AI coding tools fundamentally changes how we measure delivery risk. These tools drastically increase developer output, so teams write and submit code faster than ever before. Yet this sheer volume of artificial intelligence-generated code contributions introduces unseen complexity into your repositories.
Downstream reviewers simply can't keep up with the flood of new pull requests. This imbalance creates severe review fatigue, where engineers lose the capacity to deeply inspect code for architectural flaws or long-term maintainability issues. The code compiles and passes basic tests, but the underlying structural health of the system degrades quietly.
Unmanaged complexity builds up in your repositories and creates massive workflow friction during the review stage. When a dense, highly complex pull request sits in review for days, engineers eventually rubber-stamp the approval just to clear their queues.
That code merges, sits in the pipeline, and fails days later in production. You then spend valuable engineering cycles on bug prioritization instead of shipping new features. The failure looks like a sudden event on your dashboard, but the root cause was the hidden complexity that bottlenecked your workflow days earlier.
Measuring a failure after it hits production is fundamentally a lagging indicator. Industry frameworks provide useful signals about your software delivery performance, but they don't provide an understanding of why that performance is changing. You need to know where risk enters your system before the code ships to production.
TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it's changing, and how to respond. It connects data across company systems, interprets performance through operational intelligence, and uses domain-expert artificial intelligence agents to guide execution decisions.
By surfacing hidden risks like review fatigue, code anomalies, and workflow bottlenecks during the actual code review process, TargetBoard allows you to neutralize the root causes of failure before they merge. This shifts your posture from reactive reporting to proactive delivery confidence, ultimately driving true engineering efficiency.
You can actively prevent production failures by changing how your team handles code before it reaches the main branch. Aligned with the foundational Continuous Delivery principles established by industry experts like Jez Humble and Martin Fowler, shifting quality checks left is critical.
Pushing for speed without guardrails creates severe systemic tradeoffs. You must balance how fast you ship with how well your system actually runs.
Requires connecting cross-system data to accurately predict where failures will occur.
Redefining failure requires you to look beyond standard production deployments and measure the friction happening inside your daily workflows.
Your dashboard is only as valuable as the decisions it enables. Passive metrics show you what broke, so you must adopt active operational intelligence to see why it broke. Understanding these patterns gives you a clear framework to improve engineering efficiency and ensure long-term delivery predictability. Moving away from lagging scorecards allows you to scale your software delivery performance safely and build trust with your board.