Quick Answer: Platform engineering is the discipline of designing and building self-service workflows to minimize cognitive load for developers.
At its core, an internal developer platform provides:
This approach allows stream-aligned teams to ship code faster without managing underlying operational complexities.
Engineering departments often confuse these roles, and defining clear boundaries is critical for resource allocation. Platform engineers build the paved roads, and DevOps philosophies influence how those roads operate. Without a dedicated platform team, developers often get stuck managing shadow operations instead of writing product code.
Treating the internal developer platform as a mandatory IT project often leads to poor adoption. The Platform as a Product mindset shifts this approach by treating developers as actual customers. Key characteristics include:
The demand for the platform engineering discipline has surged because organizations are struggling to manage the AI impact on software delivery. Developers use artificial intelligence to generate massive volumes of code rapidly, so raw output metrics look incredibly high. But this AI-generated code often introduces hidden complexity and technical debt into the codebase.
Reviewers are forced to spend days validating auto-generated logic. This creates massive workflow friction where code writing is fast but merging is painfully slow. Platform engineering teams are now essential for building the guardrails needed to manage this code surge without sacrificing delivery predictability.
When developers submit highly complex pull requests generated by artificial intelligence, human reviewers can't process them efficiently. This mismatch causes severe workflow bottlenecks that directly inflate cycle time. Pull request churn increases as reviewers request continuous changes to understand the automated logic.
This rework and duplication stall progress across the entire department. When one stream-aligned team gets stuck in an endless review cycle, cross-team dependencies break down. You can't forecast delivery timelines accurately when massive code outputs sit unmerged in fragmented systems.
Platform engineering directly shapes software delivery performance by removing the operational hurdles that slow teams down. A well-designed platform improves execution predictability by:
Golden paths are highly opinionated, supported approaches for building and deploying software. By standardizing these paved roads, platform teams achieve specific outcomes:
Security checks often act as a massive roadblock right before a product launch. Relying on manual approvals and traditional ticket ops forces developers to wait days for a security review, and this actively delays critical releases. Platform engineering solves this by embedding security and compliance guardrails directly into Continuous Integration and Continuous Deployment pipelines.
Developers receive immediate feedback on vulnerabilities while they are still writing code. This shifts security left and eliminates the late-stage friction that frustrates stream-aligned teams.
To evaluate delivery tradeoffs and manage resource allocation effectively, engineering leaders rely on a structured approach to building platforms. According to the Cloud Native Computing Foundation (CNCF) framework, a robust platform requires specific functional areas to operate smoothly^1. These six pillars form the foundation of a predictable delivery system.
A self-service portal provides a single interface for developers to access tools and documentation without filing IT tickets. This centralization reduces context switching so teams can ship features faster.
This pillar automates the setup of cloud resources and deployment environments. You must clearly delineate between basic infrastructure orchestration, which just spins up servers, and advanced operational intelligence, which monitors how efficiently those systems support delivery.
Standardized pipelines govern how code moves from a local commit to a production deployment. Platform teams build these automated routes to ensure every stream-aligned team follows the same reliable path to production.
Automated security checks run in the background to prevent vulnerable code from advancing. This eliminates the need for manual security reviews right before a critical launch.
Observability tools provide real-time visibility into application health and infrastructure performance. If a deployment causes an issue, the platform automatically flags the root cause so developers can resolve it immediately.
Platform teams must track adoption rates and identify workflow bottlenecks to continuously improve the platform. This data proves whether the internal developer platform is actually reducing friction or just shifting the burden to a different system.
Problem: CTOs and engineering leaders often rely on subjective developer surveys or standard engineering metrics to gauge success. These metrics provide useful signals, but they fail to explain why performance is changing or where hidden workflow bottlenecks live within data silos.
Solution: You need an operational intelligence layer to connect fragmented data and track the actual business impact of your platform. TargetBoard is an agentic operational intelligence platform that helps leadership teams understand how execution is performing, why it is changing, and how to respond.
It connects data across company systems and uses domain-expert artificial intelligence agents to guide execution decisions. Instead of looking at a static dashboard showing an unexplained drop in velocity, TargetBoard surfaces the exact workflow friction causing the delay so you can act immediately and improve system-level visibility.
Tracking engineering effectiveness requires a mix of output metrics and deep execution signals. You must measure how fast work moves and understand the context behind those movements to drive predictable delivery outcomes.
Standard DevOps Research and Assessment frameworks measure critical aspects of software delivery performance. They are excellent supporting signals for your organization. But they don't provide system-level visibility into why a team missed a deadline or why a specific repository is suddenly generating massive technical debt.
Consider the edge case where auto-generated code introduces hidden structural complexity. Standard delivery metrics entirely miss this technical debt until it causes a production incident months later. To truly measure engineering effectiveness, you must transition to operational intelligence that connects signals across planning, code, and delivery systems.
According to Gartner research, most software engineering organizations will establish platform engineering teams by 2026^2. But the platform engineering discipline requires internal cultural shifts and disciplined adoption. It's never just about purchasing software and hoping for a productivity spike.
Referencing Team Topologies provides a strong structural foundation for designing successful platform teams that interact smoothly with the rest of your engineering department^3. When you combine a well-structured platform team with proactive operational intelligence, you stop reacting to stale data. You gain the execution predictability needed to lead with complete confidence.
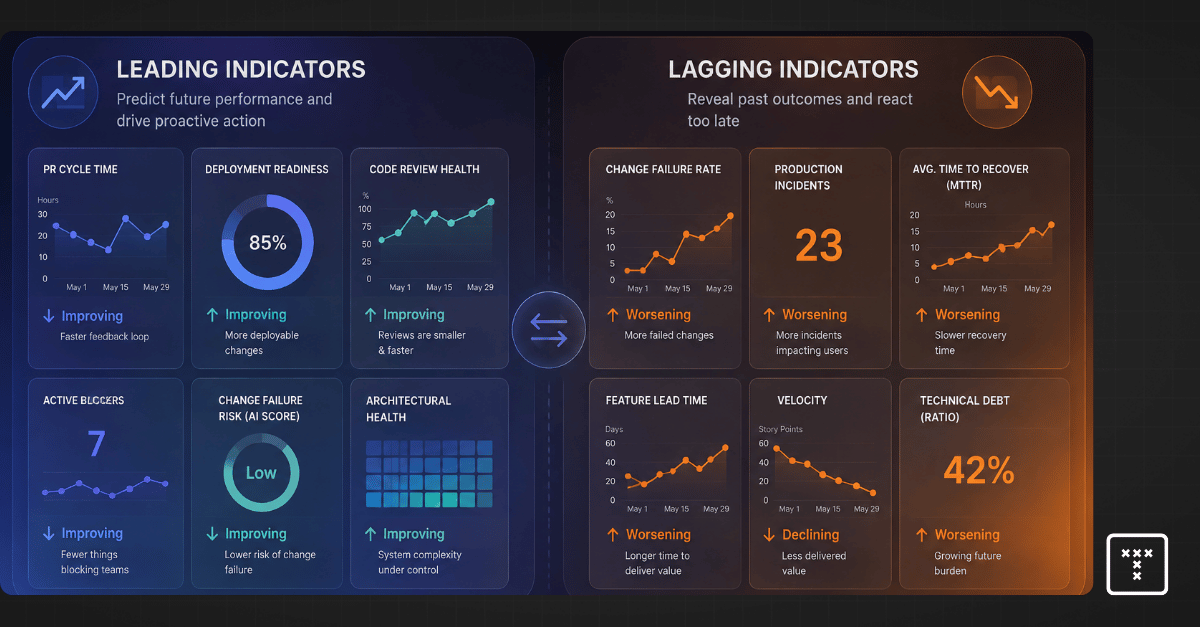
Leading and lagging indicators are the two primary data categories used to evaluate engineering performance. Lagging indicators measure the final results of a process after it concludes. Leading indicators measure the upstream activities and inputs that predict those future results.
Think of this dynamic through the classic windshield versus rearview mirror analogy because it clarifies how you use the data to make decisions. Leading indicators are forward-looking metrics that act as your windshield, helping you anticipate the road ahead. Lagging indicators are backward-looking metrics that serve as your rearview mirror, showing you exactly where you have been. You need both, so you can make accurate execution decisions.
You can quickly audit your current reporting dashboards to evaluate leading versus lagging indicators. Ask these diagnostic questions to determine if your data provides actionable insights or just a historical record:
Investopedia and standard corporate glossaries focus on marketing or sales data when defining leading and lagging indicators. Engineering executives need specific engineering performance metrics mapped to the software delivery lifecycle.
Lagging indicators confirm the final results of the software delivery lifecycle. They are essential for aligning engineering efforts with broader business outcomes. These metrics tell you if a project shipped on time or if a release met quality standards.
Platform engineering teams also track coincident indicators, which measure activity happening right now. The core value of a lagging indicator remains its definitive proof of past performance. Common examples include total bugs found in production and final release frequency.
Leading indicators highlight the friction points happening right now that will inevitably impact your final delivery metrics. These signals allow you to intervene early. If you track Pull Request size and complexity, you can predict which code reviews will stall.
High review churn acts as a clear warning sign, often predicting technical debt and poor code quality. Monitoring cross-team dependencies helps you spot coordination bottlenecks before they derail an entire release timeline. Managing these inputs gives you direct control over the eventual outcomes.
Standard measurement frameworks provide valuable signals about overall organizational health, but they lack the operational understanding needed to drive daily execution. CTOs and VPs of Engineering have experienced the frustration of presenting stalled delivery metrics to a board while their dashboard shows green across the board. Delivery can suddenly halt despite good past metrics because standard tools lack systemic visibility. They force you into a state of reactive management.
This gap becomes critical when teams introduce AI-generated code into their workflows. AI tools dramatically increase code output volume, which creates a false sense of speed. That sheer volume introduces hidden complexity and massive review bottlenecks that standard frameworks fail to catch until cycle time completely collapses. Output volume isn't the same thing as delivery predictability.
You can't manage a modern engineering organization by looking at outcomes alone. You must establish a clear cause-and-effect relationship between your daily engineering activities and your final business results.
Tracking both lead and lag indicators allows you to perform root cause analysis in real time. If you see a predictive signal flashing red, you can course-correct before the sprint fails. According to the 2023 Forrester Research report on engineering operations, teams that actively monitor upstream workflow friction achieve significantly higher delivery predictability than teams tracking only final deployment rates.
Engineering executives know they must track predictive signals to prevent delivery failures. The reality is that manually piecing together fragmented data across tools like Jira and GitHub to compare lagging vs leading indicators is completely unsustainable. You often end up with conflicting signals where Jira shows a project on track while GitHub shows massive review delays.
To truly act on predictive signals, leaders need a system that automatically connects cross-system workflow behavior to delivery metrics to explain why performance is changing. This requires an evolution from passive observation to active intervention.
By unifying this fragmented data, an operational intelligence layer gives you the context needed to make confident execution decisions. You stop relying on stale reports and start managing the actual flow of work.
Understanding the difference between outcome metrics and predictive signals changes how you run your engineering organization. You gain the ability to measure and manage performance based on operational reality rather than retrospective reporting.
This approach gives you a clear framework for technical risk mitigation and smarter resource allocation. By monitoring workflow friction early, you protect your long-term maintainability rather than waiting for a North Star Metric to drop at the end of the quarter. You stop reacting to missed deadlines and start actively guiding your engineering systems toward predictable and sustainable delivery.
Engineering analytics is the practice of analyzing data from the software development pipeline to understand and improve software delivery performance. It connects fragmented data points across issue trackers and code repositories to give leaders systemic visibility.
The goal is to move beyond simply measuring output and start governing the entire delivery system. This continuous evaluation of engineering metrics helps organizations identify bottlenecks and align daily work with strategic business outcomes.
Search results often mix these two distinct concepts. Analytics engineering is a specific job title within the modern data stack. These professionals build and maintain the data pipelines that data scientists use for business intelligence.
Engineering analytics is an operational discipline used by technical executives. VPs of Engineering and CTOs use this discipline to monitor workflow bottlenecks and maintain delivery predictability.
Imagine staring at a dashboard on Friday afternoon during a critical delivery cycle. Deployment frequency looks healthy, yet lead time for changes has doubled. Your engineering managers spent hours dealing with manual reporting overhead to build this view, but the dashboard can't explain the root cause of the delay.
This highlights the fundamental problem with passive reporting. Dashboards give you metrics without context. They show a snapshot of past performance but offer zero actionable insights to resolve the workflow friction. Analytics requires an operational intelligence layer to interpret those signals and guide your response.
Understanding the evolution of data maturity helps clarify why dashboards fall short. The industry breaks analytics into four operational stages.
AI coding tools are fundamentally changing how work is produced. They accelerate initial output, so developers ship more volume in less time. Traditional developer productivity frameworks look at this spike in velocity and assume the system is highly efficient.
But this volume introduces massive hidden complexity. The difference between AI-generated code vs. human-written code often shows up during the review phase. An AI tool might write a feature in ten minutes, but that high-complexity pull request can sit in review for four days. Human reviewers struggle to validate the dense logic, creating severe workflow friction.
The deployment metrics look temporarily inflated, yet technical debt quietly accumulates in the background. The delivery system slows down over time as developers spend hours untangling complex PRs instead of writing new features. You can't manage this new reality with basic dashboards because they measure the speed of creation while completely missing the downstream cost of code review.
The core issue is no longer a lack of visibility. Jira and GitHub provide enough raw data to achieve system-level visibility, yet engineering leaders still lack objective understanding. You need a reliable way to turn conflicting metrics into clear execution decisions without relying on manual analysis or guesswork.
TargetBoard is an agentic operational intelligence platform that connects data across company systems, interprets performance continuously, and uses domain-expert AI agents to guide execution decisions. It automatically interprets fragmented data across your tools to uncover hidden issues like PR churn.
This intelligence layer surfaces decision-ready insights for leaders. You can restore delivery predictability and identify bottlenecks objectively, allowing your teams to stop reacting to stale reports and start addressing workflow friction as it happens.
VPs of Engineering mistakenly treat deployment metrics as a complete measure of developer productivity rather than just a starting signal. According to the 2023 DORA report, elite performing teams prioritize delivery predictability and system reliability alongside raw speed. Frameworks like DORA metrics and the SPACE framework provide valuable benchmarks for these outcomes.
But these frameworks don't provide systemic understanding. They tell you that a metric shifted, yet they can't isolate the root cause behind the shift. You need an active intelligence layer to connect those framework signals to actual workflow behavior.
Real execution decisions happen when you connect data to specific workflow bottlenecks. Consider a sprint where cycle time spikes by 40 percent. A basic dashboard simply reports the delay, but operational intelligence reveals the actual mechanics.
According to 2023 industry benchmarks from LinearB, pull request review time accounts for 70 percent of delivery delays. In this scenario, three high-complexity pull requests sat in review for over four days due to cross-team dependencies, directly causing that 40 percent cycle time spike. Identifying pull request (PR) churn at this granular level allows you to reallocate senior engineers to clear the backlog immediately.
Selecting the right platform requires evaluating how well it moves your organization from reactive reporting to proactive governance. Modern engineering analytics systems and engineering analytics tools fall into three primary categories. You need a unified source of truth to manage complex delivery pipelines effectively.
Relying on output metrics alone creates a false sense of security, especially when AI tools inflate short-term velocity. True organizational improvement requires understanding how work flows through your entire delivery pipeline. Shifting from passive dashboards to operational intelligence gives you the context needed to drive execution alignment.
Understanding these patterns gives you a clear framework for your next resource allocation decision. You can stop reacting to delayed reports and start managing delivery predictability proactively.